
Data standardisation converts raw, inconsistent source data into a uniform format so that every downstream system — matching engine, analytics platform, CRM, or ERP — reads the same value the same way. Done properly, it reduces fuzzy matching error rates by 30 to 50 percent and cuts deduplication false-positive rates by roughly the same margin. This guide covers the seven-stage standardisation pipeline, the most common field-type problems, and how to automate the process at enterprise scale.
Start a free trial of Match Data Pro and run your first standardisation job on live data today.
Why Data Standardisation Fails Without a Pipeline
Most teams treat standardisation as a one-time clean-up task. They write ad hoc scripts to fix a date format here, capitalise a name field there, and move on. The problem is that new dirty data arrives every day. Without a repeatable, automated pipeline, the work compounds.
The root cause is source diversity. A typical enterprise CRM holds records from web forms, CSV imports, manual entry, and third-party data appends. Each source applies different conventions:
- Dates:
01/15/2024,2024-01-15,Jan 15, 2024,15-Jan-24 - Phone numbers:
(602) 555-0100,6025550100,+1-602-555-0100,602.555.0100 - Company names:
Acme Corp,ACME CORPORATION,Acme Corp.,Acme - State codes:
Arizona,AZ,az,Ariz.
None of these pairs will match on an exact join. Even a fuzzy match engine will score them poorly if the input format differs wildly from the reference record. Standardisation must precede matching, not follow it.
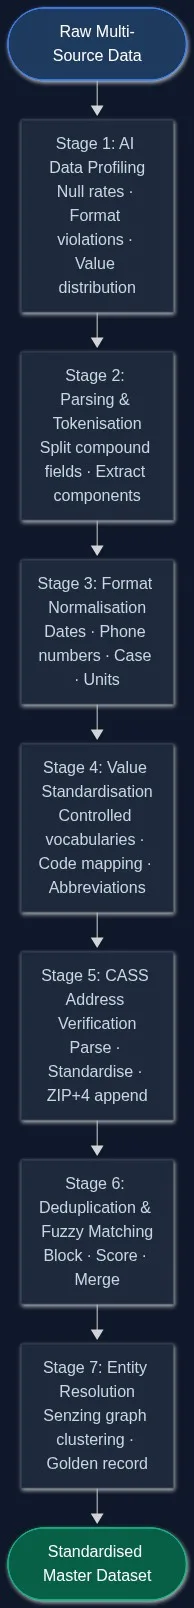
A repeatable pipeline — not a one-off script — is the only answer. The seven stages below define that pipeline. Each stage feeds the next, and all seven can be automated through a platform like Match Data Pro’s data cleansing engine.
The Seven-Stage Data Standardisation Pipeline
Stage 1: AI Data Profiling
Before you standardise anything, profile the data. AI data profiling scans every field and returns null rates, format distribution, value frequency, and anomaly flags. For a dataset of one million records you need to know that 23% of phone numbers are in a non-standard format before you write a normalisation rule — not after the pipeline fails.
Profiling output drives every subsequent stage. It tells you which fields need parsing, which need code mapping, and which are clean enough to pass through.
Stage 2: Parsing and Tokenisation
Compound fields must be split before individual components can be standardised. A single name field containing Dr. James R. Wilson Jr. needs to yield: prefix (Dr.), first (James), middle (R.), last (Wilson), suffix (Jr.). Addresses stored as a single string need to yield street number, street name, unit suffix, city, state, and postal code as separate tokens.
Parsing errors at this stage corrupt every downstream step. A unit suffix like APT 3B left inside the street name field will cause a CASS verification failure and a fuzzy match miss.
Stage 3: Format Normalisation
Format normalisation applies deterministic rules to convert every value to the target format. Common targets:
- Dates: ISO 8601 (
YYYY-MM-DD) for storage; display format applied at the UI layer - Phone numbers: E.164 (
+16025550100) for international comparisons; a 10-digit stripped format for domestic deduplication - Case: title case for person names (
James Wilson); uppercase for state codes and country codes (AZ,US) - Units: convert
sq ft,square feet, andsqftto a single canonical token before comparing property records
These rules are field-type-specific. A regex that works on US phone numbers will break on international numbers. Build your normalisation rules against the actual format distribution the profiler found in Stage 1.
Stage 4: Value Standardisation
Format normalisation handles structure. Value standardisation handles meaning. The goal is to map variant terms to a controlled vocabulary.
Examples:
VP of Sales,Vice President Sales,VP-Salesall map toVP SalesLLC,L.L.C.,Limited Liability Companyall map toLLC- Industry codes:
SaaS,Software as a Service,Cloud Softwarecan map to a canonical NAICS code - Country names:
USA,United States,US,U.S.A.all map toUS
Value standardisation is where data standardisation best practices differ most by domain. Healthcare needs SNOMED and ICD-10 mappings. Financial services needs LEI and BIC code resolution. Marketing operations needs job title and company type normalisation.
Stage 5: CASS Address Verification
Address data degrades at roughly 10 to 15 percent per year as people move, businesses close, and postal routes change. Format normalisation is not enough for addresses. You need USPS CASS certification, which parses, standardises, and verifies every address against the postal database — appending the ZIP+4 extension that uniquely identifies a delivery point.
CASS address verification in Match Data Pro processes addresses in batch or via real-time API. The output is a standardised address in USPS format with a deliverability flag. Undeliverable addresses are flagged for review rather than silently passed through.
ZIP+4 append is especially important for deduplication. Two records with identical street addresses but different ZIP+4 codes may refer to different units in the same building. Without the extended code, they merge incorrectly.
Stage 6: Deduplication and Fuzzy Matching
Standardised data is prerequisite input to deduplication. Once every record uses the same date format, phone format, and address structure, blocking keys become far more selective. A blocking key on last_name[0:3] + zip5 will produce tight candidate pairs from clean data. The same key on unstandardised data will produce either massive over-blocking (too many pairs to score) or under-blocking (missed duplicates).
Match Data Pro’s AI-powered fuzzy matching engine applies configurable Jaro-Winkler, Levenshtein, phonetic, and token-based algorithms across candidate pairs after standardisation. The match score improves materially because the input strings are already in a comparable form. A score threshold of 0.85 on standardised data typically outperforms a threshold of 0.90 on raw data.
Stage 7: Entity Resolution
The final stage uses entity resolution to cluster matched records into a single golden record. Match Data Pro integrates Senzing’s graph-based entity resolution engine, which builds an identity graph across all matched pairs and applies survivorship rules to select the best field value from each source record.
The output is a master dataset where every entity — customer, supplier, patient, property — appears exactly once, with the most authoritative value for each field. That master dataset feeds your CRM, ERP, analytics warehouse, or AI model with data that is both standardised and deduplicated.
Field-Type Standardisation: Common Edge Cases
Name Fields
Person name standardisation is deceptively hard. Consider these variants of the same record:
ROBERT J SMITH(all caps import)Bob Smith(nickname in web form)Smith, Robert(last-name-first CRM export)R. Smith(abbreviated first name)
A standardisation pipeline that tokenises, cases, and expands common nicknames (Bob to Robert, Bill to William) before fuzzy matching will link all four. Without that expansion, only exact or near-exact strings match. Nickname expansion tables are configurable in Match Data Pro’s cleansing rules library.
Company Name Fields
Legal entity suffixes (Inc, LLC, Ltd, GmbH) are high-noise tokens for matching. Strip them before scoring, then restore from the survivorship winner. Similarly, punctuation in company names (AT&T vs ATT vs At&T) needs normalisation before the token matching step runs.
Date Fields
Date field errors fall into three categories: format variation (solved by normalisation), ambiguous two-digit years (1924 vs 2024 — context-dependent), and impossible dates (2023-02-30 — flag for review). Match Data Pro’s AI profiling flags impossible dates as anomalies before the normalisation rule runs, preventing silent corruption.
Automation: Job Scheduling and Incremental Processing
A standardisation pipeline that runs once is a project. One that runs continuously is a program. Match Data Pro’s job automation layer lets you schedule full or incremental standardisation runs against any connected data source — Salesforce, HubSpot, SQL Server, MySQL, flat files, or any source reachable via the import/export connector library.
Incremental processing is essential for large datasets. A one-million-record CRM does not need a full re-standardisation run every night. Only the records that changed since the last run need processing. Match Data Pro tracks change timestamps and processes only the delta, cutting nightly run times from hours to minutes.
Alert thresholds can trigger notifications when new data exceeds a format violation rate — for example, if more than 5 percent of incoming phone numbers fail the E.164 normalisation rule, that signals a source-system format change that needs investigation upstream.
Ready to automate your standardisation pipeline? Schedule a demo and we will walk through a live job against your data source.
Standardisation Across Systems: Cross-Source Challenges
Multi-source standardisation adds a layer that single-source projects do not face: field semantics that differ by system. A status field in Salesforce might store Active while the same concept in the ERP stores 1 and in the marketing platform stores opted_in. Standardisation requires not just format rules but cross-system semantic mappings.
Build a data dictionary that maps each source field to a canonical field name and value set before the pipeline runs. That dictionary becomes the configuration layer for Match Data Pro’s standardisation rules. It also serves as the documentation artefact that governance and compliance teams require.
Data integration projects that embed standardisation inside the ETL pipeline — rather than treating it as a pre-load step — produce consistently cleaner target systems. Every record passing through the pipeline is validated and standardised before it reaches the destination table.
Frequently Asked Questions
What is data standardisation and why does it matter?
Data standardisation converts values across all source systems to a consistent format, vocabulary, and structure. It matters because matching, deduplication, and analytics all depend on comparable inputs. Inconsistent formats cause missed matches, inflated duplicate counts, and unreliable aggregate metrics. Teams that standardise before matching typically see 30 to 50 percent fewer false positives.
What is the difference between data standardisation and data cleansing?
Data cleansing is the broader process that includes correcting errors, removing invalid records, and fixing data quality issues. Data standardisation is a specific stage within cleansing that converts valid but inconsistently formatted values to a uniform target format. Cleansing covers what is wrong; standardisation covers what is inconsistent.
How does data standardisation improve fuzzy matching accuracy?
Fuzzy matching algorithms score string similarity. When inputs are in inconsistent formats, the same entity produces vastly different strings, and similarity scores drop below match thresholds. Standardising to a common format before scoring means the algorithm compares James Wilson to James Wilson rather than JAMES WILSON to Wilson, James. That closes the similarity gap and raises match confidence reliably.
Can data standardisation be fully automated?
Yes, with the right platform. Match Data Pro automates profiling, parsing, format normalisation, value standardisation, address verification, and job scheduling without manual scripting. Rules are configured once and applied to every new record on ingestion. The main human input is defining the target formats and controlled vocabularies — the pipeline execution itself is fully automated and schedulable.
How often should a data standardisation pipeline run?
High-volume CRM and ERP environments typically run incremental standardisation nightly, processing only records that changed since the last run. Marketing databases with weekly list imports run standardisation on import. Real-time use cases — web form ingestion, API data feeds — need standardisation at point of entry via a live API call. The right frequency depends on your data velocity and downstream latency tolerance.
Start a free trial of Match Data Pro and standardise your first dataset in hours — no contract, no infrastructure setup required.