
AI workflows can run reliably inside air-gapped or network-isolated environments — but only when the underlying data is clean, deduplicated, and correctly structured before processing begins. Regulated industries including defence, government, healthcare, and financial services increasingly run AI-assisted analysis on sensitive data that cannot leave a controlled perimeter. The challenge is not the AI model itself; it is the data quality pipeline that must operate entirely offline, without cloud-based API calls or external data enrichment services. Enterprise data cleaning workflows that work inside isolated environments require the same capabilities as cloud deployments: profiling, standardisation, fuzzy matching, entity resolution, and job automation — all running within the perimeter.
Ready to run structured data quality workflows inside a secure perimeter? Start a free trial of Match Data Pro to evaluate the full pipeline on your own data.
What Makes an Environment Air-Gapped or Network-Isolated?
An air-gapped environment has no connection — physical or logical — to external networks, including the public internet. Network-isolated environments are a softer variant: internal network access is permitted, but external egress is blocked or tightly controlled by firewall policy. Both configurations appear in regulated industries where data sovereignty, classification requirements, or regulatory mandates prohibit data leaving a defined perimeter.
Common examples include:
- Defence and intelligence agencies handling classified records
- Government data centres under FedRAMP High or IL4/IL5 requirements
- Hospitals and health systems where PHI cannot transit public networks
- Financial institutions with strict data residency requirements
- Legal and compliance teams working with sealed or privileged datasets
The defining operational constraint is that every tool in the data quality stack — profiling engine, matching algorithms, entity resolution, address verification, and job scheduler — must run on infrastructure the organisation controls, with no call-outs to external APIs or cloud-hosted licence validation services.
The Data Quality Problem That Breaks AI in Isolated Environments
AI models are only as reliable as the data they process. In regulated environments, this problem is amplified because data quality issues accumulate over long periods without the continuous cleansing pipelines that cloud-connected systems often run as background jobs. When an AI model runs inference on a database with 15% duplicate records, inconsistent name formats, and unverified addresses, the outputs are structurally unreliable — not because the model is wrong, but because the inputs are dirty.
Common data quality failures in regulated data stores
These patterns appear consistently in isolated environments:
- Duplicate entities: “Jonathan Smith” and “Jon Smith” recorded as separate individuals across two intake systems, both linked to different address records. An AI model treating them as distinct entities produces incorrect analytics and false negative identity checks.
- Format fragmentation: Date fields stored as “Nov 12 2026”, “11/12/26”, and “2026-11-12” across three legacy tables. No standardisation means comparison logic fails silently.
- Stale address data: Physical addresses that were valid at record creation but have not been re-verified. CASS certification verifies deliverability; without it, location-dependent AI analysis produces skewed results.
- Orphaned records: Entities that exist in one system but not another after a migration, leaving gaps in the AI model’s view of an individual or organisation.
AI data profiling run before any matching pipeline identifies these patterns automatically, flagging field-level completeness rates, format distributions, and duplicate candidate density — all within the perimeter, with no data leaving the environment.
The Pipeline Architecture for Air-Gapped Data Quality
Running a full data quality pipeline inside a network-isolated environment requires a platform that is deployable as a self-contained unit. That means all dependencies — matching libraries, address reference databases, entity graph engine, job scheduler, and UI — must ship with the deployment package. The pipeline stages themselves are identical to a cloud deployment; the difference is infrastructure isolation.
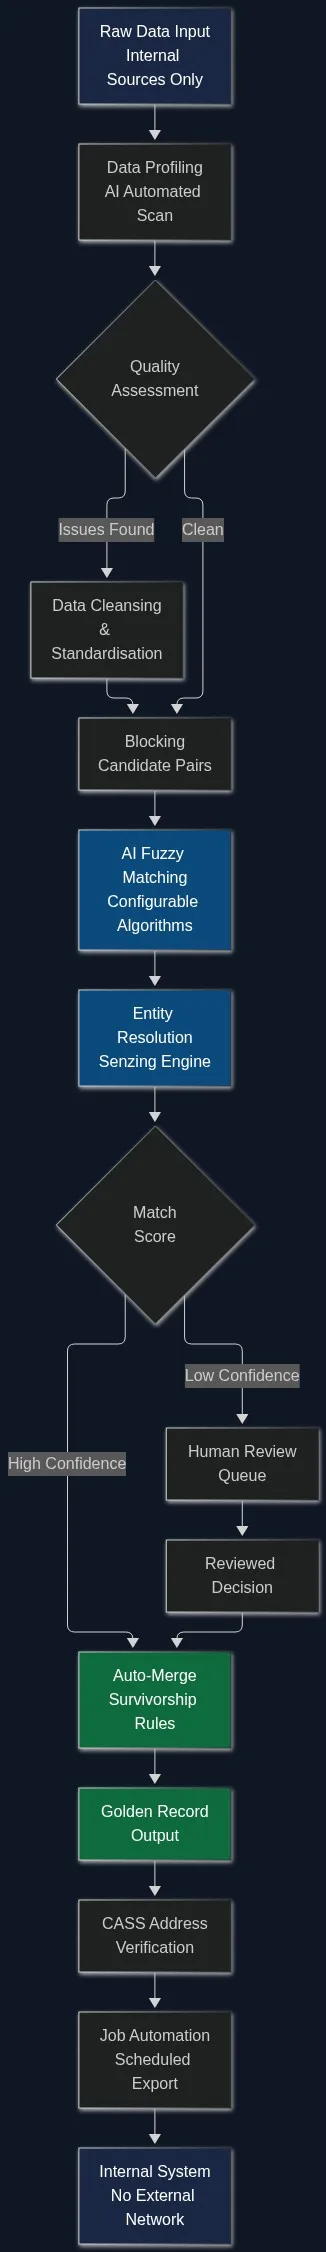
Stage 1: Automated data profiling
Every pipeline run begins with profiling. The profiling engine scans all source tables, scores completeness and consistency per field, identifies format variants, and calculates candidate duplicate density. In an air-gapped environment this scan happens entirely in-memory on the local infrastructure. Match Data Pro’s AI-powered data profiling produces a field-level quality report that drives the downstream cleansing configuration — no manual schema inspection required.
Stage 2: Standardisation and cleansing
Standardisation converts every source field to a canonical format before matching. Names are case-normalised and parsed into components (prefix, first, middle, last, suffix). Dates are coerced to ISO 8601. Phone numbers are stripped to E.164. Company names have legal suffixes normalised: “Inc.”, “Incorporated”, and “Inc” become a single token. Data standardisation at this stage reduces false negatives in the matching phase by 30 to 50 percent, because the algorithm compares clean comparable tokens rather than raw format-inconsistent strings.
Stage 3: Blocking and candidate pair generation
Blocking is the technique that makes large-scale matching computationally feasible. Rather than comparing every record pair (O(n²) comparisons), blocking groups records by shared attributes — first three characters of surname, postal code prefix, year of birth — and only scores pairs within each block. For a 2-million-record dataset, well-configured blocking reduces candidate pairs from 2 trillion to under 50 million, cutting compute time by 97% without sacrificing recall. All blocking logic runs locally.
Stage 4: AI fuzzy matching
Once candidate pairs are generated, AI-powered fuzzy matching algorithms score each pair across every configured field. Match Data Pro applies field-specific algorithms: Jaro-Winkler for name transpositions, Levenshtein edit distance for address line variants, phonetic matching (Metaphone, Double Metaphone) for sound-alike names, and token set ratio for company name matching. Each field score is weighted by its discriminating power. A composite score of 0 to 100 determines routing: above 85 auto-merges; between 60 and 85 routes to review; below 60 is rejected as a non-match.
Example pair scored in an isolated government dataset:
| Field | Record A | Record B | Score |
|---|---|---|---|
| Last name | Rodriguez | Rodrigues | 94 |
| First name | Carlos | Carl | 82 |
| DOB | 1983-04-17 | 1983-04-17 | 100 |
| Address | 142 Oak Ave, NW | 142 Oak Avenue NW | 96 |
| Composite | 91 — Auto-merge |
Stage 5: Entity resolution
Fuzzy matching identifies pairs. Entity resolution clusters those pairs into coherent entities — groups of records that all refer to the same individual or organisation. Match Data Pro integrates the Senzing entity resolution engine, which uses probabilistic graph clustering to handle transitive matches: A matches B, B matches C, therefore A, B, and C belong to the same entity cluster. This runs entirely in-process on local infrastructure with no external graph API calls.
Entity resolution at this stage is what differentiates a basic deduplication run from a production-grade identity resolution pipeline. It is the difference between finding 70% of duplicates and finding 95%.
Stage 6: CASS address verification using a local reference database
CASS address verification validates addresses against USPS postal data and returns standardised, deliverable addresses with ZIP+4 codes. In cloud deployments this is typically an API call. In air-gapped environments, the CASS reference database — updated periodically via approved secure transfer — is loaded locally and queried entirely in-process. The verification output appends a deliverability code (Y/N/S/D) and standardised address components to each record before it enters the golden record.
Stage 7: Survivorship and golden record production
When multiple records are confirmed as the same entity, survivorship rules determine which field values survive into the golden record. Rules are configurable: most recent non-null value wins for contact fields; most complete address wins for location; source system A takes precedence over source B for legal name. The golden record is written to the internal target system with a full audit trail of which source records contributed each field value.
Job Automation in an Isolated Environment
A one-time cleanse is not enough. Regulated data stores receive new records continuously — intake forms, case updates, transaction records. The pipeline must run on a schedule without manual intervention. Automated data cleansing in an air-gapped environment uses an internal job scheduler that triggers pipeline runs on a cron schedule, monitors completion status, writes run logs to an internal audit sink, and alerts operators via internal messaging (email relay or SIEM integration) when error rates exceed configured thresholds.
Match Data Pro’s job automation layer handles all of this natively. Pipeline configurations are stored as versioned JSON job definitions. Operators can schedule full re-runs, incremental delta runs (processing only records changed since the last run), and ad-hoc triggered runs — all without touching the underlying matching configuration.
Import and Export Connectors for Isolated Systems
Getting data in and out of an air-gapped environment requires connectors that work without external network access. Match Data Pro’s import/export connectors support flat-file ingestion (CSV, TSV, fixed-width), database connectors (SQL Server, PostgreSQL, Oracle, MySQL) over local network, and secure file transfer protocols (SFTP over internal network, encrypted file drops on local storage). No data leaves the perimeter. Outputs write directly to internal target tables or secure file locations.
For teams that need to validate a subset of records against an external reference — a one-way approved data transfer — the connector architecture supports staged data handoff: records pass through a data diode or controlled transfer point and are ingested by the internal pipeline on the other side.
What to Evaluate Before Deploying in a Regulated Environment
Not every data quality platform supports isolated deployment. Before selecting a platform for a regulated or air-gapped environment, verify these requirements:
- No external API dependencies at runtime: Licence validation, model updates, and telemetry calls must all be suppressable. Any call-out to an external service is a disqualifier.
- Local address reference database: CASS or other postal verification must ship as a bundled dataset with an offline update mechanism.
- Containerisable deployment: Docker or container-native packaging allows the platform to run on air-gapped infrastructure without internet-connected package repositories.
- Immutable audit trail: Every match decision, merge operation, and pipeline run must be logged locally with tamper-evident controls for compliance reporting.
- Role-based access control: Operators, reviewers, and read-only auditors need separate permission levels without dependence on external identity providers.
Match Data Pro is designed to meet these requirements. The platform ships as a self-contained deployment with all matching libraries, the Senzing entity resolution engine, a local CASS reference database, and an internal job scheduler — with no mandatory external dependencies at runtime. Book a demo to walk through deployment requirements for your regulated environment.
Frequently Asked Questions
Can AI-powered fuzzy matching run without internet access?
Yes. Fuzzy matching algorithms — Jaro-Winkler, Levenshtein, phonetic, token-based — are purely computational and require no external API calls. A platform like Match Data Pro packages all matching libraries locally, so the entire pipeline runs in-process on isolated infrastructure with no network egress required during matching operations.
How is CASS address verification handled in an air-gapped environment?
CASS address verification uses a postal reference database that can be loaded locally and queried entirely in-process. The reference dataset is updated periodically — typically quarterly — through a controlled, approved transfer process. Verification runs against the local reference copy without any internet connection. ZIP+4 standardisation and deliverability codes are generated entirely offline.
What is the difference between air-gapped and network-isolated for data quality purposes?
Air-gapped means physically or logically disconnected from all external networks. Network-isolated means external egress is blocked but internal network access is permitted. For data quality pipelines, both require the same thing: all platform dependencies must be bundled locally. The key operational difference is that network-isolated environments can often use internal database connectors across a LAN, while air-gapped environments may rely on file-based data transfer.
How does entity resolution work without cloud graph services?
Entity resolution engines like Senzing run entirely in-process — the graph clustering logic, probabilistic scoring models, and identity record storage all operate locally. No data is sent to external graph APIs or cloud services. Match Data Pro embeds Senzing as a local engine, so the full entity resolution pipeline — from candidate pair scoring to cluster formation — runs inside the perimeter with no external dependencies.
How do I keep the data quality pipeline current in an environment with no internet access?
Platform updates — including algorithm improvements, reference database refreshes, and configuration changes — are delivered as versioned packages that pass through your organisation’s approved secure transfer or change management process. CASS reference data refreshes quarterly. Pipeline configurations are version-controlled JSON files that can be updated without redeploying the platform. Scheduled job automation continues to run without interruption during reference data updates.