
Data profiling is the systematic examination of a dataset to measure its completeness, accuracy, consistency, and uniqueness before any cleansing or matching begins. Without profiling first, teams apply fixes blindly — wasting effort on clean fields while critical quality issues go undetected. A profiling run on a 500,000-row CRM typically reveals 12–22% null rates in key fields, 8–15% format violations, and duplicate rates between 5% and 18%.
Ready to see what your data actually looks like? Start a free trial of Match Data Pro and run your first AI profiling report in minutes.
What Data Profiling Actually Measures
Profiling is not a single metric — it is a structured scan across six quality dimensions. Each dimension answers a different diagnostic question about your data.
Completeness
Completeness measures the percentage of records with a value in each field. A profiling scan might reveal that 19% of CRM contacts have no email address, 31% have no phone number, and 7% are missing a last name entirely. Those numbers directly predict downstream match failure rates — a fuzzy matching engine cannot score a name it does not have.
Format Consistency
Format consistency flags fields where values exist but do not conform to an expected pattern. Phone numbers stored as (555) 867-5309, 5558675309, +1-555-867-5309, and 555.867.5309 in the same column represent the same number — but exact matching will fail on all four. Data standardisation can normalise them, but only after profiling identifies the variation scale.
Uniqueness and Duplication Rate
Uniqueness analysis counts distinct values per field and flags near-duplicate patterns across records. A profiler detects that email field has 94% uniqueness but the name + postcode composite has only 82% uniqueness — a strong signal that duplicate customer records exist. This is the input that shapes your deduplication strategy.
Value Distribution and Outliers
Distribution analysis surfaces impossible or improbable values. A revenue field with a mean of $240,000 and a maximum of $4.8 billion signals either a data entry error or a formatting inconsistency (cents stored as dollars). Outlier detection catches these before they corrupt scoring rules or segment analytics.
Referential Integrity
When data spans multiple tables or systems, profiling checks whether foreign key relationships hold. If 11% of order records reference a customer ID that does not exist in the customer table, those orders are orphaned — no amount of matching will fix that without first surfacing the break.
Why Profiling Must Come Before Cleansing and Matching
Many teams jump straight to automated data cleansing or fuzzy matching without a profiling baseline. The result is predictable: cleansing rules fix the wrong fields, match thresholds are set without evidence, and the pipeline runs for hours before returning results nobody trusts.
Consider a concrete example. A RevOps team is preparing to migrate 320,000 contact records into a new CRM. They skip profiling and go straight to deduplication. The dedupe job runs and merges 14,000 record pairs. Post-migration, the sales team reports that 6,000 of those merges were wrong — different contacts with similar names and old shared addresses. The root cause: the team did not know that the address field had 41% stale data. Had profiling run first, they would have flagged address as an unreliable match key and weighted email and phone more heavily.
Profiling delivers three things that no other stage can:
- Field reliability scores — which fields are trustworthy enough to use as match keys
- Prioritised fix list — ranked by impact on downstream match accuracy
- Baseline for regression testing — so you can measure improvement after cleansing runs
The 7-Stage Data Quality Pipeline Starting with Profiling
Match Data Pro structures every data quality engagement as a seven-stage pipeline. Profiling is not optional — it is Stage 2, immediately after connecting the source data.
The diagram below shows how profiling feeds directly into cleansing decisions, which then sequence into fuzzy matching, address verification, and entity resolution.
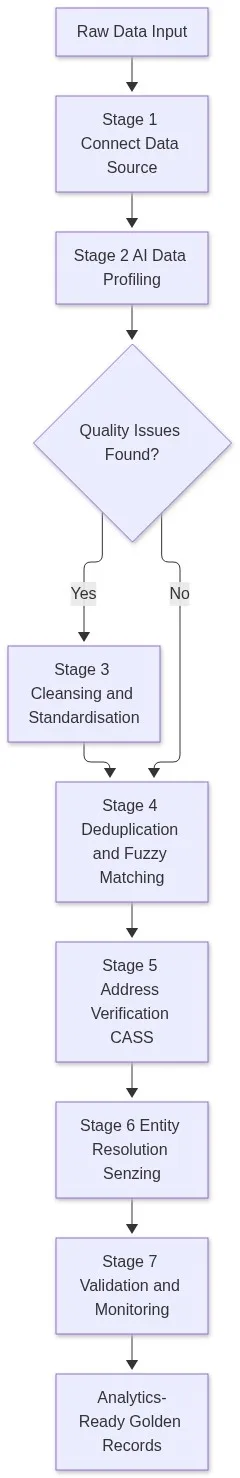
Here is what each stage does and why sequence matters:
| Stage | Action | Key Output |
|---|---|---|
| 1. Connect | Ingest from CSV, DB, API, CRM, ERP | Loaded dataset |
| 2. Profile | Scan completeness, formats, dups, outliers | Quality scorecard + prioritised fix list |
| 3. Cleanse | Fix nulls, normalise formats, strip noise | Standardised fields |
| 4. Deduplicate | Block, fuzzy-score, merge candidates | Collapsed duplicate pairs |
| 5. Verify addresses | CASS-certified address validation, ZIP+4 | Deliverable, normalised addresses |
| 6. Resolve entities | Senzing graph matching, golden record build | Linked entity clusters |
| 7. Monitor | Quality scores, dashboards, drift alerts | Ongoing data health metrics |
What AI-Powered Profiling Adds Over Manual Approaches
Manual profiling — running COUNT(*), GROUP BY, and DISTINCT queries across a schema — works for small datasets. It breaks at scale. A schema with 180 columns and 10 million rows requires thousands of individual queries and days of analyst time just to produce a basic quality snapshot.
AI data profiling in Match Data Pro scans the entire dataset automatically. The engine applies pattern recognition to detect format variants (not just nulls), infers field types from value distributions rather than schema metadata, and flags cross-field anomalies — such as a postcode that does not match the stated city.
Three specific capabilities separate AI profiling from SQL-based approaches:
- Semantic field detection. The profiler recognises that a column named
cust_phcontains phone numbers, even without a schema label, and applies phone-specific validation rules automatically. - Cross-field correlation. It detects that first name and last name fields both have high null rates on records where the company name field is populated — indicating B2B records stored in a B2C schema.
- Suggested match keys. Based on uniqueness scores and null rates, the profiler recommends which field combinations are reliable enough to use as blocking keys in the deduplication stage.
Real-World Profiling Outputs: Before and After
The following table shows a typical profiling report output for a 420,000-row B2B contact database, alongside the resulting cleansing actions and improvement metrics.
| Field | Null Rate | Format Violations | Recommended Action | Post-Cleanse Improvement |
|---|---|---|---|---|
| 14% | 8% (invalid syntax) | Validate syntax, flag invalid | Match accuracy +11% | |
| Phone | 22% | 31% (mixed formats) | Normalise to E.164 | Match accuracy +18% |
| Address line 1 | 9% | 41% (non-standard) | CASS verification, parse | Deliverability +34% |
| Company name | 3% | 17% (abbreviations) | Expand abbreviations, standardise | Entity match rate +22% |
| Postcode | 11% | 19% (5-digit vs ZIP+4) | Append ZIP+4 via CASS | Address match rate +27% |
These gains are not achievable without the profiling baseline. Without knowing that phone had 31% format violations, the team would not have known to standardise before fuzzy scoring — and would have missed a substantial portion of real duplicate pairs.
How to Use Profiling Output to Configure Matching Rules
Profiling output translates directly into data matching configuration. Here is the mapping:
- High-completeness, high-uniqueness fields (email: 86% complete, 97% unique) become primary match keys with high weight — typically 35–45 points in a 100-point composite score.
- Medium-completeness fields (phone: 78% complete, 89% unique after normalisation) become secondary keys — 20–30 points.
- Low-completeness fields (address line 1: 91% complete but 41% format violations pre-cleanse) are used only after CASS verification reduces their error rate — post-cleanse weight 15–25 points.
- High-violation fields that cannot be reliably cleansed are excluded from match keys entirely and flagged for manual review.
This evidence-based approach to matching algorithm configuration is what separates production-grade pipelines from guesswork. Teams that set thresholds without profiling data routinely over-merge (combining different people) or under-merge (missing clear duplicates at the same threshold).
Profiling for Ongoing Data Governance
Profiling is not a one-time pre-project activity. Data degrades at approximately 2–3% per month due to contact churn, address changes, and integration errors from new data sources. A single profiling run before a migration does nothing to prevent quality decay six months later.
Match Data Pro supports scheduled profiling jobs — daily, weekly, or on ingestion — that feed into a data quality dashboard. When null rates or format violation rates cross a configured threshold, the platform raises an alert before the bad data propagates to downstream systems.
This positions profiling as the continuous input to your data quality monitoring programme, not just a gate before a one-off project. It also supports data governance audit trails — every profiling result is timestamped and stored, so compliance teams can demonstrate data quality at any point in time.
Want to see profiling in action on your own data? Book a demo and we will walk through a live profiling run against a sample of your dataset.
Frequently Asked Questions
What is data profiling and why does it matter?
Data profiling is the automated examination of a dataset to measure completeness, format consistency, uniqueness, value distributions, and referential integrity. It matters because it reveals the actual quality of your data before cleansing or matching begins — turning assumptions into evidence. Without it, teams configure matching rules and cleansing logic based on guesswork, which typically results in a 15–30% higher false-match rate.
How long does data profiling take?
AI-powered data profiling in Match Data Pro typically completes a full scan of a 1-million-row dataset in under 10 minutes. Manual SQL-based profiling across the same dataset can take 2–5 analyst days depending on schema complexity. Profiling run time scales with column count and row volume, but automated platforms parallelize the scan across fields simultaneously.
What is the difference between data profiling and data cleansing?
Data profiling measures quality — it diagnoses what is wrong and quantifies the scale of each issue. Data cleansing fixes quality — it applies rules, transformations, and standardisation to correct the problems profiling identified. Profiling must always precede cleansing, because cleansing rules applied without profiling data are likely to fix the wrong fields or use incorrect thresholds.
Can data profiling detect duplicate records?
Yes. Data profiling identifies duplication signals — high value overlap across name and address fields, low uniqueness scores on composite key combinations, and repeated phone or email values across multiple records. It does not merge duplicates; that is the job of a deduplication engine. But profiling gives you the duplication rate estimate (e.g., “approximately 11% of records appear duplicated”) that you need to scope and prioritise the deduplication work.
How often should you run data profiling?
At minimum, run profiling before every major data project — migration, integration, or analytics build. For operational databases, schedule profiling on every significant ingestion event or on a weekly cadence. Customer and contact databases degrade at 2–3% per month, so a monthly profiling run is a reasonable baseline. High-velocity systems (e-commerce, real-time CRM) benefit from daily profiling with automated alerts.