
Data preparation transforms raw, inconsistent source data into clean, validated, analytics-ready records. A complete data preparation pipeline runs seven stages: profiling, standardisation, cleansing, address verification, deduplication, entity resolution, and job automation. Skip any stage and downstream models receive bad inputs — corrupted analytics, flawed segments, and unreliable AI outputs follow.
Start a free trial of Match Data Pro and run your first data preparation pipeline today — no contract required.
Why Data Preparation Is Not Optional
Analysts spend an estimated 60–80% of their time on data preparation tasks — finding, cleaning, and reformatting data before any analysis begins. That figure comes from repeated industry surveys, and it has not improved materially over a decade despite better tooling. The reason is structural: organisations collect data from more sources than ever — CRM, ERP, marketing automation, third-party lists, APIs — and each source has its own formats, conventions, and error rates.
The consequences of skipping preparation are measurable. Duplicate customer records inflate campaign costs by 10–20%. Unstandardised address fields cause 15–25% of mail pieces to be undeliverable. Inconsistent name formats break entity matching and produce fragmented customer views that corrupt analytics and AI training data.
A structured data quality framework treats data preparation as a repeatable pipeline, not a one-off clean. Each stage builds on the previous one. Skipping stage 2 means stage 5 produces lower-precision matches. Skipping stage 4 means golden records carry bad addresses.
The Seven Stages of a Data Preparation Pipeline
The diagram below maps the full pipeline from raw source data to analytics-ready output.
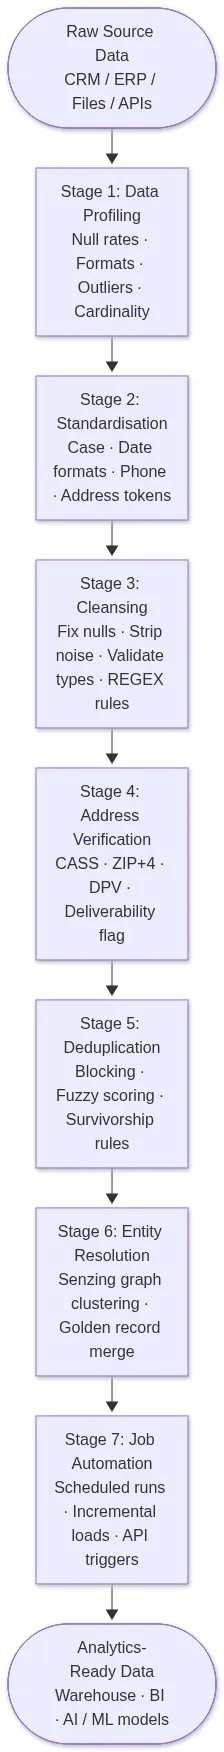
Stage 1: Data Profiling
Data profiling is the diagnostic pass that quantifies every quality problem before any transformation runs. For each field, it measures:
- Null rate — what percentage of records have no value in this field
- Format distribution — how many distinct formats appear (e.g. “MM/DD/YYYY” vs “YYYY-MM-DD” vs “Jan 5 2024”)
- Cardinality — the number of distinct values, flagging fields that should be categorical but have high variance
- Outliers — values that fall outside expected ranges (a zip code with 7 digits; a revenue field with negative values)
Match Data Pro’s AI profiling engine scans datasets automatically and produces a field-level quality score with issue counts. A profiling run on a 2-million-row CRM export typically completes in under 10 minutes and returns a prioritised issue list that drives every downstream configuration decision.
Stage 2: Standardisation
Data standardisation converts format variants into a single canonical form so that matching and aggregation produce consistent results. Common transformations include:
- Name case normalisation: “JOHN SMITH” → “John Smith”
- Date format unification: “01/15/24”, “Jan 15 2024”, “2024-01-15” → ISO 8601: “2024-01-15”
- Phone number formatting: “(312) 555-0123”, “3125550123”, “+1-312-555-0123” → E.164: “+13125550123”
- Address token parsing: “123 Main St Apt 4B Chicago IL 60601” → structured fields: Street Number, Street Name, Unit, City, State, ZIP
These transformations are not cosmetic. A deduplication engine comparing “JOHN SMITH” against “John Smith” without prior case normalisation will score a lower string similarity than the records deserve, causing false negatives. Every format variant that survives into the matching stage adds noise and reduces precision.
Stage 3: Data Cleansing
Data cleansing corrects errors that profiling identified and that standardisation cannot fix by format rules alone. This includes:
- Null imputation — filling missing fields from secondary sources or derived logic (e.g. deriving State from ZIP code)
- Noise stripping — removing placeholder values (“N/A”, “TEST”, “999-999-9999”), HTML tags embedded in text fields, and special characters that break downstream parsing
- Type validation — confirming that numeric fields hold numbers, date fields hold valid dates, and email fields match a valid pattern
- REGEX rules — applying regular expression transforms to extract structured data from free-text fields (e.g. extracting a 10-digit phone number from a notes field)
Match Data Pro applies cleansing rules as a configurable rule set. Teams can define custom expressions, import/export connector mappings, and chained transformations that execute in sequence across any source format — CSV, Excel, database, or API feed.
Stage 4: Address Verification
Address verification is a specialised cleansing step for postal records. Address cleansing using CASS (Coding Accuracy Support System) certification checks every address against the USPS delivery database, returning:
- DPV (Delivery Point Validation) status — whether the address is deliverable
- ZIP+4 appended — the 4-digit extension that pins the address to a specific block face or building
- Standardised USPS format — consistent abbreviations and street suffix forms
Approximately 15–25% of addresses in a typical enterprise CRM fail DPV on the first pass. Catching those failures at stage 4 prevents undeliverable mail, failed address-based deduplication, and inaccurate geographic analytics. Match Data Pro’s CASS-certified address verification runs inline as part of the preparation pipeline — no separate API call or vendor integration required.
Stage 5: Deduplication
Data deduplication identifies records that refer to the same real-world entity and merges them into a single verified record. The challenge is that duplicates rarely look identical — they have typos, missing fields, format differences, and nickname variants.
A production deduplication pipeline uses three sub-stages:
- Blocking — partition the dataset so the engine only compares records that could plausibly match (same first 3 characters of surname, same ZIP, same first 4 of phone). Without blocking, an n² comparison on 1 million records requires 500 billion pair evaluations.
- Fuzzy scoring — apply weighted algorithms per field. Names use Jaro-Winkler. Addresses use token-set ratio. Phone numbers use Levenshtein on the digit string. Each field score is multiplied by its configured weight, and the composite score is compared against a threshold.
- Survivorship rules — when two records merge, survivorship rules determine which field value survives. Common rules: prefer the most-recently-updated value; prefer non-null over null; prefer the longer string for free-text fields.
Match Data Pro’s AI-powered fuzzy matching engine supports configurable algorithm selection per field, threshold tuning per use case, and real-time deduplication via its live fuzzy search API for point-of-entry duplicate prevention.
Stage 6: Entity Resolution
Entity resolution goes one step further than deduplication. Where deduplication collapses exact or near-exact duplicates within a single dataset, entity resolution links records across multiple disparate systems — CRM, ERP, marketing platform, support system — that refer to the same underlying person, company, or location.
Match Data Pro integrates Senzing, an enterprise-grade graph-based entity resolution engine. Senzing builds a probabilistic graph of relationships between records, clusters them into resolved entities, and assigns a persistent global entity ID. This powers a true 360-degree customer view: every touchpoint across every system linked to a single identity.
A worked example: a customer named “Jon Smith” appears as “Jonathan Smith” in the ERP, “J. Smith” in the support ticket system, and “John Smyth” in the marketing platform. Standard deduplication operating on individual sources would miss most of these. Senzing entity resolution links all four records into a single verified identity with a confidence score and full audit trail of the match evidence.
Stage 7: Job Automation
Data preparation is not a one-time project. Sources update continuously — new records enter via web forms, API feeds, file imports, and CRM sync jobs. A production pipeline runs on a schedule or triggers incrementally on new record arrival.
Match Data Pro’s job automation layer lets teams configure scheduled runs (daily, weekly, on-demand), incremental processing that only re-processes changed records since the last run, and API-triggered jobs that execute the full pipeline on a new batch submitted via REST endpoint. Import/export connectors cover CSV, Excel, SQL databases, Salesforce, HubSpot, and more — so the pipeline feeds directly from and back into source systems without manual file transfers.
Common Data Preparation Mistakes and How to Avoid Them
Skipping profiling and writing rules blind
Teams that skip profiling write cleansing and matching rules against assumptions rather than evidence. A field they expect to be 90% complete turns out to be 40% null. A date field they expected to be ISO format contains 12 different formats. Profiling takes minutes; fixing matching rules after a failed run takes days.
Standardising after matching
Running deduplication on unstandardised data is the most common cause of low match precision. “IBM Corp”, “I.B.M.”, and “International Business Machines” will score low string similarity without prior standardisation. Apply all standardisation transforms before the first comparison runs.
Treating address verification as optional
Address fields are the most commonly used matching key after name. If 20% of your address fields are non-deliverable or non-standardised, your blocking partitions will fail to group records that should be compared, and your false-negative rate will rise sharply. CASS verification is a required step for any pipeline that uses address as a match field.
Matching across sources without entity resolution
Deduplication within a single source is not the same as resolving identity across sources. A customer who is “clean” in each individual system but appears in three different systems under three slightly different names still represents fragmented identity. Entity resolution is the step that unifies cross-system identity into a persistent golden record.
Data Preparation for AI and Machine Learning Pipelines
AI and ML models are sensitive to data preparation quality in ways that rule-based analytics are not. A BI dashboard with a 5% duplicate rate produces slightly inflated revenue figures. An ML model trained on the same data may learn systematically wrong patterns from the duplicated examples, producing outputs that are confidently wrong.
Specific preparation requirements for ML:
- Label consistency — if training labels are attached to records, duplicate records with conflicting labels will introduce noise that degrades model accuracy
- Feature completeness — imputing or flagging null values matters more for ML than for SQL queries; most ML frameworks handle missing values differently depending on feature type
- Entity consistency — if the same customer appears under three IDs in training data, the model learns three separate patterns for the same entity
- Format consistency — ML feature pipelines expect consistent types; a field that is sometimes numeric and sometimes a string will cause pipeline failures or silent type coercion errors
Match Data Pro’s automated data preparation pipeline outputs analytics-ready records with consistent formats, resolved identities, and verified addresses — exactly the foundation ML feature pipelines require.
Ready to run a production-grade data preparation pipeline? Book a demo and see how Match Data Pro transforms raw source data into trusted records — or start your free trial and run your first job today.
Frequently Asked Questions
What is data preparation and why does it matter?
Data preparation is the process of transforming raw, inconsistent source data into clean, validated, analytics-ready records through a structured pipeline of profiling, standardisation, cleansing, address verification, deduplication, and entity resolution. It matters because every downstream system — BI dashboards, CRM analytics, AI models — produces outputs only as reliable as the data fed into it. Poor preparation is the root cause of most analytics failures.
How long does a data preparation pipeline take to run?
Run time depends on dataset size and pipeline configuration. A profiling pass on 1–2 million records typically completes in under 10 minutes. Full pipeline execution including address verification and deduplication on the same dataset typically takes 30–90 minutes depending on matching complexity. Incremental runs on changed records only are significantly faster — often under 5 minutes for daily CRM updates.
What is the difference between data preparation and data cleansing?
Data cleansing is one stage within data preparation. Cleansing specifically corrects errors, fills nulls, strips noise, and validates field types. Data preparation is the full end-to-end pipeline that also includes profiling (diagnosing issues), standardisation (normalising formats), address verification, deduplication (collapsing duplicates), and entity resolution (linking cross-system identity).
Do I need entity resolution if I already deduplicate my data?
Yes, in most enterprise environments. Deduplication collapses duplicate records within a single source or dataset. Entity resolution links records across multiple disparate systems that refer to the same real-world entity. If your customer exists in three different systems under slightly different name spellings, deduplication alone will not connect those records. Entity resolution produces the persistent cross-system identity that deduplication cannot.
Can data preparation be automated end to end?
Yes. Match Data Pro automates the full pipeline — profiling, standardisation, cleansing, CASS address verification, fuzzy matching, entity resolution, and output — via scheduled jobs or API-triggered runs. Teams configure the pipeline once using import/export connectors, threshold settings, and survivorship rules, then run it on a schedule with no manual intervention. Incremental processing handles daily record updates efficiently.