
A data quality team is the operational unit responsible for profiling, cleansing, deduplicating, and governing your organisation’s data assets. Most organisations need a core team of four to six roles: a Data Quality Lead, one or two Data Quality Engineers, a Data Steward, a Quality Analyst, and a Platform Administrator. The exact headcount scales with data volume, but the role structure stays consistent whether you have 2 million records or 200 million.
Ready to give your team a platform that handles the technical heavy lifting? Start a free trial of Match Data Pro and have your first data quality pipeline running today.
Why Organisations Struggle Without a Defined Data Quality Team
The most common failure mode is not a lack of tools. It is the absence of clear ownership. When no one owns data quality, duplicate records accumulate, format standards drift, and address data degrades at a rate of 10 to 15 percent per year. By the time the problem is visible in a dashboard, the root cause is months old.
Three patterns cause most failures:
- Distributed accountability: Individual teams own their system but no one owns the cross-system view. CRM and ERP records diverge silently.
- Reactive rather than preventive: Teams fix data only when a report breaks or a migration approaches. By then, the backlog is large.
- No measurement: Without defined data quality dashboards and KPIs, it is impossible to show progress or prioritise what to fix first.
A formalised team resolves all three. It creates ownership, shifts effort upstream to prevention, and ties quality metrics to business outcomes.
The Four Core Roles in a Data Quality Team
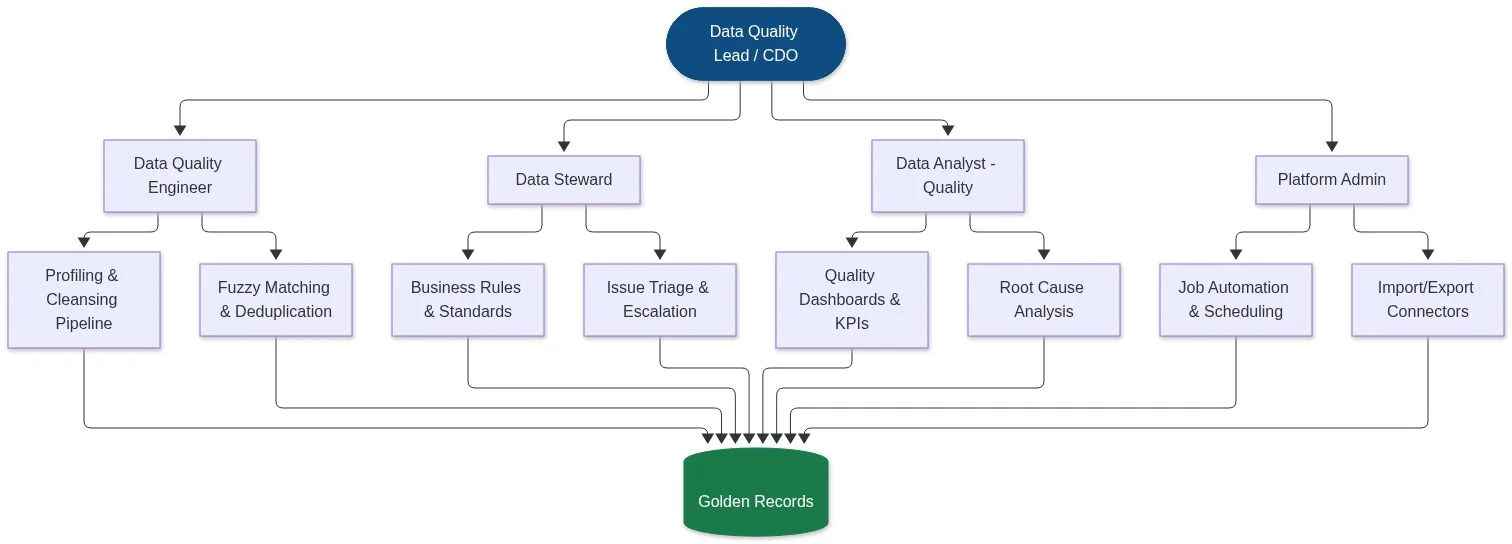
These four roles cover the minimum viable structure for an organisation processing enterprise data volumes. Each maps to a distinct operational domain.
1. Data Quality Lead (or Head of Data Quality)
Owns the data quality strategy, sets organisational standards, and reports to the CDO or VP Data. This role defines the KPIs: duplicate rate, completeness score, address match rate, and freshness by domain. The Lead prioritises the work backlog and liaises with business stakeholders who consume the data. At organisations without a CDO, this person often serves both functions.
Key outputs: Data quality policy, quarterly quality scorecard, escalation matrix.
2. Data Quality Engineer
Builds and maintains the technical pipeline. This role configures AI data profiling jobs to scan incoming datasets, sets up fuzzy matching rules, tunes algorithm weights, and schedules automated deduplication runs. At a typical mid-market organisation, one engineer can manage 15 to 20 active jobs with a well-configured platform.
A concrete example: an engineer configures a weekly deduplication job on the CRM contact table. The job runs data standardisation first (name casing, phone normalisation, state abbreviations), then applies a composite fuzzy score across first name, last name, email, and phone. Pairs scoring above 85 auto-merge. Pairs scoring 60 to 84 go to review queue. Below 60 are discarded.
Key outputs: Configured matching pipelines, automated job schedules, algorithm threshold documentation.
3. Data Steward
Bridges technical and business domains. Stewards own the business rules that govern what a valid record looks like in each domain: what constitutes a duplicate customer versus a legitimate subsidiary, what address format the ERP expects, which phone format the contact centre system accepts. They triage edge cases the automated pipeline flags and document resolution decisions for future reference.
A steward working on a healthcare dataset, for example, decides how to handle records where the same patient appears under two insurance IDs with matching name and date of birth but different addresses. That business logic lives in the matching rules, but a human must define it first.
Key outputs: Business rule library, edge-case resolution log, domain glossary.
4. Data Quality Analyst
Monitors pipeline output, maintains quality dashboards, and investigates anomalies. When data quality issues surface in production, the analyst traces root cause: did the spike in null addresses come from a new import connector, a source system change, or a code deployment? This role requires SQL proficiency and familiarity with the platform’s reporting outputs.
Key outputs: Weekly quality report, root cause analysis, trend charts by data domain.
Two Supporting Roles Worth Adding at Scale
Platform Administrator
Manages the data quality platform itself: user access, connector configuration, upgrade cycles, and job automation schedules. At smaller organisations this role is absorbed by the Engineer. At larger ones — processing more than 50 million records per month — it warrants its own headcount. The admin configures import and export connectors between source systems (CRM, ERP, marketing platform, data warehouse) and the cleansing pipeline.
Domain Data Owner (Business-Side Role)
Not a full-time data quality role, but a formal accountability assignment within each business unit. The sales domain data owner approves changes to CRM matching rules. The finance domain owner approves changes to vendor master deduplication thresholds. Without this accountability layer, data quality teams get bypassed when business units import messy data directly into the system.
How to Structure the Team at Different Organisation Sizes
Team size should track data complexity, not headcount. The right question is not “how many people do we have?” but “how many active data domains do we govern, and what is the monthly record volume?”
| Organisation Size | Monthly Record Volume | Recommended Team Structure |
|---|---|---|
| SME / Mid-Market | Up to 2M records | 1 Lead (also acts as steward), 1 Engineer, 1 Analyst (part-time) |
| Mid-Enterprise | 2M to 20M records | 1 Lead, 1-2 Engineers, 1 Steward per domain, 1 Analyst |
| Large Enterprise | 20M to 100M records | 1 Head of DQ, 2-3 Engineers, 2-3 Stewards, 2 Analysts, 1 Platform Admin |
| Hyperscale | 100M+ records | DQ CoE with dedicated leads per domain, full engineering squad, embedded stewards |
At SME scale, the platform does the heavy lifting. A well-configured automated data cleansing pipeline on Match Data Pro can run nightly jobs across CRM, ERP, and marketing data with one engineer spending four to six hours per week on configuration and monitoring.
The Technology Layer: What Your Team Needs in a Platform
Even the best-structured team underperforms with the wrong tooling. The platform must cover the full pipeline so engineers spend their time on configuration, not custom code.
Here is what each role needs from the platform:
- Data Quality Engineer: AI data profiling to scan and score fields automatically, configurable fuzzy matching algorithms (Levenshtein, Jaro-Winkler, phonetic, token-based), and job automation to schedule recurring cleansing runs without manual triggers.
- Data Steward: A review interface for flagged records, with field-by-field match scores and before/after values visible. The steward should be able to approve or reject a merge in two clicks and document the reason.
- Data Quality Analyst: Pre-built quality dashboards showing completeness, duplication rate, address match rate, and job run history. Trend data by domain so the analyst can detect drift before it reaches a threshold.
- Platform Admin: Import/export connectors for the most common systems (Salesforce, HubSpot, SAP, SQL databases, flat files), role-based access controls, and a live fuzzy search API for real-time record lookups at point of entry.
Match Data Pro covers all of these. The platform includes AI-powered fuzzy matching, entity resolution via Senzing, CASS address verification, automated job scheduling, and a live fuzzy search API. No-contract monthly SaaS means your team can start in a day, not a quarter.
Building the Data Quality Team: A Six-Step Roadmap
Use this sequence to structure your build-out. Each step produces a tangible output that justifies the next investment.
- Audit current state. Run AI data profiling across your primary datasets. Measure null rates, format violations, duplicate rates, and address validity. This gives the Lead a baseline to defend budget and prioritise effort.
- Define domains and owners. List every data domain (customer, vendor, product, location) and assign a business-side Domain Data Owner. This prevents the data quality team from becoming the sole accountable party for problems created upstream.
- Hire or designate the Engineer first. The Engineer unlocks platform productivity. Hire this role before the Analyst. A skilled Engineer with the right platform can automate 70 to 80 percent of the cleansing volume before the Analyst joins.
- Configure the pipeline. Start with one domain: usually customer or contact data. Build the standardisation, deduplication, and address verification jobs. Validate output against the baseline metrics from step 1.
- Add the Steward and Analyst once the pipeline is live. The Steward needs real flagged records to build rules from. The Analyst needs live dashboard data to monitor. Hiring before the pipeline is live produces wasted onboarding time.
- Expand across domains. Replicate the pipeline pattern to vendor, product, and location data. Use the Engineer’s template configurations to accelerate. Add a Platform Admin if job count exceeds 30 or connector complexity increases.
Want to see this pipeline in action on your own data? Book a demo and we will walk through a live build using records from your environment.
Key Performance Indicators for a Data Quality Team
A data quality team without metrics has no mandate to fix anything and no way to show its value. Set these six KPIs from day one:
- Duplicate rate by domain: Target under 2% for customer records, under 1% for vendor master.
- Completeness score: Percentage of records with all mandatory fields populated. Target 95%+ for primary contact fields.
- Address validity rate: Percentage of addresses that pass CASS address verification. Target 90%+.
- Pipeline run success rate: Percentage of scheduled jobs completing without errors. Target 99%+.
- Time to resolution: Average days from issue detection to fix. Track separately for auto-resolved (should be under 1 hour) and steward-reviewed (target under 5 business days).
- Entity resolution coverage: Percentage of records linked to a confirmed golden record. Rising coverage indicates your entity resolution pipeline is working; a plateau or decline signals a configuration or source system change.
Report these monthly to the CDO or IT leadership. Tie them to business outcomes: a 3-percentage-point drop in duplicate rate translated to a 12% reduction in duplicate outbound mailings and a measurable decrease in customer service tickets about incorrect records.
Frequently Asked Questions
How many people do you need on a data quality team?
A minimum viable data quality team requires three roles: a Lead, an Engineer, and a Steward. For organisations processing under 2 million records per month, one skilled engineer with an automated platform can manage the technical pipeline part-time. Add an Analyst once you have live dashboard data to monitor. Scale headcount by domain count, not company size.
What is the difference between a data steward and a data engineer in a quality team?
A data engineer builds and configures the technical pipeline: profiling jobs, matching rules, deduplication thresholds, and job automation. A data steward owns the business rules that the pipeline enforces: what constitutes a duplicate, what field values are valid, how edge cases should be resolved. Engineers configure the system; stewards define what the system should do.
Should data quality sit under IT or the business?
The data quality function works best as a shared service reporting to the CDO or VP Data, with dotted-line accountability into both IT and business units. Pure IT ownership creates a bottleneck and disconnects the team from business impact. Pure business ownership creates a team without the technical skills to build and maintain pipelines. A shared model with clear escalation paths performs best.
What skills should a data quality engineer have?
A data quality engineer should be proficient in SQL, understand fuzzy matching algorithms (Levenshtein, Jaro-Winkler, phonetic), and be comfortable configuring automation workflows. Experience with data profiling tools, record linkage concepts, and at least one integration pattern (API, flat file, database connector) is essential. Python scripting is useful but not required when using a platform like Match Data Pro.
How long does it take to build a functioning data quality team?
A functioning data quality team covering one domain can be operational in 30 to 60 days. The critical path is: hire or designate the Engineer (week 1), configure the platform and baseline profiling (weeks 2 to 3), run the first deduplication and cleansing job (week 4), and begin reporting (week 5). Onboarding additional domains typically adds two to three weeks per domain once the first pipeline is validated.