
Data virtualisation creates an abstraction layer that lets applications query disparate sources as if they were one unified database. It speeds up access to data without physical movement. But it cannot fix poor data quality in those sources. When customer records across your CRM, ERP, and data lake contain duplicates, inconsistent formats, or invalid addresses, the virtualised view inherits every one of those problems and amplifies them across every consuming application.
Ready to clean your source data before virtualisation? Book a demo and see how Match Data Pro prepares multi-source data for reliable virtual views.
What Is Data Virtualisation?
Data virtualisation is an integration approach that provides a single logical view of data held in multiple physical systems. Instead of copying data into a centralised repository, queries pass through a virtualisation layer that translates and federates requests in real time. The source systems retain their own data; the virtualisation layer presents a unified schema.
Common use cases include real-time analytics across cloud and on-premise systems, self-service BI where users query without knowing the underlying source, and regulatory reporting where data must be drawn from multiple authoritative systems simultaneously.
Three things make data virtualisation attractive to enterprise data teams:
- No ETL pipelines to maintain for read-only consumption
- Near-real-time query results against live source data
- A single semantic layer that IT can govern centrally
The Data Quality Problem Virtualisation Cannot Solve
Virtualisation connects sources. It does not clean them. This is the most common misconception data architects encounter when evaluating the technology.
Consider a retail organisation with three customer systems: a Salesforce CRM, an order management platform, and a legacy ERP. Customer “Jon B. Smith” in the CRM is “Jonathan Smith” in the ERP and “J. Smith” in the order system. The virtualised view sees three separate entities. Every dashboard, model, and report built on top of that view inherits the fragmentation.
Specific quality failures that propagate through a virtualisation layer include:
- Duplicate records: The same customer or vendor appears multiple times with minor name or address variants, inflating counts and corrupting segmentation.
- Inconsistent formats: Date fields stored as MM/DD/YYYY in one system and YYYYMMDD in another cause query failures or silent miscalculations.
- Invalid addresses: Unverified postal data makes location-based analytics unreliable and wastes direct-mail spend.
- Fragmented entity identity: Without entity resolution, the same real-world organisation appears as dozens of slightly different records across procurement, sales, and finance.
None of these issues are resolved by adding a virtualisation layer. They must be fixed at the source or in a dedicated data quality pipeline that runs before or alongside virtualisation.
| Quality Problem | Impact Without a Fix | Impact Amplified by Virtualisation |
|---|---|---|
| 5% duplicate rate | Double-counting in one system | Double-counting in every federated query |
| Format mismatch (dates) | Errors in one pipeline | Join failures across all virtualised sources |
| Unresolved entity identity | Fragmented analytics | Fragmented analytics multiplied by source count |
| Invalid addresses | Wasted mailing cost | Corrupted location analytics at scale |
Data Quality as a Prerequisite for Reliable Virtual Views
For virtualised data to be trustworthy, source data must meet minimum quality standards before the virtualisation layer touches it. That means running a structured quality pipeline on each contributing system.
Stage 1: AI Data Profiling
AI data profiling scans each source dataset and measures null rates, format distributions, value-range violations, and suspected duplicate rates. A profiling run on a 2-million-record CRM database typically surfaces 8-15% null rates on key identifier fields, 5-12% format violations on phone and date fields, and 3-8% duplicate rates on name-address combinations. These numbers define what the quality pipeline must fix before virtualisation can expose the data reliably.
Stage 2: Standardisation and Cleansing
Data standardisation converts raw inconsistent source values into a uniform format: date fields to ISO 8601, phone numbers to E.164, company suffixes (Inc, Incorporated, Corp) to a canonical form, and state codes to two-letter abbreviations. Without this step, cross-source queries against a virtualised layer join on mismatched values and return incomplete or wrong results.
Stage 3: Fuzzy Matching and Deduplication
Once records are standardised, fuzzy matching identifies which records across sources refer to the same real-world entity. Levenshtein distance catches transpositions (Smyth vs Smith). Jaro-Winkler handles name prefixes. Token-based algorithms handle company names where word order varies (“Acme Corp LLC” vs “LLC Acme Corporation”). Match scores above a configured threshold route records to deduplication, collapsing them into a single verified record.
Stage 4: Entity Resolution
Fuzzy matching at the record level is not sufficient for complex multi-system identity problems. Entity resolution using the Senzing engine builds a persistent entity graph that tracks relationships across sources, handles alias networks, and updates entity clusters as new records arrive. This converts fragmented identity into a consistent, queryable golden record that the virtualisation layer can expose reliably.
Stage 5: Address Verification
CASS address verification validates and standardises every postal record against the USPS database, appending ZIP+4 codes, correcting abbreviations, and flagging undeliverable addresses. For virtualisation use cases involving location-based analytics or direct-mail outputs, unverified addresses produce incorrect geographic segmentation and wasted cost per piece. The address cleansing pipeline in Match Data Pro runs CASS verification automatically as part of the quality job.
How Match Data Pro Prepares Data for Virtualisation
Match Data Pro is a cloud SaaS data quality platform. It connects to source systems via import/export connectors covering flat files, databases, cloud APIs, and CRM/ERP platforms. For each connected source, it runs the full quality pipeline: AI profiling, standardisation, fuzzy matching and deduplication, Senzing entity resolution, and CASS address verification.
The output is a golden record per entity with a survivorship-rule-defined field set: the most complete, most recent, and most frequently confirmed value wins each field. That golden record writes back to the source or to a staging layer that the virtualisation tier reads as its authoritative input.
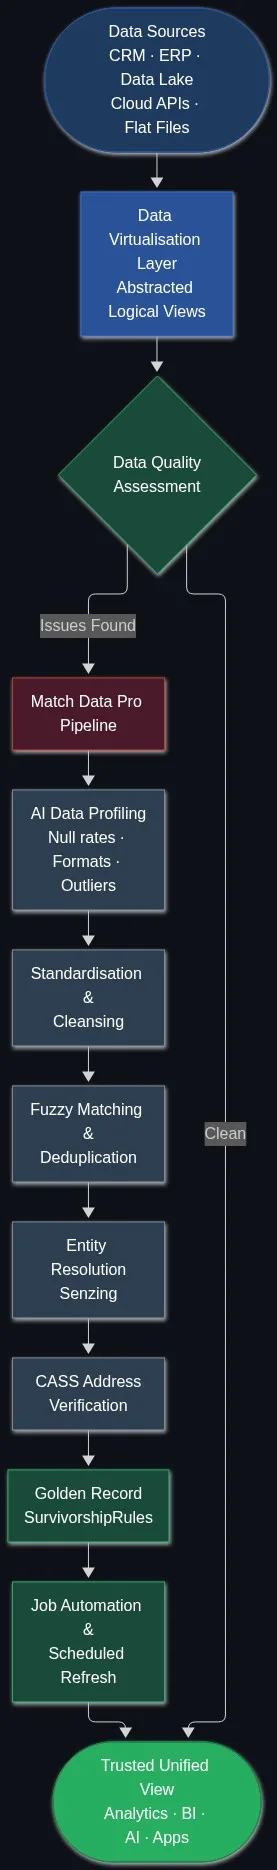
Job automation schedules quality runs on a cadence that matches source update frequency. A nightly batch job re-profiles and re-deduplicates before the morning analytics window opens. A live fuzzy search API handles real-time lookups when the virtualisation layer needs an on-demand quality check for a newly arrived record. No long-term contract is required. Teams can start a free trial and confirm match rates against their own data before committing.
Practical Data Quality Checks for Every Virtualisation Project
Before enabling a virtualised view, run these checks on each source system:
Completeness Threshold
Key identifier fields (customer ID, name, email) must be present in at least 90% of records. Fields below 85% completeness produce unreliable join results through the virtualisation layer. Profile first, fill gaps through enrichment or flag records for exclusion.
Duplicate Rate Threshold
A source with more than 5% duplicate records will cause double-counting in aggregated virtual views. Run deduplication and confirm the duplicate rate drops below 2% before enabling the feed. Golden record outputs from Match Data Pro carry a confidence score and a unique persistent entity ID that the virtualisation layer uses as a stable join key across all sources.
Format Conformance Rate
All date, phone, address, and currency fields must conform to a single standard. A format conformance rate below 95% will produce query errors or miscalculations. Standardise before exposing.
Entity Resolution Coverage
Confirm that entity resolution has processed 100% of records in each source. Any unresolved record is a potential duplicate that the virtualisation layer will surface as a separate entity. Track entity resolution coverage as a quality metric in your data quality dashboard.
See Match Data Pro in action on your own data. Start your free trial at members.matchdatapro.com. No long-term contract required.
Frequently Asked Questions
What is data virtualisation and how does it differ from ETL?
Data virtualisation provides a logical unified view of multiple source systems without physically moving data. ETL extracts, transforms, and loads data into a target store. Virtualisation is faster to deploy for read-only use cases but requires higher source data quality because it has no transformation layer to fix errors before queries execute.
Why does data quality matter so much for data virtualisation?
Virtualisation amplifies source quality problems across every consumer of the virtual view. A 5% duplicate rate in a CRM becomes a 5% count inflation in every dashboard and report built on that view. Poor format conformance causes join failures across sources. Without upstream cleansing and deduplication, virtual views are unreliable at scale.
How do you deduplicate records across sources for a virtualisation project?
Run a fuzzy matching pipeline that scores record similarity across name, address, phone, and email fields using multiple algorithms weighted by field importance. Records above a match threshold are collapsed to a golden record using survivorship rules. That golden record carries a persistent entity ID used as the join key in the virtual layer. Match Data Pro automates this across all connected sources.
What is entity resolution and why does it matter for virtual data layers?
Entity resolution links records that refer to the same real-world entity across multiple systems, even when no shared identifier exists. For virtual data layers, it ensures that “Acme Corp” in the CRM and “ACME Corporation” in the ERP resolve to one entity rather than appearing as two separate rows in every federated query. Without it, analytics on the virtual layer overcount unique entities.
Can Match Data Pro connect to my existing data sources for quality processing before virtualisation?
Yes. Match Data Pro supports import/export connectors for flat files (CSV, Excel), relational databases (SQL Server, PostgreSQL, MySQL, Oracle), cloud storage, and CRM/ERP platforms. Each source runs through the full quality pipeline: AI profiling, standardisation, fuzzy matching, entity resolution, and CASS address verification. Outputs write back to source or to a clean staging layer. No long-term contract is required.