
Vendor matching identifies duplicate and near-duplicate supplier records across procurement, ERP, accounts payable, and contract management systems and consolidates them into a single verified vendor record. Without it, organisations routinely carry 15–30% duplicate vendor rates, which inflate payment risk, distort spend analytics, and break compliance controls. The fix is a structured matching pipeline that combines AI-powered fuzzy matching, address verification, and entity resolution to produce a clean, actionable vendor master.
Ready to clean your vendor master? Start a free trial of Match Data Pro and run your first vendor deduplication job in minutes.
Why Duplicate Vendor Records Exist
Vendor duplication is a structural problem, not a data entry accident. It emerges from several predictable sources:
- Multiple onboarding paths. Procurement, AP, and contract teams each create vendor records independently. “Acme Corp” in the procurement system becomes “Acme Corporation Ltd” in the ERP and “ACME CORP.” in the AP tool.
- Acquisitions and re-brandings. A supplier changes its legal name. Old records survive while new ones are created. Both remain active.
- System migrations. Data from legacy systems loads without deduplication. Historical records and current records coexist under slightly different identifiers.
- Regional or subsidiary variation. The same parent company operates as five legal entities across different jurisdictions, each entered as a separate vendor.
The result: a vendor master where “Microsoft Corporation”, “Microsoft Corp”, “Microsoft Ltd”, and “MSFT” all appear as separate entries. Each has its own payment terms, contact records, and spend history. None of them connects to the others.
Related: Vendor Master Data Cleansing: How to Fix Supplier Data Before It Breaks Your ERP
What Vendor Matching Actually Does
Vendor matching is the process of identifying records that refer to the same real-world supplier and grouping them for merge or link. It operates across four dimensions simultaneously:
Name Matching
Supplier names are the noisiest field. Legal suffixes (“Inc.”, “LLC”, “GmbH”, “Ltd”) vary by system. Abbreviations appear in some records and not others. Acronyms replace full names. Effective fuzzy matching algorithms such as Jaro-Winkler and token-set ratio handle these variants without requiring exact string equality. A typical match on “Acme Corporation” vs. “Acme Corp.” returns a score of 91/100 under token-set ratio.
Address Matching
Street addresses carry their own noise: “123 Main St” versus “123 Main Street”, “Suite 400” versus “#400”, missing ZIP codes, and transposed digits. CASS address verification normalises every address against the USPS postal database before matching runs. Once normalised, two records at the same physical location are far easier to link reliably.
Tax ID and Registration Number Matching
EIN, VAT numbers, and DUNS identifiers are the strongest deterministic signals. When two records share a Tax ID, they are almost certainly the same vendor. When they differ, the match score drops and the record pair routes to human review. Combining Tax ID signals with fuzzy name scores produces a composite score that handles both clean and dirty data.
Contact and Banking Detail Matching
Phone numbers, email domains, and bank account numbers provide secondary signals. A shared bank account across two vendor records is a strong indicator of duplication. Match Data Pro’s multi-field weighted scoring combines all signals into a single composite match score, weighted by field reliability.
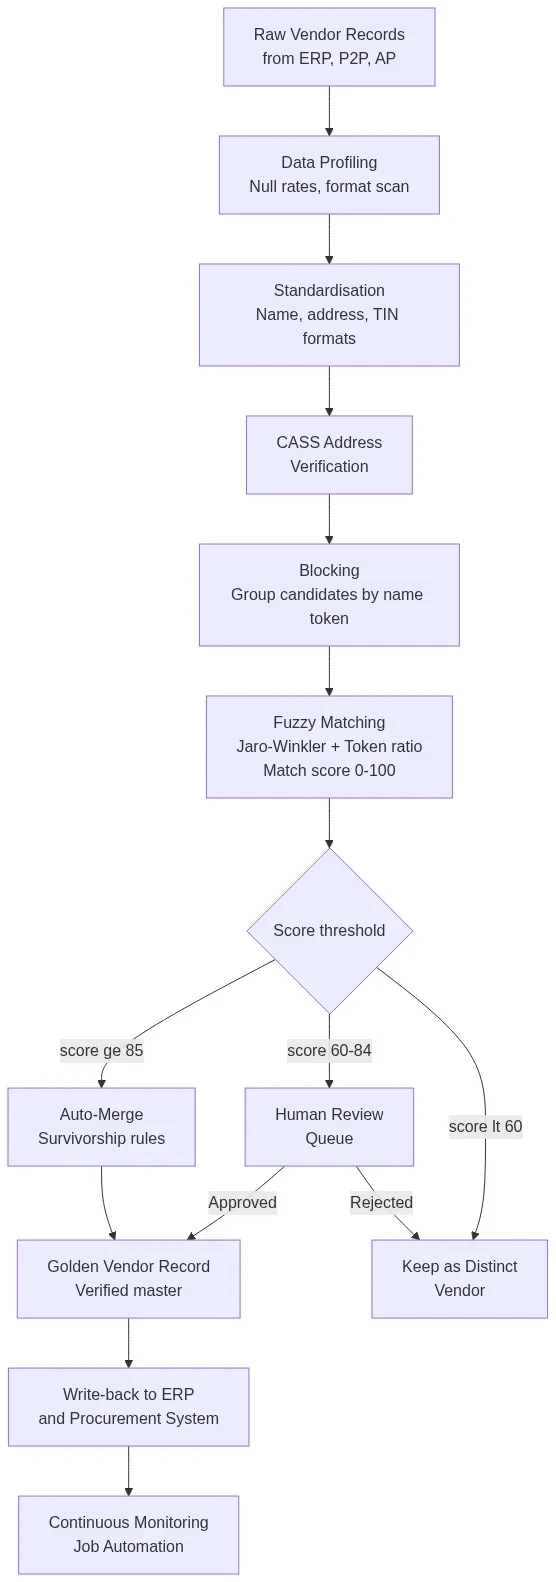
The Vendor Matching Pipeline: Seven Stages
Stage 1: Data Profiling
Before matching begins, AI data profiling scans every field in the vendor master: null rates, format distributions, duplicate key counts, and value anomalies. A typical enterprise vendor master shows 18–22% null Tax IDs, 30–40% inconsistent legal suffixes, and 10–15% address formatting errors. Profiling surfaces these numbers before a single match runs.
Stage 2: Standardisation
Raw vendor names go through normalisation: legal suffix stripping (“Corporation” to “Corp”), case normalisation, punctuation removal, and unicode transliteration. Address fields are parsed into street number, street name, unit, city, state, and ZIP. Tax IDs are reformatted to a canonical pattern (XX-XXXXXXX for EIN). Standardised data reduces false negatives by 35–50% compared to matching on raw input.
Stage 3: CASS Address Verification
Every vendor address is verified against the USPS CASS-certified database. Invalid addresses are flagged. Deliverable addresses receive standardised format and ZIP+4 appended. This step is critical for address-based matching: two vendors at the same physical location but entered with different street formats will only link reliably after CASS normalisation. See how address cleansing works in practice.
Stage 4: Blocking
Blocking reduces the comparison space from O(n²) to manageable clusters. Records are grouped by shared tokens: the first three characters of the normalised vendor name, ZIP code prefix, or Tax ID prefix. Only records within the same block are compared. This step makes million-record vendor masters computationally feasible.
Stage 5: Fuzzy Matching and Composite Scoring
Within each block, every pair receives a composite match score:
- Vendor name similarity: Jaro-Winkler (weight 35%)
- Address similarity: normalised edit distance (weight 25%)
- Tax ID match: exact (weight 30%)
- Phone/email domain match: token match (weight 10%)
Score range: 0–100. A score of 85+ triggers automatic merge. A score of 60–84 routes to a human review queue. Below 60, records are treated as distinct vendors. Match Data Pro’s configurable matching engine lets teams adjust weights and thresholds without code changes.
Stage 6: Survivorship and Golden Record Creation
When records merge, survivorship rules determine which field values survive. Typical rules: prefer the most recent Tax ID, prefer the ERP vendor name over the AP name, prefer the CASS-verified address. The output is a golden vendor record — a single authoritative entry with the best data from all source records, plus a full audit trail of what was merged and why.
Stage 7: Write-back and Automation
The golden vendor record writes back to the source ERP and procurement system via import/export connectors. Scheduled job automation re-runs the matching pipeline on a weekly or nightly basis, catching new duplicates as they enter the system. New vendor onboarding triggers a real-time check via the live fuzzy search API before the record is committed.
Real-World Duplicate Examples
Below are four common vendor duplicate patterns and how matching resolves them:
| Record A | Record B | Match Score | Action |
|---|---|---|---|
| Acme Corporation, 123 Main St, Chicago IL | Acme Corp., 123 Main Street, Chicago IL 60601 | 93 | Auto-merge |
| Global Supply Inc, EIN 12-3456789 | Global Supplies Inc, EIN 12-3456789 | 96 | Auto-merge (Tax ID exact) |
| Johnson & Johnson Medical, 123 Fifth Ave NY | J&J Medical Devices, 400 College Rd NJ | 67 | Human review |
| Tech Solutions LLC, Dallas TX | Technology Solutions Corp, Austin TX | 48 | Keep distinct |
The third example shows why human review matters. “Johnson & Johnson Medical” and “J&J Medical Devices” share a parent company but may be different legal entities with separate contracts and payment terms. The 67-point score flags it for review rather than automatic merge.
The Cost of Not Matching Vendors
Duplicate Payments
When the same invoice is processed against two vendor records for the same supplier, AP systems may pay twice. Industry benchmarks suggest 0.1–0.5% of total payables are affected by duplicate payments in organisations without vendor deduplication. On a $500M payables volume, that is $500K–$2.5M per year.
Spend Analytics Distortion
When spend is fragmented across 12 vendor records for the same supplier, no single record shows the full spend relationship. Volume discounts, preferred supplier agreements, and spend consolidation opportunities become invisible. Inaccurate data costs compound across every downstream analytics report.
Compliance Failures
Sanctions screening, OFAC checks, and supplier risk ratings operate on vendor name and address. A fragmented vendor master means the same high-risk supplier may clear screening on one record and flag on another — creating a compliance gap that auditors and regulators will find. Entity resolution closes this gap by consolidating all supplier identities before screening runs.
Vendor Matching in Practice: Key Scenarios
ERP Go-Lives and Migrations
SAP, Oracle, and Workday go-lives are the most common trigger for vendor matching projects. Legacy systems carry years of accumulated duplicates. A pre-migration vendor deduplication run typically reduces vendor master record counts by 20–35%, which directly reduces data migration scope and cost. See how this fits into a broader vendor matching evaluation.
Post-Acquisition Integration
When two companies merge, their vendor masters overlap significantly. The combined entity may have 8,000 vendors in system A and 6,000 in system B, with 40–60% overlap. Running a cross-system fuzzy match identifies the overlap and produces a unified vendor master before systems consolidate. The alternative is years of manual reconciliation.
Continuous Vendor Onboarding
New vendor records enter the master daily. Without real-time duplicate checking at point of entry, duplicates accumulate faster than batch cleanup can remove them. A live fuzzy search API call at onboarding catches “Acme Corp” before a second record for “Acme Corporation” is committed. This is the only approach that prevents duplication rather than reacting to it.
Match Data Pro supports all three scenarios from a single platform. Book a demo to see how your vendor master would perform against a live matching run.
Frequently Asked Questions
What is vendor matching?
Vendor matching is the process of identifying records in a vendor master that refer to the same real-world supplier, even when names, addresses, or identifiers differ slightly. It uses fuzzy matching algorithms, Tax ID comparison, and address verification to produce a composite match score, then merges confirmed duplicates into a single golden vendor record.
How many duplicates does a typical vendor master contain?
Most enterprise vendor masters contain 15–30% duplicate or near-duplicate records. The rate is higher after system migrations, acquisitions, or long periods without active deduplication. Organisations with multiple ERP instances and regional procurement teams often see rates above 30%.
Can vendor matching work without a Tax ID or DUNS number?
Yes. When Tax IDs or DUNS numbers are missing or inconsistent, matching falls back to fuzzy name comparison, address normalisation, phone number matching, and email domain comparison. The composite score is lower without a Tax ID signal, so the human review queue grows, but matches are still found accurately across the remaining fields.
What is a golden vendor record?
A golden vendor record is the single authoritative output of a vendor merge operation. It combines the best field values from all source records — most reliable Tax ID, CASS-verified address, most recent contact details — into one master entry. It includes a full audit trail showing which source records were merged and which survivorship rules applied.
How often should vendor matching run?
Most organisations run a full vendor deduplication batch weekly or nightly via job automation. Additionally, a real-time fuzzy search API check at vendor onboarding prevents new duplicates from entering the master. High-volume procurement environments with daily vendor creation events benefit most from real-time prevention combined with periodic batch cleanup.