AI-powered data quality workflows can run inside fully isolated, air-gapped environments — no cloud connectivity required. Regulated industries including defence, intelligence, healthcare, and financial services regularly process sensitive records entirely on-premise. The architectural decisions that make this work are specific and non-trivial.
This article covers the design patterns, pipeline stages, and tooling choices that enable robust data quality automation in regulated, network-isolated infrastructure.
What Is an Air-Gapped Environment in Data Engineering?
An air-gapped system has no logical or physical connection to the public internet or external networks. Data enters through controlled ingestion channels — encrypted USB transfers, secure file drops, one-way data diodes — and never leaves through an outbound internet connection. Any software running inside must be fully self-contained.
For data quality teams, that means every component of the pipeline — profiling engine, matching algorithms, entity resolution library, job scheduler — must be deployable without reaching an external registry or licence server. This is a harder constraint than “private cloud” or “VPC.” A VPN connection back to a cloud vendor still disqualifies a system from true air-gap status in most defence and intelligence contexts.
Common regulated environments that require air-gapped data quality
- Department of Defence and intelligence agency data pipelines
- National-security classified record systems
- Hospital networks under strict data residency rules
- Financial institutions subject to data sovereignty regulation
- Critical infrastructure operators (energy grids, water systems)
Why Standard AI Workflow Architectures Fail in Air-Gapped Settings
Most modern AI tooling assumes internet access at every stage. Model weights are fetched from remote registries. Licence validation phones home on startup. Dependency updates pull from public package repositories. In an air-gapped environment, each of these assumptions breaks the workflow before a single record is processed.
The cloud-dependency problem
Cloud-native data quality platforms are built to ingest records, run matching jobs, and write results — all via API endpoints that expect outbound HTTPS traffic. Remove that connectivity and the platform stalls. Some vendors offer an “on-premise” option that still requires a periodic licence check-in with a remote server. That is not a true air-gapped deployment.
Match Data Pro’s on-premise deployment option packages all processing components — the Senzing entity resolution engine, the fuzzy matching pipeline, data profiling, and job automation — into a self-contained installation that operates without any outbound network dependency.
Model weight distribution and versioning
When AI-assisted matching uses trained models, those weights must be bundled at install time and updated through the same controlled ingestion channel used for data. There is no mechanism to pull a new model version from a remote registry inside a classified environment. Teams need a versioning process that mirrors the organisation’s existing software update approval workflow.
Building a Data Quality Pipeline for Air-Gapped Environments
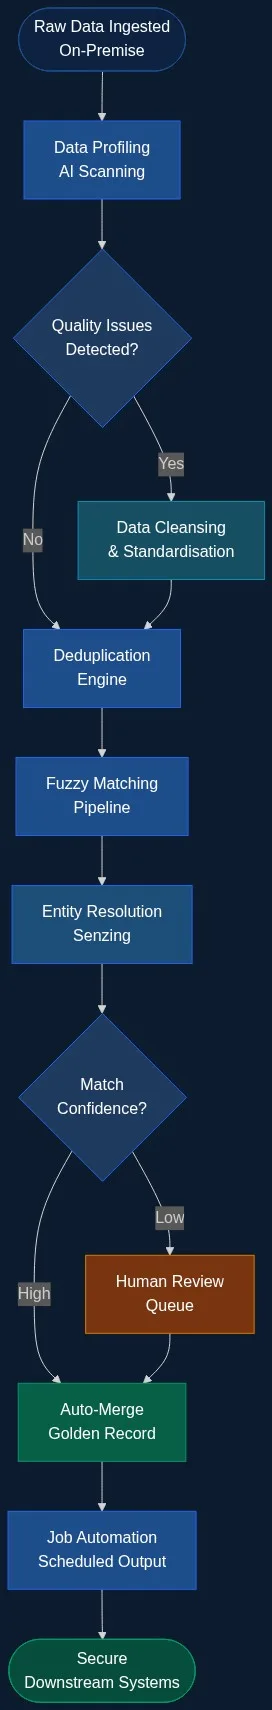
The pipeline stages are identical to any enterprise data quality workflow. The difference is in how each stage is packaged and executed. Every service must be deployable from an internal artefact repository with no external calls.
Stage 1: Data ingestion and profiling
Records enter through an approved ingestion path. The first step is AI-powered data profiling — scanning for field completeness, format consistency, value distributions, and anomaly patterns. In an air-gapped context, the profiling engine runs against the local dataset with no connectivity requirement. Profiling surfaces problems early: a name field that is 40% blank, a phone number column where 15% of values contain letters, a date field with three competing formats.
Stage 2: Cleansing and standardisation
Once the profile is complete, automated data cleansing corrects structural errors and normalises fields to a consistent format. Consider a dataset with address variants:
- Before: “1600 Pennsylvania Ave NW”, “1600 PENNSYLVANIA AVE.”, “1600 Penn. Ave NW”
- After: “1600 Pennsylvania Ave NW, Washington, DC 20500”
Standardisation rules for names, addresses, phone formats, and company abbreviations all execute locally. No external lookup is needed for most standardisation logic — the rules are configuration-driven, not API-dependent.
Stage 3: Deduplication
With fields standardised, the deduplication engine runs a blocking pass to reduce the comparison space, then scores candidate pairs using a weighted combination of algorithms. A typical match scoring matrix for person records might look like:
- Last name (Jaro-Winkler): weight 0.30
- First name (Jaro-Winkler): weight 0.20
- Address (token overlap): weight 0.25
- Date of birth (exact): weight 0.25
Pairs scoring above a configured threshold (e.g. 0.85) are auto-merged. Pairs in a grey zone (e.g. 0.65–0.84) route to a human review queue. Everything below the lower threshold is kept as distinct records. All of this runs in memory on the host server — no cloud compute required.
Stage 4: Fuzzy matching and entity resolution
Deduplication handles a single dataset. Entity resolution links records across multiple source systems — connecting a person’s record in a claims database to their record in a credentialing system, even when no shared identifier exists. Match Data Pro’s integration of Senzing entity resolution is specifically designed for deployments where the engine runs entirely within the customer’s own infrastructure. Senzing’s graph-based probabilistic model is pre-trained; it does not phone home for inference.
The fuzzy matching pipeline handles field-level comparison: transposed digits in an ID number, a hyphenated surname entered as two words, a company name where “LLC” appears in some records and is absent in others. These variations are resolved by the algorithm stack, not by a remote API.
Stage 5: Job automation and scheduled outputs
Regulated environments almost always require recurring batch processing — nightly deduplication runs, weekly cross-system reconciliation, monthly compliance reporting. Job automation inside an air-gapped environment means the scheduler runs on the local host and writes outputs to an approved internal destination. Match Data Pro’s job automation layer supports cron-based scheduling with configurable output paths, logging to local targets, and alert routing through internal notification channels.
Audit Trails and Compliance in Isolated Pipelines
A match decision made inside a classified system is still a decision that must be auditable. Regulators — whether FedRAMP, HIPAA, or sector-specific frameworks — require that every record merge, every survivorship decision, and every rejected match pair can be traced back to specific inputs, algorithm versions, and threshold configurations in force at the time.
Match Data Pro logs match decisions with field-level scores, algorithm identifiers, and threshold values at the time of execution. Logs write to local targets. They are not sent to a cloud logging service. This is a hard requirement for air-gapped compliance that many platforms cannot meet.
Teams evaluating entity resolution for regulated environments should specifically test whether the vendor’s audit log mechanism requires any external connection to function. If the platform silently degrades to no logging when offline, that is a compliance failure.
Deployment Considerations: On-Premise vs. Private Cloud vs. True Air-Gap
True air-gap is the strictest constraint. Below it sit several related deployment models:
- Fully air-gapped: No network connectivity. All data, software, and model weights transferred physically. Used in defence and intelligence.
- Private cloud (isolated VPC): Connectivity exists but is restricted to internal endpoints only. Common in financial services and healthcare.
- On-premise with internet access: Software runs locally but can reach external endpoints for licence checks or updates. Not acceptable for classified workloads.
Match Data Pro’s on-premise option covers all three tiers. The same software package installs in a fully air-gapped rack, a private VPC, or a standard on-premise server room. The configuration differs; the core pipeline does not.
For teams that do not require air-gap isolation, the Match Data Pro cloud SaaS option offers the same complete pipeline — data cleansing, deduplication, entity resolution, and job automation — on a month-to-month subscription with no long-term contract. Register for a free trial to evaluate the full platform before committing.
For regulated teams that need an isolated deployment, schedule a technical demo to walk through deployment architecture, security controls, and compliance documentation.
Frequently Asked Questions
Can AI-powered data matching run without any internet connection?
Yes. Platforms designed for air-gapped deployment package all matching algorithms, model weights, and processing engines into a self-contained installation. No external API calls, licence check-ins, or model downloads are required at runtime. Match Data Pro’s on-premise option is built for exactly this constraint.
What data quality steps can be automated in an air-gapped environment?
All of them. Profiling, cleansing, standardisation, deduplication, fuzzy matching, entity resolution, and scheduled batch output can each run locally on the host server. Job automation handles recurring runs and writes logs to internal targets without requiring any outbound connection.
How do regulated teams update the matching software inside an air-gapped network?
Updates follow the same controlled ingestion process used for data: packaged artefacts are transferred via approved physical media or a one-way data diode, then deployed through the organisation’s internal software management system. Match Data Pro releases versioned update bundles designed for this process.
What is the difference between air-gapped and on-premise deployment?
On-premise means the software runs on customer-owned hardware, but may still reach external endpoints for licences or updates. Air-gapped means there is zero network path to any external system. A platform can be on-premise but not air-gapped. Air-gap is a stricter, physically enforced isolation requirement.
Does entity resolution work accurately without cloud compute?
Yes, if the engine uses pre-trained models and deterministic or probabilistic algorithms that run locally. Senzing, which Match Data Pro integrates, executes graph-based entity resolution entirely on the host. It does not require cloud inference. Accuracy is equivalent to cloud-based deployments given equivalent data quality inputs.