
Business intelligence initiatives fail when the underlying data is dirty, duplicated, or disconnected. No amount of dashboard sophistication compensates for a data layer where the same customer appears under three names, revenue figures double-count because of duplicate transactions, or CRM and ERP records for the same account never actually join. The root cause of most failed BI projects is not the tool — it is the data that feeds it.
Why Data Quality Is the Real BI Problem
Gartner estimates that poor data quality costs organisations an average of $12.9 million per year. Much of that loss flows directly through BI systems: reports that contradict each other, dashboards that analysts stop trusting, and executive decisions built on aggregates that double-count the same records.
Three failure patterns repeat across organisations:
- Duplicate entities inflating metrics. A customer appearing as “Acme Corp”, “ACME Corporation”, and “Acme Co.” is counted as three separate revenue sources. Churn models misfire. Lifetime value calculations are wrong.
- Inconsistent formats breaking joins. One system stores dates as YYYY-MM-DD. Another uses MM/DD/YYYY. A third stores them as text strings. The join fails silently, leaving 30% of transactions unmatched.
- Siloed sources with no resolved identity. CRM, ERP, and marketing automation each hold a version of the customer record. None share a primary key. BI tools see fragments, not a 360-degree view.
The fix is not a new BI tool. It is a data quality pipeline that runs before the data reaches the BI layer.
Book a demo to see how Match Data Pro prepares data for BI-ready pipelines.
The Six Data Quality Problems That Break BI
1. Duplicate Records
Duplicates are the most common and most damaging BI data problem. When the same entity — customer, vendor, product — appears multiple times in a source system, every aggregate metric is inflated. Sales totals overcounted. Contact lists padded. Segment sizes wrong.
Standard deduplication using exact-match rules misses 40-70% of real duplicates because real data is never perfectly consistent. “Jon Smith” and “Jonathan Smith” at the same address are the same person. Exact-match logic does not catch them. AI-powered fuzzy matching deduplication scores similarity across name, address, phone, and email fields simultaneously, catching near-duplicates that exact-match misses entirely.
2. Unstandardised Fields
Field format inconsistency is the silent killer of BI joins. Consider a revenue field containing: “$1.2M”, “1200000”, “1,200,000.00”, and “1.2 million”. All four mean the same thing. Aggregation functions treat them as four different values — or null out three of them.
Data standardisation normalises every field to a consistent format before data reaches the BI layer. That means consistent date formats, numeric precision, text case, unit notation, and categorical encoding across every source system.
3. Null and Incomplete Values
Null rates above 15% in a key field degrade BI accuracy severely. A customer segment analysis where 20% of records have no industry code produces segments that are systematically biased. Reports built on incomplete data consistently undercount the groups with the worst data hygiene — which are often the groups most worth analysing.
Data profiling surfaces null rates, format violation counts, and outlier distributions before cleansing begins. It is the diagnostic step that tells you exactly which fields need remediation and by how much.
4. Unresolved Entity Identities
When the same real-world entity — a company, a person, a product — appears with different identifiers across source systems, BI tools cannot link them without help. A customer in Salesforce with ID “SF-10042” maps to account “ERP-99187” in SAP. Without entity resolution, those two records are never joined. Revenue attribution is split. The customer journey is broken.
Entity resolution matches records across systems using configurable fuzzy scoring and graph-based clustering — no shared key required. Match Data Pro includes Senzing entity resolution, which handles high-volume cross-system identity matching at production scale.
5. Invalid Address Data
Address fields are some of the dirtiest in any database. Typos, missing ZIP codes, non-standard formats, and outdated records degrade geographic BI analysis — territory reporting, regional revenue splits, and logistics dashboards all depend on clean, verified postal data. CASS address verification validates and corrects postal records against the USPS database, standardising street names, cities, and ZIP codes before they enter the data warehouse.
6. No Automated Refresh
Data quality is not a one-time project. Address records decay at 15-20% per year. New records enter systems daily. Without an automated refresh pipeline, the gains from an initial cleansing project erode within months. BI dashboards that were accurate in January become unreliable by June.
Job automation schedules recurring data quality runs — nightly, weekly, or triggered by API events — so the data layer stays current without manual intervention.
The Six-Stage Pipeline for BI-Ready Data
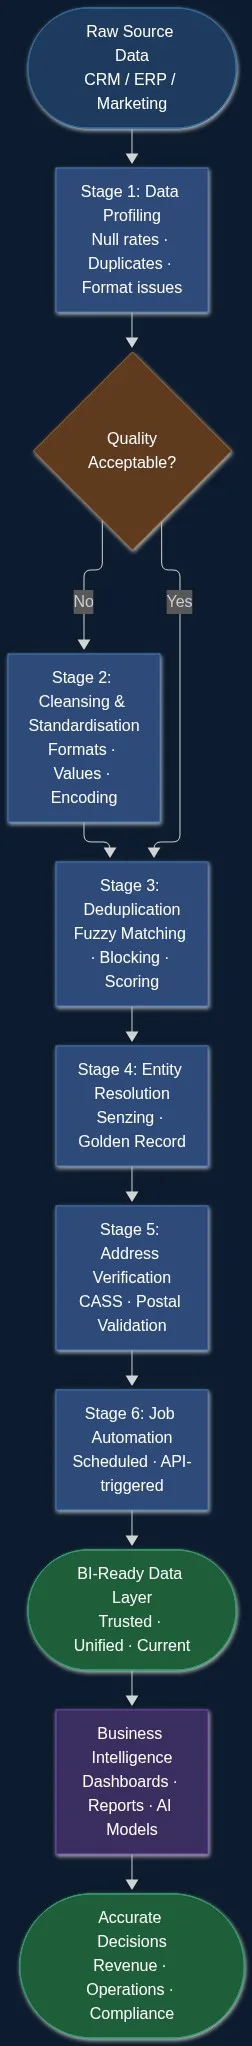
The diagram below shows the pipeline that transforms raw source data into a trusted BI-ready data layer.
Stage 1: Profile Every Source Dataset
Before any cleaning begins, profiling gives you a quantified view of data health: null rates per field, duplicate density, format violations, and outlier distribution. A typical enterprise dataset surfaces 12-18 distinct quality issues at this stage. Without profiling, cleansing is guesswork.
Match Data Pro’s AI data profiling scans every field automatically, scores quality dimensions, and generates a remediation priority list — so the team focuses effort where it has the most impact.
Stage 2: Cleanse and Standardise
Cleansing corrects individual field errors: wrong formats, truncated values, encoding issues, placeholder entries (“N/A”, “999-999-9999”, “test@test.com”). Standardisation normalises consistent representations across sources. Both steps must run before deduplication — matching on dirty fields produces false positives and missed matches.
Stage 3: Deduplicate Using Fuzzy Matching
With fields standardised, fuzzy matching identifies near-duplicate records across each source dataset and across datasets. The matching engine applies multiple algorithms — Jaro-Winkler for names, token-based matching for addresses, phonetic encoding for name variants — with field-weighted composite scoring. Records above a threshold are merged; borderline cases are routed to review.
Example: Before deduplication, a CRM holds 48,000 account records. After deduplication, 41,200 unique entities remain. Revenue figures drop by 14% — not because revenue fell, but because duplicate accounts were double-counting it.
Stage 4: Resolve Entities Across Systems
Entity resolution links records that refer to the same real-world entity across separate systems. It operates after per-source deduplication and before the data warehouse load. This step produces the persistent cross-system identity — the golden record — that BI tools join against.
Stage 5: Verify Addresses
CASS verification runs against every address record, correcting street abbreviations, standardising city and state formats, appending ZIP+4 codes, and flagging undeliverable addresses. Geographic BI analysis — territory maps, regional dashboards, delivery heatmaps — depends on this step.
Stage 6: Automate and Monitor
The pipeline runs on a schedule. Match Data Pro’s job automation executes each stage — profiling, cleansing, deduplication, entity resolution, address verification — on a configured cadence. Exceptions are logged. Thresholds trigger alerts. The BI layer receives fresh, validated data without manual intervention.
What Changes When BI Gets Clean Data
The operational impact is measurable and fast. Teams that run a structured data quality pipeline before BI implementation typically see:
- Duplicate-driven metric inflation drops 10-25%
- Report reconciliation time cuts by 60-80%
- Analyst time spent on “why are these numbers different?” conversations drops sharply
- Confidence in dashboard outputs increases — which means dashboards actually get used
The more important change is structural. When BI outputs are trusted, decisions accelerate. Territory managers act on regional dashboards instead of building their own spreadsheets. Finance closes faster because source data matches. Marketing segments are accurate, so campaign targeting improves.
Connecting Data Sources Without a Shared Key
Many organisations assume cross-system BI joins require a shared identifier — an account ID or customer number that exists in every system. In practice, that shared key rarely exists across the full data estate. CRM systems assign their own IDs. ERP systems assign theirs. Data warehouses ingest both without resolving the overlap.
Record linkage without a shared key is a core capability of a production-grade data quality platform. Match Data Pro matches records across systems using configurable fuzzy scoring on name, address, phone, email, and custom fields — building a cross-system entity graph that BI tools can join against reliably. Data matching software that handles this at scale is the missing layer most BI stacks lack.
Start your free trial of Match Data Pro and run the pipeline on your own data — no contract required.
Preguntas frecuentes
Why do BI initiatives fail even with good dashboards and reporting tools?
BI tools visualise what they receive. If the underlying data contains duplicates, inconsistent formats, and unresolved entity identities, the dashboards surface those problems as conflicting figures and untrustworthy metrics. The tool is rarely the issue — the data pipeline feeding it is. A six-stage data quality pipeline resolves most of these problems before data reaches the BI layer.
How do duplicate records affect BI metrics specifically?
Duplicate records inflate every aggregate metric they touch. If a customer appears three times in a CRM, revenue from that customer is counted three times in revenue reports. Churn calculations treat each duplicate as a separate account, distorting retention rates. Customer count is overstated. The fix is fuzzy deduplication run before the data warehouse load, not after.
What is entity resolution and why does BI need it?
Entity resolution links records that refer to the same real-world object — a company, person, or product — across separate systems that use different identifiers. BI tools need a resolved identity to correctly join CRM revenue data with ERP order data for the same account. Without entity resolution, those records appear as separate entities and are never aggregated together accurately.
How often should a data quality pipeline run to keep BI data accurate?
Address data decays at roughly 15-20% per year. New records enter CRM and ERP systems daily. At minimum, deduplication and standardisation should run weekly. Address verification should run on every new record at point of entry. For high-velocity environments, a full pipeline run nightly — triggered by API or scheduled job — keeps the BI data layer within acceptable freshness thresholds.
Can Match Data Pro connect to our existing data warehouse and BI stack?
Yes. Match Data Pro includes import/export connectors for common formats and databases, plus a live fuzzy search API for real-time integration. The platform outputs clean, deduplicated, entity-resolved data that loads directly into your data warehouse — Snowflake, Redshift, BigQuery, SQL Server, or any JDBC target. It sits upstream of your BI tool, not inside it.