
Data interoperability fails when records from one system cannot reliably map to records in another. Record matching — the practice of identifying which records across disconnected systems refer to the same real-world entity — is the mechanism that makes interoperability work in practice. Without it, every integration project inherits the same siloed, inconsistent data it was meant to fix.
Ready to eliminate silo-driven data failures? Start a free trial of Match Data Pro and connect your first sources in minutes.
What Data Interoperability Actually Requires
Interoperability is often framed as a technology problem: APIs, connectors, common schemas. Those help. But the deeper problem is semantic. Two systems may store the same customer as “Acme Corp.” and “ACME Corporation, Inc.” — different strings, same entity. No API solves that without a matching layer underneath.
Three conditions must be true before data from two systems can be reliably combined:
- Structural alignment: fields, types, and formats conform to a shared schema.
- Semantic alignment: the same concept is represented the same way (e.g., “United States” not “US” or “USA”).
- Entity alignment: records that represent the same real-world object are linked under a shared identifier.
Most integration projects handle the first condition adequately and ignore the second and third entirely. That is why 60–70% of integration projects report persistent data quality problems post-go-live.
Data standardisation handles semantic alignment. Record matching and entity resolution handle entity alignment. Both must run before data crosses system boundaries.
How Data Silos Form and Why They Persist
Silos are a structural outcome of how enterprise systems are purchased and deployed. A CRM is bought to manage customer relationships. An ERP is bought to manage operations. A marketing automation platform is bought to run campaigns. Each is optimised for its own purpose, with its own data model and no requirement to share a common entity identifier with adjacent systems.
Over time, the same customer accumulates records across all three:
| System | Récord | Name field | DIRECCIÓN |
|---|---|---|---|
| CRM | CRM-00291 | Johnson Medical Group | 1240 N. Oak Ave, Suite 3 |
| ERP | CUST-8812 | Johnson Med Grp | 1240 N Oak Avenue |
| Marketing DB | MKT-55901 | Johnson Medical | 1240 N Oak Ave Ste 3 |
Three records. One customer. No shared key. An exact join returns zero results. The silo persists not because of infrastructure but because nothing has resolved which records belong to the same entity.
Data profiling is the first step to quantifying how severe this fragmentation is across your sources — measuring field-level null rates, format distributions, and preliminary duplicate counts before any matching begins.
The Record Matching Pipeline That Makes Interoperability Work
Solving interoperability through record matching requires a structured pipeline. Ad hoc SQL joins and manual deduplication do not scale past a few thousand records and introduce more errors than they remove. The pipeline below is the approach that works at enterprise volume.
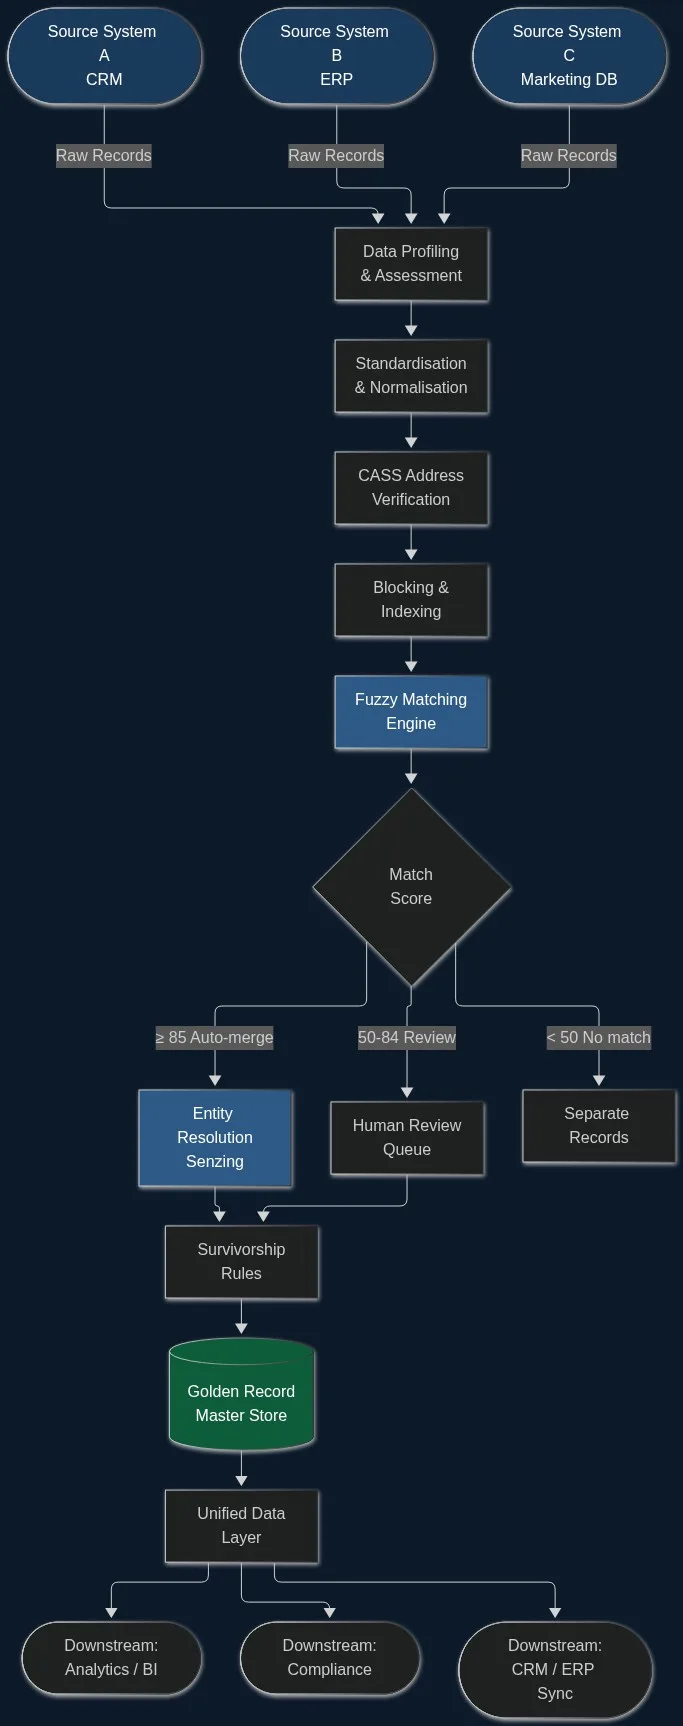
Stage 1: Profile Every Source
Before matching, you need to know what you are working with. Profiling quantifies null rates, format inconsistencies, and intra-source duplicate rates per field. A name field that is 15% null in the ERP and 2% null in the CRM changes your blocking and threshold strategy. Run profiling on each source independently before attempting any cross-source join.
Stage 2: Standardise and Normalise
Raw records from different systems carry different conventions. Apply consistent transformations: uppercase names, expand abbreviations (“Grp” to “Group”, “Med” to “Medical”), strip punctuation, normalise phone formats to E.164, and parse address components into discrete fields. Standardisation is what makes an approximate match possible between “Johnson Med Grp” and “Johnson Medical Group” — not in the raw form, but after both have been normalised to a canonical representation.
Stage 3: Verify Addresses with CASS
Address fields are the most common source of near-match failures across systems. “1240 N. Oak Ave, Suite 3” and “1240 N Oak Avenue” resolve to the same USPS delivery point — but only if you run them through CASS certification first. CASS address verification standardises every component, appends ZIP+4, and flags non-deliverable records before they enter the matching engine. This step alone eliminates 20–35% of false negatives in cross-system record matching.
Stage 4: Block and Index
Comparing every record from Source A against every record from Source B produces a quadratic number of comparisons — infeasible at scale. Blocking groups candidate pairs using a shared attribute (first three characters of a standardised name, ZIP code, or phone area code) so the matching engine only compares records that have a plausible similarity. A well-designed blocking strategy reduces comparison space by 95–99% while keeping recall above 98%.
Stage 5: Score with Fuzzy Matching
Fuzzy matching algorithms score each candidate pair on a 0–100 scale across multiple fields simultaneously. A weighted composite score might assign 40% weight to organisation name (Jaro-Winkler), 30% to address (token-based), 20% to phone (exact or Levenshtein), and 10% to postal code. For the Johnson Medical Group example, a well-tuned composite would return a score of 91 — well above an 85-point auto-merge threshold — despite the name and address variants across systems.
Algorithm selection matters per field type. Jaro-Winkler performs best on names. Levenshtein handles short codes and phone numbers. Token-based approaches (Jaccard, cosine) outperform on long free-text fields like company descriptions. Using a single algorithm across all fields is a common configuration error that drops precision by 10–20%.
Stage 6: Resolve Entities and Apply Survivorship
Fuzzy matching produces pair-level scores. Entity resolution takes those scores and builds clusters — groups of records that all refer to the same entity across all source systems. Match Data Pro integrates Senzing entity resolution, which uses graph-based probabilistic matching to cluster records at scale without hand-crafted rules. Once clusters are formed, survivorship rules determine which field value survives into the golden record: most recent, most complete, most trusted source, or a field-by-field rule set.
Where Interoperability Breaks Down in Practice
Even well-designed integration projects encounter predictable failure points. Knowing them in advance reduces rework.
Inconsistent Entity Identifiers
Many organisations use different internal IDs per system — customer IDs in CRM, account numbers in ERP, contact IDs in marketing platforms. When these IDs are not shared across systems (which is the norm), joins produce empty result sets or force expensive manual mapping exercises. Record matching replaces the need for a shared ID by linking records on content similarity rather than key equality.
Schema Evolution Without Governance
Source schemas change. A CRM upgrade renames “Account Name” to “Company”. A new ERP release splits a single address field into five components. Without active schema monitoring, these changes silently break your matching configuration months before anyone notices the downstream impact. Data quality monitoring that tracks field-level null rates and format distributions over time catches schema drift before it corrupts your interoperability layer.
High-Cardinality Name Variants
Organisation names accumulate variants over years of data entry: abbreviations, tradenames, parent-subsidiary relationships, acquisition renames. A hospital system may appear as “St. Mary’s Health”, “Saint Marys Healthcare”, “SMH”, and “St. Mary’s Hospital” across four sources — all the same entity. Managing name variants requires a preprocessing layer that expands known abbreviations, resolves legal suffixes, and strips noise tokens before fuzzy scoring begins.
Partial Records and Missing Fields
Many source systems contain records where critical matching fields — phone, email, or even full name — are missing. A matching engine that requires all fields present will reject these records as unmatchable, leaving gaps in your entity graph. The correct approach is field-weighted scoring that gracefully degrades: when a field is null, its weight is redistributed to present fields rather than triggering a zero-score rejection. Matching on incomplete data at 85–93% precision requires this null-tolerant configuration.
How Match Data Pro Breaks Down Data Silos
Match Data Pro is a cloud SaaS platform built to solve exactly these interoperability challenges. It runs the full pipeline described above — profiling, standardisation, CASS address verification, configurable fuzzy matching, Senzing entity resolution, and survivorship — in a single automated workflow with no long-term contract required.
Key capabilities that directly address interoperability failures:
- AI-powered fuzzy matching: Configurable multi-algorithm scoring with field-specific algorithm assignment and weighted composites. No single-algorithm limitations.
- Senzing entity resolution: Graph-based clustering that links records across three, five, or ten source systems simultaneously without requiring a shared primary key.
- CASS address verification: USPS-certified address standardisation and ZIP+4 appending applied before matching, eliminating address-variant false negatives.
- Live fuzzy search API: Real-time interoperability for applications that need to resolve an incoming record against your master store at point of entry — not in a nightly batch.
- Import/export connectors: Native connectors for CRM, ERP, and flat-file sources so ingestion does not require custom ETL development for every source system.
- Job automation: Scheduled pipelines that re-run profiling, matching, and entity resolution as source data changes — keeping your interoperability layer current without manual intervention.
The data matching and merging workflow in Match Data Pro handles the full cycle from raw multi-source ingestion to a verified golden record, with configurable thresholds for auto-merge, human review, and no-match routing.
Book a demo to see how Match Data Pro resolves cross-system entity conflicts on a sample of your own data in under 30 minutes.
Preguntas frecuentes
What is data interoperability and why does record matching matter for it?
Data interoperability is the ability to reliably combine and use data from different systems. Record matching matters because systems assign different identifiers to the same real-world entity. Without a matching layer, queries that span system boundaries return incomplete or duplicated results regardless of how well the technical integration is built.
Can APIs alone solve data interoperability problems?
No. APIs move data between systems but do not resolve semantic or entity-level differences. “Johnson Medical Group” in one system and “Johnson Med Grp” in another will remain two separate records even after an API integration unless a fuzzy matching and entity resolution layer is applied to link them into a single identity.
What is the difference between data integration and data interoperability?
Data integration is the technical process of moving and combining data — ETL pipelines, connectors, and APIs. Data interoperability is the semantic outcome: the ability to use that data reliably across systems. Integration without matching and standardisation delivers interoperability in structure only, not in meaning or identity.
How do you match records across systems that have no shared identifier?
Use fuzzy matching across content fields — name, address, phone, email — with a weighted composite score. Records that score above your auto-merge threshold are linked and clustered by entity resolution into a single golden record. This approach links 85–95% of true duplicates even with no shared key, depending on data completeness and threshold calibration.
How often should a cross-system record matching pipeline re-run?
At minimum, re-run the matching pipeline whenever source data is updated — typically daily for CRM and ERP systems. For high-velocity environments like e-commerce or financial services, real-time matching via a fuzzy search API at point of entry prevents new records from entering the system without immediate entity resolution, keeping the master store current continuously.