
Poor data quality is one of the most common — and most avoidable — causes of M&A value destruction. When two organisations merge, their customer, vendor, and financial databases contain duplicate records, inconsistent formats, and unverified addresses that collide on day one of integration. The result: delayed system cutovers, inflated customer counts, and decisions made on data that no one can trust. A structured data matching and deduplication pipeline applied before and during integration prevents those problems and directly protects deal value.
Ready to clean your data before integration day? Start a free trial of Match Data Pro — no contract required.
Why Data Quality Determines M&A Integration Speed
Integration timelines slip for many reasons, but dirty data is consistently near the top. Consider a mid-market acquisition where Company A carries 280,000 customer records in Salesforce and Company B carries 195,000 in HubSpot. Before deduplication, the combined figure appears to be 475,000 unique customers. After profiling, the real count is closer to 340,000 — a 28% overcount driven by duplicates across both systems.
That overcount matters because it inflates customer acquisition cost calculations, distorts churn rates, and causes the sales team to send duplicate outreach — damaging relationships with customers who just went through an acquisition and are already watching closely.
Beyond customer data, the same problem appears in:
- Vendor / supplier masters — duplicate supplier records across two ERP systems trigger duplicate payments and complicate spend analysis.
- Employee records — HR systems from both organisations contain overlapping records for shared contractors, consultants, and transferred staff.
- Product catalogs — overlapping SKUs with different naming conventions break cross-sell models on day one.
- Financial account data — inconsistent chart-of-accounts coding prevents clean financial consolidation and delays close cycles.
Every one of these problems is a data quality problem first, a systems integration problem second.
The Six-Stage M&A Data Quality Pipeline
The diagram below shows the six-stage pipeline Match Data Pro runs to consolidate two source databases into a unified master. Each stage is automated and auditable.
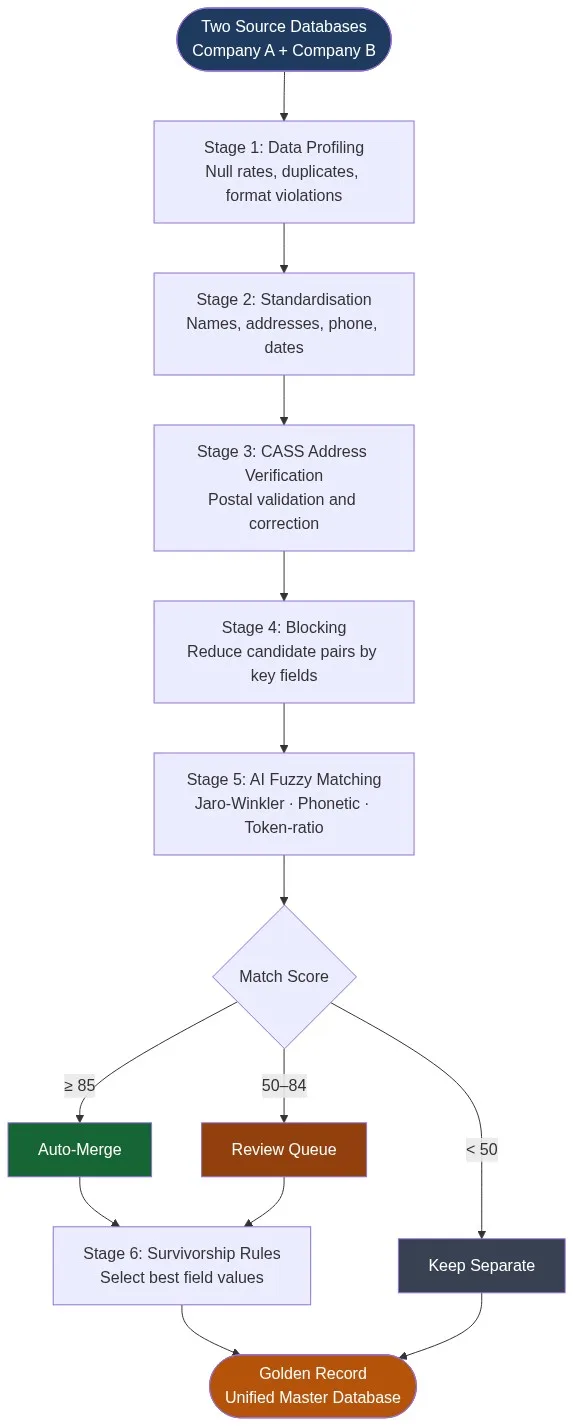
Fase 1: Perfilado de datos
AI data profiling scans every field in both source systems before a single record is touched. It produces null-rate reports, format-violation counts, value-distribution summaries, and a cross-system duplicate estimate. This baseline tells integration teams exactly where the problems are concentrated — typically 15–30% of records — before any remediation work begins.
A real profile output looks like this:
| Campo | Company A (null %) | Company B (null %) | Format conflicts |
|---|---|---|---|
| Teléfono | 8% | 14% | Mixed: (555) 123-4567 vs 5551234567 |
| Address line 2 | 31% | 22% | Ste vs Suite vs # |
| Estado | 2% | 6% | FL vs Florida |
| Correo electrónico | 4% | 9% | Case inconsistency |
These inconsistencies prevent exact-match joins from finding the same entity across databases. They must be resolved before matching begins.
Fase 2: Normalización
Match Data Pro’s cleansing engine normalises every field to a consistent format. Phone numbers become a uniform 10-digit string. State values are expanded to their full two-letter code. Company names are lowercased and stripped of legal suffixes (LLC, Inc., Corp.) so that “Acme Corp” and “ACME Corporation” score near-identically in the matching stage. Name parsing splits “Jonathan P. Smith” into first, middle, and last for field-weighted comparison.
Stage 3: CASS Address Verification
CASS address verification validates every postal record against the USPS database, corrects street abbreviations, appends ZIP+4 codes, and flags undeliverable addresses. In a typical M&A dataset, 8–12% of customer addresses have moved or are invalid. Identifying them before integration prevents bad data from propagating into the new master system.
Example correction:
| Raw input | CASS-verified output |
|---|---|
| 142 Oak St, Fl 3, Boston, MA | 142 Oak Street Floor 3, Boston, MA 02110-1234 |
| 55 W Main, Ste 400, Chicago, IL 60601 | 55 W Main Street Suite 400, Chicago, IL 60601-9823 |
Stage 4: Blocking
Comparing every record in database A against every record in database B is computationally impractical at scale. With 280,000 and 195,000 records respectively, a naive cross-join produces 54.6 billion candidate pairs. Blocking groups records into candidate buckets by shared key values — first three characters of last name plus ZIP code, for example — reducing the candidate set by 97–99% while retaining near-complete recall.
Stage 5: AI Fuzzy Matching
Within each candidate block, Match Data Pro scores every pair using a weighted combination of algorithms: Jaro-Winkler for name fields, Levenshtein for short codes, phonetic encoding for names prone to transcription error, and token-ratio for company names with word-order variation. Each field carries a configurable weight. A composite score above 85 triggers auto-merge; scores between 50 and 84 route to a human review queue; scores below 50 are kept as separate records.
Example scored pair:
| Campo | Registro A | Disco B | Puntuación | Peso |
|---|---|---|---|---|
| Apellido | Hendricks | Hendrix | 88 | 0.30 |
| Nombre | James | Jim | 71 (phonetic) | 0.20 |
| Correo electrónico | jhendricks@acme.com | j.hendrix@acme.com | 93 | 0.25 |
| Teléfono | 5551234567 | 5551234567 | 100 | 0.15 |
| Código postal | 60601 | 60601 | 100 | 0.10 |
| Compuesto | 89.6 |
A score of 89.6 clears the auto-merge threshold. The two records are the same person, despite name spelling variation and nickname use. Manual review would have missed or delayed this match in a dataset of hundreds of thousands of records.
Stage 6: Survivorship Rules and Golden Record Output
When two records merge, conflicting field values must be resolved. Survivorship rules define which source wins for each field: most-recently-updated email, longest non-null address, highest-confidence phone. The output is a golden record — a single authoritative entity that replaces both source records in the unified master. Every merge decision is logged with field-level provenance, so data stewards can audit any merged record and trace it back to its sources.
Common M&A Data Problems and Their Impact
Duplicate Customers
Duplicate customer records are the most frequent M&A data problem. They inflate CRM pipeline, cause double-outreach, and prevent accurate calculation of combined lifetime value. In a consumer-facing business, the same customer may appear in both databases with slightly different name spelling, an old versus new address, and different email domains — none of which an exact-match join catches. Data deduplication using fuzzy scoring resolves these at scale.
Duplicate Vendor Records
Overlapping supplier records between two ERP systems create duplicate payment risk. “Acme Supplies Inc.” in one system and “Acme Supplies” in another are the same vendor. Without fuzzy vendor matching, both records survive the migration and AP teams may pay the same invoice twice, or fail to apply volume discounts because spend is split across two vendor IDs. The deduplication pipeline described above applies equally to vendor master data.
Format Incompatibilities
Two companies running different ERP or CRM systems will almost certainly store the same data differently. Date formats (MM/DD/YYYY vs YYYY-MM-DD), country codes (US vs USA vs United States), and currency fields (1,000 vs 1000 vs $1,000.00) all create format-mismatch failures that break downstream analytics and reporting. Standardisation at the field level — before any data lands in the target system — prevents these failures from ever reaching production.
Incomplete Records
Acquisitions often bring in databases built to different operational standards. Company B’s CRM may have been used primarily for inbound leads and therefore has high email completion but low phone and address completion. Company A’s CRM was built for field sales and has the reverse profile. Merging incomplete records with survivorship rules — taking the non-null value from whichever source has it — produces a more complete golden record than either source alone. This is a direct data quality gain from the merger that a well-run pipeline captures automatically.
When to Run the Pipeline: Pre-Close vs. Post-Close
Many teams wait until after deal close to begin data quality work. That is a mistake. By the time systems integration begins, the pressure to cut over quickly overrides the pressure to clean up. The result is a dirty database migrated into the new target system, where it becomes the new normal.
The better model runs two passes:
- Pre-close due diligence pass — Profile both databases during the due diligence period. Quantify duplicate rates, null rates, and format violations. Use this data to estimate integration cost and timeline more accurately. This also informs deal valuation: a target with 35% duplicate customer records has lower effective database value than the raw count implies.
- Post-close integration pass — Run the full six-stage pipeline on both live databases. Deduplicate, standardise, verify addresses, and produce the golden record master. Load clean data into the target system and establish ongoing monitoring to catch new duplicates as they enter.
For the post-close pass, post-merger customer deduplication with a purpose-built platform typically takes days to weeks, not months. Match Data Pro’s job automation runs the pipeline on a schedule — so as new records enter the combined system, the deduplication logic continues to apply without manual re-runs.
Building a Unified Master: The Single Source of Truth
The end goal of M&A data integration is a single source of truth — one master database where every customer, vendor, and asset appears once, verified, and trusted. Achieving it requires more than a one-time deduplication run. It requires governance: rules that prevent duplicates from re-entering, monitoring that flags new quality issues before they accumulate, and a platform that makes ongoing quality management as automated as possible.
Match Data Pro supports this with:
- Scheduled job automation — deduplication and standardisation jobs run on a defined schedule against live data.
- Live fuzzy search API — new records entering the system are checked against the master in real time, flagging potential duplicates at point of entry.
- Entity resolution via Senzing — for complex multi-source entity resolution where graph-based identity linking is needed across many systems.
- Import/export connectors — pull data from CRM, ERP, and marketing platforms and push clean golden records back without manual file transfers.
The result is not just a clean database on integration day. It is a data quality program that sustains accuracy as the combined business grows.
See how the pipeline works on your data. Book a demo with a Match Data Pro data engineer, or start a free trial and run the deduplication pipeline on a sample of your integration data today.
Preguntas frecuentes
How much data duplication should I expect in a typical M&A integration?
Most organisations find 15–35% duplicate rates when two customer databases are profiled together. The exact figure depends on how long each database has been in use, how tightly data entry was governed, and how much customer overlap existed pre-merger. AI profiling quantifies this before remediation begins, giving integration teams an accurate baseline.
Can fuzzy matching handle company name variations like legal entity suffixes?
Yes. Before matching runs, a standardisation step strips legal suffixes (LLC, Inc., Corp., Ltd.) and normalises case and punctuation. Token-ratio algorithms then compare the remaining name tokens regardless of word order. “Acme Supplies, Inc.” and “ACME SUPPLIES LLC” will score above 90 and auto-merge in a correctly configured pipeline.
How long does M&A data deduplication take with Match Data Pro?
For datasets under 1 million records, the full six-stage pipeline — profiling, standardisation, CASS address verification, blocking, fuzzy matching, and survivorship — typically completes in hours to a few days depending on review queue volume. Match Data Pro’s job automation handles scheduling and parallel processing, so teams do not need to babysit the run.
Should data quality work happen before or after deal close?
Both. A profiling-only pass during due diligence quantifies database quality and informs deal valuation. The full deduplication and integration pipeline runs post-close. Starting the quality assessment early means the integration pipeline can begin immediately after close rather than weeks later when data quality issues are discovered for the first time.
What happens to records that do not match during deduplication?
Records that score below the match threshold are treated as unique entities and kept as separate records in the golden master. They are not discarded. Low-confidence pairs (scores between 50 and 84) route to a human review queue where a data steward can confirm or reject the match. This three-way routing — auto-merge, review, keep separate — preserves record completeness while maximising automation.