
Strong data governance fails when the data it governs is dirty, duplicated, and unstandardised. Governance policies define who owns data, who can change it, and what constitutes a valid record. But those rules only work if the underlying data is accurate, deduplicated, and structurally consistent. Without a sound data foundation, governance becomes an audit exercise over bad data rather than a control over good data.
This article explains why data foundations — profiling, cleansing, standardisation, deduplication, address verification, and entity resolution — are prerequisites for effective governance, and how to build them in a structured, repeatable pipeline.
What Is a Data Foundation and Why Does It Matter for Governance?
A data foundation is the set of processes and structures that ensure every record entering your systems is accurate, complete, consistently formatted, and free of duplicates. Governance policies depend on this foundation. Without it, policies are enforced on records that contradict each other, describe the same entity under different names, or contain values that violate the rules governance is supposed to enforce.
Consider a simple example. Your governance policy says every customer record must have a verified address and a unique identifier. But if your CRM contains:
- Row 1: “Acme Corp”, “123 Main St”, no ID
- Row 2: “ACME Corporation”, “123 Main Street Ste 4”, ID: 7721
- Row 3: “Acme Corp.”, “123 Main St.”, ID: 7721
All three records violate your governance rules in different ways. The policy is correct. The foundation is broken. Governance cannot fix that — only data quality tooling can.
Organisations that invest in AI data profiling before defining governance policies consistently identify structural issues that governance frameworks alone cannot resolve.
Ready to see what your data foundation really looks like? Start a free trial of Match Data Pro and run your first profiling scan in minutes.
The Seven Stages of a Strong Data Foundation
Building a data foundation is not a one-off clean. It is a staged pipeline that runs continuously as new data enters and existing data ages.
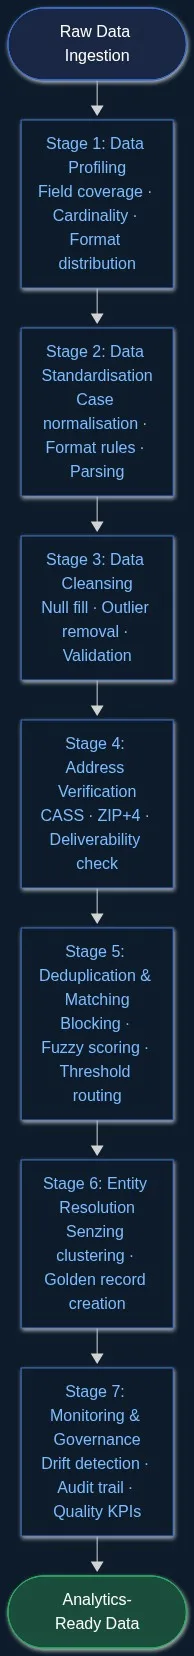
Fase 1: Perfilado de datos
Profiling scans every field for null rates, format distributions, cardinality, and outliers. It answers the question: what does the data actually look like right now? A profiling run on a 500,000-record CRM typically surfaces 12–18% null rates in key fields, 6–9% format violations, and 8–15% duplicate candidates before any cleansing begins. AI-powered data profiling automates this scan and produces a prioritised issue report rather than requiring analysts to write manual queries.
Fase 2: Normalización
Standardisation converts raw, source-specific formats into a uniform schema. Names become “FirstName LastName”. Phone numbers become E.164 format. Dates become ISO 8601. Company suffixes — “Inc.”, “Incorporated”, “Inc” — resolve to a single canonical form. Data standardisation is the stage where matching error rates drop by 30–50%, because algorithms compare consistent tokens instead of raw strings.
Fase 3: Limpieza
Cleansing removes or corrects values that fail validation rules. This includes removing placeholder entries (“N/A”, “test@test.com”), trimming whitespace, filling null fields from secondary sources, and flagging records that cannot be corrected automatically for human review. Automated data cleansing handles the high-volume cases without manual configuration per rule set.
Fase 4: Verificación de la dirección
Addresses degrade at roughly 10–15% per year as people and businesses move. CASS-certified address verification parses, standardises, and validates every postal address against the USPS master database, appending ZIP+4 codes and deliverability flags. A record with an unverifiable address cannot be treated as a trusted entity under any governance policy. Address cleansing and CASS verification resolves this before records reach your golden record pipeline.
Stage 5: Deduplication and Fuzzy Matching
Deduplication identifies records that describe the same real-world entity even when values differ. The three Acme Corp records above are a classic case. A blocking step groups candidate pairs by first-token or ZIP code to avoid O(n²) comparison costs. Fuzzy scoring algorithms — Jaro-Winkler for names, token ratio for addresses — assign a 0–100 similarity score to each pair. Pairs above a high threshold (e.g., 92+) auto-merge. Pairs in a review band (75–91) route to a human queue. Data deduplication in practice reduces duplicate rates from 12–20% in raw CRM data to under 1% in a governed master file.
Etapa 6: Resolución de entidades
Entity resolution extends deduplication across systems. Where deduplication consolidates duplicates within a single dataset, entity resolution links records across CRM, ERP, marketing platforms, and third-party sources into a single identity graph. Entity resolution powered by Senzing uses graph-based probabilistic matching to cluster records without requiring a shared identifier. The output is a golden record — the authoritative representation of each entity across all source systems.
Stage 7: Monitoring and Governance Integration
A foundation is not static. New data enters daily. Records change. Sources evolve. Continuous data quality monitoring tracks completeness, format compliance, duplicate rates, and address deliverability in real time. When a metric breaches a threshold — say, duplicate rate rises above 3% — an alert fires before governance auditors discover the problem. Audit trails record every change: what was modified, when, by which pipeline step, and what the previous value was.
How Governance Policies Build on a Clean Foundation
Once the foundation is in place, governance policies have concrete data to operate on. Consider three common governance requirements:
Data Stewardship
Stewardship assigns ownership of records or domains to named individuals. Stewards can only perform their role when records are identifiable, non-duplicated, and standardised. If the same supplier exists as 14 variants across ERP and procurement, no steward can maintain one authoritative view without deduplication first. Vendor master data cleansing is a common first step in operationalising supplier data stewardship.
Compliance and Auditability
Regulatory frameworks — GDPR, CCPA, HIPAA — require organisations to locate, correct, or delete a subject’s data on request. That is impossible if the same subject exists as 7 near-duplicate records across three systems. Entity resolution creates the identity linkage that makes compliance requests actionable. The audit trail generated by a data quality pipeline provides the evidence regulators and auditors expect.
Data Quality SLAs
Governance frameworks increasingly include data quality SLAs: commitments that a dataset will maintain a minimum completeness of 98%, a duplicate rate below 2%, and an address deliverability rate above 95%. These SLAs are only measurable — and enforceable — if profiling and monitoring are running continuously against a clean, standardised dataset.
Common Failure Patterns When Foundations Are Weak
Teams that implement governance without fixing foundations encounter predictable problems:
- Policy drift: Rules are defined but not enforced at ingest, so new dirty records bypass the governance layer immediately.
- Shadow datasets: Analysts create their own cleaned extracts because the governed master is unreliable, undermining the single source of truth.
- Audit failures: Regulators request a subject’s data. The team cannot confidently identify all records belonging to that subject because entity resolution was never implemented.
- Steward burnout: Data stewards spend 60–70% of their time manually resolving format inconsistencies and duplicates rather than enforcing policy.
Each of these is a foundation problem, not a governance policy problem. Rewriting governance policies does not fix them.
Ready to build a foundation your governance program can rely on? Start a free trial of Match Data Pro and run your first profiling and deduplication job in under 30 minutes — no contract required.
Building the Foundation with Match Data Pro
Match Data Pro is a cloud SaaS platform that covers every stage of the data foundation pipeline in a single, no-code environment. Data engineers, CRM leads, and IT teams use it to:
- Run AI data profiling across CSV, Excel, and database sources in minutes
- Standardise and cleanse fields using configurable rule sets and automated transformation pipelines
- Verify postal addresses with CASS certification, appending ZIP+4 codes and deliverability flags
- Deduplicate records using configurable fuzzy matching algorithms — Jaro-Winkler, Levenshtein, phonetic, token-ratio — with weighted field scoring
- Resolve entities across systems using Senzing’s graph-based probabilistic matching engine
- Apply survivorship rules to build golden records from merged source data
- Monitor quality in real time and generate governance-grade audit trails
- Automate the full pipeline on a schedule via job automation and drift monitoring
The platform deploys as cloud SaaS with no infrastructure overhead and no long-term contract. Teams typically complete their first full deduplication run within 24 hours of registration.
Book a live demo to see the full pipeline — from raw data to governed golden records — with your own use case.
Preguntas frecuentes
What is the difference between data governance and data quality?
Data quality is the state of your data — how accurate, complete, consistent, and deduplicated it is. Data governance is the set of policies, roles, and processes that define how data should be managed. Governance without quality produces well-documented bad data. Quality without governance produces clean data with no accountability structure. Both are necessary; quality is the prerequisite.
Why does data governance fail without clean data foundations?
Governance policies depend on data being identifiable and non-duplicated. If the same entity exists as multiple conflicting records, stewards cannot manage it, compliance teams cannot locate it, and SLAs cannot be measured against it. The governance framework becomes a set of rules applied to data that systematically violates them.
How do you build a data foundation before implementing governance?
Run profiling first to quantify the problem. Then standardise formats, cleanse invalid values, verify addresses, deduplicate within each source, and resolve entities across sources. Output a golden record per entity. Only then do governance policies have a stable, identifiable record set to operate on. The full pipeline typically takes two to six weeks for a mid-size CRM dataset.
What is entity resolution and why is it important for governance?
Entity resolution links records across systems that refer to the same real-world entity — even without a shared identifier. It is essential for governance because compliance requests (GDPR, CCPA) require finding all records for a subject across every system. Without entity resolution, compliance teams manually search multiple databases and miss records, creating regulatory exposure.
How often should a data foundation be maintained?
Continuously. Address data degrades at 10–15% per year. New records enter CRM and ERP systems daily. Duplicate rates rise within weeks of a data migration. The foundation pipeline — profiling, cleansing, deduplication, entity resolution — should run on an automated schedule, with drift alerts firing when any quality metric breaches its SLA threshold.