
Audit logs for data compliance record every change made to your records — who changed what, when, and what the value was before and after. Under GDPR, HIPAA, SOX, and similar frameworks, regulators do not just want clean data; they want demonstrable proof that data has been handled correctly over time. Without automated audit trails, organisations face discovery gaps during audits, remediation delays, and regulatory fines that run into millions of dollars.
Start a free trial of Match Data Pro and see how automated data pipelines generate governance-grade audit trails by default.
Why Audit Logs Are a Compliance Requirement, Not an Option
Regulators across every major framework require documented evidence that data changes are traceable. GDPR Article 30 requires records of processing activities. HIPAA’s Security Rule mandates audit controls for all systems handling protected health information. SOX Section 302 requires executives to certify the accuracy of financial data, which is impossible without a reliable change log.
The 2023 IBM Cost of a Data Breach Report put the average breach cost at $4.45 million. A significant portion of that cost comes from the inability to quickly identify what data was affected and when. Organisations with mature audit logging capabilities contain breaches 28% faster on average.
Audit logs serve four distinct compliance functions:
- Accountability: Links every record change to a named user or automated process
- Detectability: Surfaces unauthorised modifications through anomaly alerts
- Recoverability: Provides the before-state needed to roll back bad changes
- Reportability: Generates regulator-ready exports on demand
What Audit Logs Must Capture
Many teams log at the application level — recording that a user clicked “save” — but miss the data-level detail regulators actually require. A compliance-grade audit entry needs six fields at minimum.
The six required fields
- Record identifier: The primary key or entity ID of the affected record
- Change type: Insert, update, delete, merge, or flag
- Field name: Which specific field changed
- Before value: The exact previous value
- After value: The new value post-change
- Timestamp and actor: UTC timestamp plus the user ID or system process name
Consider a customer record where the address is updated during a data standardisation run:
| Campo | Audit Entry Detail |
|---|---|
| ID del registro | CUST-00482 |
| Change Type | Update |
| Campo | address_line_1 |
| Antes | 123 main st ste 4 |
| After | 123 Main Street, Suite 4 |
| Actor | MDP-CASS-JOB-20261107 |
| Marca de tiempo | 2026-11-07T09:14:33Z |
That single log entry proves the change was made by an automated, authorised process — not a human with unknown intent. During a HIPAA audit, that distinction matters enormously.
The Automation Problem: Why Manual Logging Fails
Manual audit logging breaks in three common scenarios.
High-volume pipelines
A data quality pipeline processing 500,000 records per night cannot rely on human-triggered log entries. Even a one-second manual log entry per record would take six days. Automated data cleansing pipelines must generate audit events natively, as part of the execution engine — not as a post-processing afterthought.
Merge and deduplication operations
When deduplication merges two customer records into one golden record, the audit trail must document which source records contributed, which field values survived (and which were discarded), and what survivorship rule was applied. A simple “record updated” log entry is not sufficient for a compliance review.
Cross-system entity resolution
When entity resolution links a record from your CRM to a matching record in your ERP, the audit log must capture the linkage event: which algorithm fired, what confidence score was produced, and which user or threshold rule authorised the merge. This granularity is what separates a compliant data pipeline from a liability.
How Match Data Pro Automates Audit Trails Across the Data Quality Pipeline
Match Data Pro generates structured audit log entries at every stage of the data quality pipeline. No custom coding is required. Each job run produces a timestamped, field-level record of every change applied to every record.
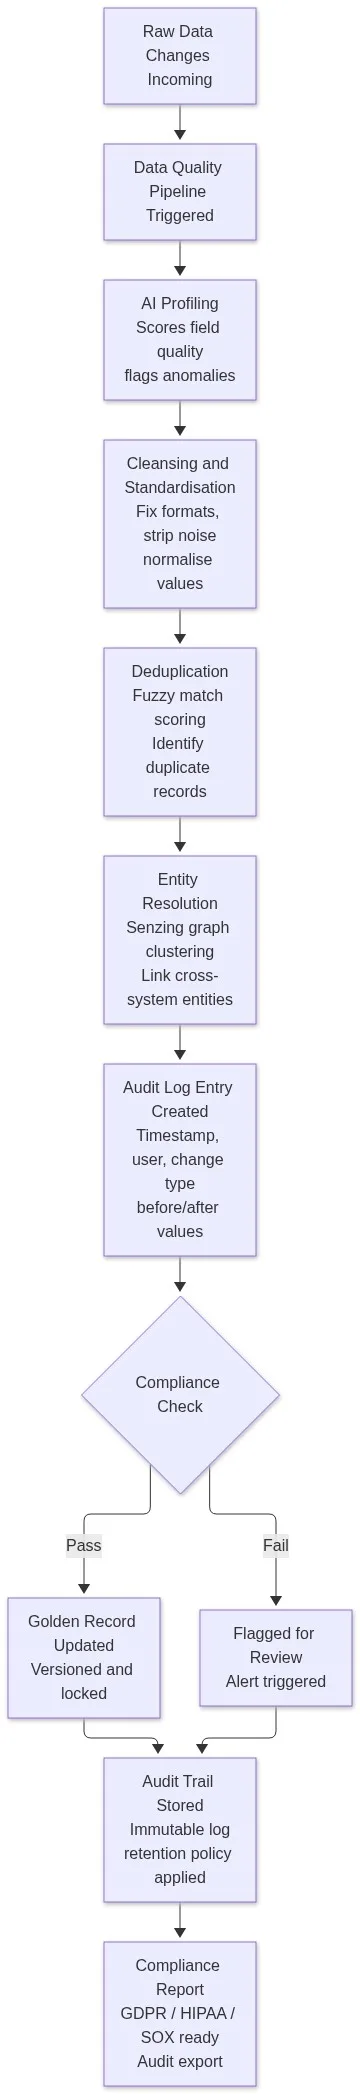
Stage 1 — AI data profiling
The pipeline begins with AI data profiling, which scans every field across the dataset and flags quality issues: null rates, format violations, outliers, and duplicate candidate clusters. The profiling report is timestamped and stored as part of the job record, giving compliance teams a baseline snapshot of data health before any changes are made.
Stage 2 — Cleansing and standardisation
Every cleansing operation — stripping illegal characters, normalising phone formats, uppercasing name fields — writes a before/after log entry. Data standardisation rules are version-controlled, so if a rule changes, the audit trail reflects which rule version was active at the time of each transformation.
Stage 3 — CASS address verification
CASS address verification validates postal records against the USPS delivery database and appends ZIP+4 codes. Each verification writes an audit entry: the original address, the corrected address, the verification result code (valid, corrected, undeliverable), and the job timestamp. This is essential for organisations subject to CAN-SPAM, HIPAA, or state-level data accuracy laws.
Stage 4 — Fuzzy matching and deduplication
When the fuzzy matching engine identifies duplicate candidates, each pair receives a composite match score. The audit log captures: source record IDs, individual field scores (name: 94, address: 88, phone: 71), the composite threshold crossed, and the merge decision. If a human reviewer overrides an automated decision, that override is logged separately with the reviewer’s ID.
Stage 5 — Entity resolution
Senzing-powered entity resolution links records across systems into a unified entity graph. Every link event — including the evidence chain that caused two records to be associated — is written to the audit log. Regulators reviewing a GDPR right-to-erasure request can query the audit trail to find every system where a subject’s data appears and every transformation it has undergone.
Stage 6 — Survivorship and golden record creation
When survivorship rules determine which field values populate the golden record, the audit trail records the decision logic: “field: email; source: CRM; rule: most-recent; discarded value: ERP.” This level of traceability is required for financial data under SOX and for health records under HIPAA’s minimum necessary standard.
Retention, Immutability, and Export
Three operational requirements separate a defensible audit log from a theoretical one.
Immutability
Audit log entries must not be editable after creation. Write-once storage or cryptographic hashing of log entries prevents retroactive tampering. During a regulatory audit, the ability to demonstrate that log entries have not been modified since creation is as important as the log content itself.
Retention policy alignment
GDPR requires personal data to be retained only as long as necessary for the original purpose. HIPAA requires medical record audit logs for six years. SOX requires financial record trails for seven years. Your data platform must support configurable retention policies that align per-dataset — not a single global setting. Match Data Pro’s data quality program configuration supports dataset-level retention rules out of the box.
On-demand export
When a regulator requests audit evidence, the response window is typically 30 to 72 hours. Audit logs stored in a queryable format — not buried in flat log files — allow compliance teams to filter by date range, record ID, change type, or actor and produce a formatted export within minutes rather than days.
Connecting Audit Trails to Broader Data Governance
Audit logs are most powerful when connected to a wider data governance foundation. A clean, deduplicated, standardised dataset with an attached audit trail gives compliance officers one authoritative answer to every regulator question: “Show me everything that happened to this record.”
Organisations that treat audit logging as an afterthought — bolted onto existing systems after go-live — pay significantly more in remediation costs when regulators ask questions the logs cannot answer. The right approach is to build audit trail generation into the data quality pipeline from the start, so every transformation is documented as it happens.
Match Data Pro’s cloud SaaS platform deploys in hours, requires no long-term contract, and generates compliance-grade audit trails automatically across every job run. Book a demo to see the audit trail interface and compliance export workflow in action.
Preguntas frecuentes
What is an audit log in data compliance?
An audit log in data compliance is a timestamped, field-level record of every change made to a dataset — capturing who changed which field, the before and after values, and the system or user that triggered the change. Compliance frameworks including GDPR, HIPAA, and SOX require organisations to maintain these records to demonstrate accountability and support regulatory investigations.
What must a compliance-grade audit log capture?
A compliance-grade audit log must capture at minimum: the affected record identifier, the type of change (insert, update, delete, merge), the specific field changed, the before value, the after value, the UTC timestamp, and the actor (user ID or system process). Logs that capture only high-level events such as “record saved” do not meet the field-level traceability required by most regulators.
How long should audit logs be retained for compliance?
Retention periods vary by framework. SOX requires financial data audit trails for seven years. HIPAA requires medical record audit logs for six years from creation or last use. GDPR requires personal data audit trails to be retained only as long as the data itself is lawfully held, then securely deleted. Configure per-dataset retention policies that align to the most stringent applicable framework for each data domain.
How does automated data deduplication affect audit log requirements?
Automated deduplication creates complex audit events because a single merge operation combines multiple source records into one golden record. Each merge must log the contributing source record IDs, field-level survivorship decisions (which value was kept and why), the match score, and the rule that triggered the merge. Manual logs rarely capture this level of detail, making automated, pipeline-native audit generation essential.
Can Match Data Pro generate audit logs automatically?
Yes. Match Data Pro generates structured, field-level audit log entries automatically at every stage of the data quality pipeline — profiling, cleansing, standardisation, deduplication, address verification, and entity resolution. Each job run produces a timestamped, queryable audit record. Logs are exportable on demand in formats suitable for regulatory submissions, with configurable retention policies per dataset.