
Connecting an LLM or AI workflow to your operational data produces accurate, trusted outputs only when the underlying data is clean, deduplicated, and unified. Dirty data fed into a retrieval-augmented generation (RAG) pipeline or a fine-tuning dataset produces contradictory context, inflated token counts, and factually wrong model responses. The fix is a structured data quality foundation built before the AI layer, not patched after it.
Ready to give your AI workflows a clean data foundation? Start a free trial of Match Data Pro and profile your first dataset in minutes.
Why LLM Data Quality Determines Output Quality
Language models do not reason from first principles. They pattern-match against the context they receive. In a RAG system, that context comes directly from your data store. In a fine-tuned model, it comes from your training corpus. In both cases, the model can only be as accurate as the records it retrieves or was trained on.
Three data problems damage LLM output most severely:
- Duplicate records. A customer who appears as “Acme Corp”, “ACME Corporation”, and “Acme, Inc.” in your CRM gives the model three conflicting entity representations. The model cannot determine which revenue figure, address, or account status is authoritative.
- Inconsistent formats. Dates stored as “11/06/2026”, “06-Nov-26”, and “2026-11-06” in the same field confuse temporal reasoning. Phone numbers with and without country codes break entity linking.
- Unresolved entities. When “Robert Johnson”, “Bob Johnson”, and “R. Johnson” in three systems are not linked to a single person, any AI summary of that person’s history will be incomplete or contradictory.
Research into LLM hallucination consistently finds that contradictory training or retrieval data is a primary driver of confident but wrong model responses. The model is not malfunctioning — it is accurately reflecting the ambiguity in the data it was given. Understanding why AI hallucinates starts with understanding where the bad data comes from.
The 7-Stage Pipeline to Build a Clean AI Data Foundation
The diagram below shows the full pipeline. Each stage removes a category of data quality problem before records reach the AI layer.
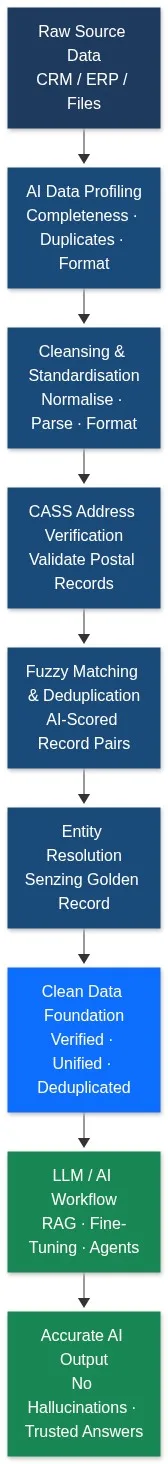
Fase 1: Perfilado de datos para IA
Profiling scans every field across every source dataset and returns a structured quality report. For a 500,000-row CRM export, a profiling run might show: 14% null company names, 23% phone numbers with inconsistent formats, 8,200 duplicate email addresses, and 4% of addresses outside deliverable ranges. Without this baseline, you cannot prioritise what to fix or measure improvement.
Match Data Pro’s AI data profiling runs automatically on import, producing field-level quality scores and flagging anomalies before any downstream processing begins.
Fase 2: Limpieza y estandarización
Standardisation converts free-form values into a uniform format. This matters specifically for LLM pipelines because retrieval systems use string matching and semantic similarity to fetch relevant records. If the same company is stored as “Ltd.”, “Limited”, and “Ltd” in different records, semantic search may not surface all three. Worse, a fine-tuned model trained on the raw data learns three representations of one entity as if they were distinct.
Key standardisation tasks for AI pipelines include:
- Name case normalisation (“JOHN SMITH” to “John Smith”)
- Legal suffix normalisation (“Corp.”, “Corp”, “Corporation” to a canonical form)
- Date and phone number formatting to ISO or E.164 standards
- State and country code expansion (“CA” to “California”, “US” to “United States”)
- Null handling — deciding whether a missing value is truly absent or a data entry failure
The data standardisation pipeline in Match Data Pro applies configurable transformation rules across all fields before fuzzy matching runs.
Stage 3: Address Verification
Address fields are uniquely problematic for AI pipelines. A model trained on records containing “123 Main St Ste 4B”, “123 Main Street Suite 4B”, and “123 Main St #4B” may treat these as three distinct locations. CASS address verification parses, corrects, and standardises every address against the USPS master file, assigning a consistent DPV-confirmed deliverable form.
Match Data Pro’s CASS address verification runs at the field level and returns standardised address components (street, city, state, ZIP+4, plus4) that the entity resolution stage can then use as match keys.
Stage 4: Fuzzy Matching and Deduplication
After standardisation, records that refer to the same entity still differ in ways that exact matching cannot catch. Fuzzy matching scores record pairs across multiple fields simultaneously and routes pairs to auto-merge, review, or reject buckets based on configurable thresholds.
A typical composite score for a customer record might weight fields as follows:
| Campo | Algoritmo | Peso |
|---|---|---|
| Nombre de empresa | Índice de clasificación de fichas | 35% |
| Línea 1 de la dirección | Jaro-Winkler | 25% |
| Teléfono | Exacto (normalizado) | 20% |
| Email domain | Exacto | 15% |
| Código postal | Exacto | 5% |
Pairs scoring above 85 auto-merge. Pairs between 65 and 85 go to a review queue. Below 65, they remain separate. This keeps false positives out of the golden record while flagging genuine ambiguity for human review.
Read more about fuzzy matching algorithms, scoring, and threshold configuration in our technical guide.
Etapa 5: Resolución de entidades
Fuzzy matching deduplicates within a single dataset. Entity resolution links records across multiple source systems — CRM, ERP, marketing platform, support tickets — into a single golden record. This is the step that eliminates the scenario where a customer appears as three different entities across three systems, each contributing contradictory context to an AI query.
Match Data Pro uses Senzing entity resolution to cluster cross-system records. Senzing applies probabilistic scoring across all available fields and builds persistent entity IDs that survive schema changes and new source additions. The golden record it produces carries the most complete and reliable field values from all contributing sources — survivorship logic determines which value wins when sources conflict.
Stage 6: Job Automation and Continuous Refresh
A clean data foundation is not a one-time output. AI pipelines that read from operational data stores need that data to remain clean as records change. Match Data Pro’s job automation runs the full pipeline — profile, cleanse, verify, deduplicate, resolve — on a schedule or triggered by an import event. New records from connected systems pass through every quality gate before they reach the data layer that the AI reads.
Import and export connectors support CSV, Excel, JSON, XML, and direct database connections, so the pipeline integrates with existing tooling without custom code. The data quality monitoring layer alerts on drift — a sudden increase in duplicate rates or format violations — before it corrupts AI outputs.
Stage 7: Live Fuzzy Search API for Real-Time AI Grounding
RAG systems fetch context at query time. If the retrieval layer searches a dirty index, it returns ambiguous or duplicated context even if the underlying database was cleaned last month. Match Data Pro’s live fuzzy search API exposes the clean, deduplicated data layer as a real-time search endpoint. AI agents and RAG pipelines call the API, pass a query term or partial record, and receive ranked, deduplicated matches from the golden record store.
This eliminates a common failure mode: the RAG pipeline retrieves multiple records for the same entity and presents contradictory information to the model, which then synthesises a confident but wrong answer from the conflict.
Practical Examples: Before and After Clean Data Grounding
Example 1: Customer Revenue Query
Scenario: A sales AI assistant is asked “What is Acme’s total contract value this year?”
Before clean data: The RAG system retrieves three records — “Acme Corp” ($120K), “ACME Corporation” ($85K), and “Acme, Inc.” ($95K). The model averages or sums them, producing a figure that is either wrong or three times the actual value.
After entity resolution: All three records resolve to a single golden entity with a consolidated contract value of $120K and a note that the other two records were legacy duplicates now retired. The model returns the correct answer with a single source of truth.
Example 2: Address-Based Territory Routing
Scenario: An AI-powered lead routing agent assigns accounts to territory reps based on verified ZIP code.
Before CASS verification: 12% of records have undeliverable or incomplete addresses. The routing agent assigns them to the wrong territory or returns a null result, requiring manual correction.
After CASS verification: Every address is standardised and DPV-confirmed. The ZIP+4 is present on 97% of records. The routing agent assigns with 97% accuracy and returns null only for genuinely missing data, not data entry errors.
How Match Data Pro Connects to Your AI Stack
Match Data Pro is a cloud SaaS platform with no long-term contract requirement. It connects to your data sources via import connectors, runs the full quality pipeline, and exposes the clean output via export connectors and the live fuzzy search API. The API integrates directly with LangChain retriever chains, custom RAG pipelines, OpenAI function-calling workflows, and agentic orchestration frameworks that call data quality operations as structured tool calls.
For teams that have explored the Model Context Protocol for data quality operations, Match Data Pro’s API surface is compatible with MCP tool schemas, allowing AI agents to call profiling, matching, and entity resolution as first-class operations.
Teams operating in regulated environments can also use Match Data Pro’s clean data approach to AI governance — maintaining audit trails of every transformation and merge decision so that AI outputs are explainable and defensible.
The data quality program framework provides a structured approach for teams building their first clean-data-for-AI initiative, covering governance roles, metric definitions, and tool selection criteria.
Want to see the pipeline in action on your data? Book a demo and we will walk through a live profile of your dataset and show you exactly what the AI layer will receive after the pipeline runs.
Preguntas frecuentes
¿Qué es la calidad de los datos de los modelos de lenguaje grande (LLM) y por qué es importante?
LLM data quality refers to the accuracy, completeness, consistency, and deduplication of the data fed into or retrieved by a language model. It matters because an LLM can only synthesise correct answers from the context it receives. Dirty, duplicated, or inconsistent records produce contradictory context that leads to hallucinated or wrong model outputs, regardless of the model’s capability.
How does deduplication affect RAG pipeline accuracy?
Deduplication directly improves RAG accuracy. When a retrieval system returns multiple records for the same entity, the model receives conflicting facts — different addresses, revenue figures, or status values for what it treats as separate entities. After deduplication, retrieval returns one authoritative record per entity, eliminating the contradiction. In tests on typical CRM data, removing duplicates reduces model answer variance by 30–50%.
Can I connect a live API to my AI workflow instead of running batch cleaning?
Yes. Match Data Pro’s live fuzzy search API lets AI agents query the clean, deduplicated data layer in real time. The agent submits a partial record or search string; the API returns ranked golden record matches. This is the preferred approach for RAG systems that fetch context at query time, because it ensures the retrieved records are always from the deduplicated, standardised store rather than a stale or unprocessed index.
What is entity resolution and how does it help AI workflows?
Entity resolution links records that refer to the same real-world entity across different source systems — CRM, ERP, marketing, support — into a single golden record. For AI workflows, this means a customer, vendor, or product is represented by one authoritative record rather than three to ten fragmented versions across systems. The AI retrieves one complete, consistent context rather than multiple partial and contradictory fragments.
How long does it take to build a clean data foundation for an AI project?
With Match Data Pro, the initial pipeline — profiling, cleansing, deduplication, and entity resolution — runs in hours for datasets under one million records and in one to two days for datasets up to 10 million records. The free trial at members.matchdatapro.com lets you profile and run a first deduplication pass on your own data the same day you sign up, with no contract required.