
Organisations managing more than 100,000 healthcare records every day face a data quality problem that manual processes cannot solve. At that volume, duplicate patient records, unstandardised name formats, and bad addresses accumulate faster than staff can fix them. An automated, stage-by-stage data quality pipeline is the only reliable answer.
If your team is looking at the scale challenge now, book a demo to see how Match Data Pro handles high-volume healthcare record operations.
Why Volume Makes Healthcare Data Quality Harder
A single hospital network may receive data from EHR systems, billing platforms, lab vendors, pharmacies, and insurance carriers. Each source uses different field structures, naming conventions, and address formats. At 100K+ records per day, even a 2% error rate means 2,000 bad records entering your system daily.
Three categories of error dominate:
- Duplicates: The same patient appears in EHR as “Robert Williams” and in billing as “Bob Williams DOB 1971-03-14”. Without fuzzy matching, these stay as two records.
- Format inconsistency: Dates stored as “14/03/1971”, “03-14-71”, and “March 14 1971” across three systems make range queries fail.
- Invalid addresses: Roughly 10–15% of healthcare addresses degrade annually as patients move. Unverified addresses cause returned mail, billing failures, and care coordination gaps.
Scale amplifies every error. A 5% duplicate rate on 500,000 records means 25,000 split patient histories. That is not a data hygiene issue — it is a patient safety issue.
Stage 1: AI Data Profiling at Ingestion
Before any transformation runs, every inbound batch needs a quality baseline. AI data profiling in Match Data Pro scans every field automatically: completeness rates, format distributions, outlier values, and cross-field consistency checks.
A typical profiling output for a 50,000-record batch might show:
- First name: 99.2% populated, 3.4% contain numeric characters (a red flag)
- Date of birth: 12 distinct date formats detected across the dataset
- ZIP code: 6.1% fail a 5-digit or ZIP+4 format check
- Phone: 18.7% missing, 4.2% contain only placeholder values like “0000000000”
Profiling output drives the standardisation rules for the next stage. Without it, standardisation runs blind.
Stage 2: Standardisation Before Matching
Matching on unstandardised data produces unreliable scores. Standardisation must run before any fuzzy comparison begins. The data standardisation pipeline in Match Data Pro handles:
Name Standardisation
Names are the highest-noise field in healthcare. “Dr. Robert J. Williams Jr.”, “Williams, Bob”, and “ROBERT WILLIAMS” all refer to the same person. A name normaliser should:
- Strip titles, suffixes, and punctuation
- Expand known nickname-to-formal name mappings (Bob to Robert, Liz to Elizabeth)
- Convert to a consistent case (uppercase tokens for comparison)
- Separate given name, middle initial, and surname into discrete fields
Date and Phone Standardisation
All date-of-birth values convert to ISO 8601 (YYYY-MM-DD) before any matching runs. Phone numbers strip all non-numeric characters and normalise to a 10-digit national format. Both operations run via configurable transformation rules in the platform’s cleansing engine.
Análisis sintáctico de direcciones
Free-text address fields need to be split into street number, street name, unit, city, state, and ZIP before verification. Parsed components enable more precise fuzzy comparisons and are required for CASS address verification.
Stage 3: CASS Address Verification
CASS (Coding Accuracy Support System) certification is the USPS standard for address validation. Every parsed address runs through the CASS engine, which:
- Confirms the address exists in the USPS delivery point database
- Corrects street name abbreviations (“St” vs “Street”, “Ave” vs “Avenue”)
- Appends the ZIP+4 code for precise geo-targeting and carrier route sorting
- Flags non-deliverable addresses for manual review
In a 100K-record daily batch, expect 8–12% of addresses to receive a correction or flag on first pass. After the initial cleanse, ongoing verification catches the 10–15% annual decay from patient moves. The Match Data Pro address cleansing pipeline runs CASS verification as an integrated step, not a separate workflow.
Stage 4: Fuzzy Matching and Entity Resolution at Scale
With clean, standardised records, the matching engine can run. At 100K+ records per day, brute-force comparison of every pair is computationally impractical. The solution is blocking.
Blocking to Reduce Candidate Pairs
Blocking partitions records into groups where matches are plausible. Common blocking keys for healthcare records:
- First three characters of surname + birth year
- Soundex of surname + ZIP code prefix
- Date of birth + first two characters of given name
Using two or three blocking passes, a dataset of 100,000 records reduces from approximately 5 billion candidate pairs to 2–4 million — a 99.9% reduction in computation load with negligible loss of recall.
Multi-Algorithm Scoring
Each candidate pair receives a composite match score across multiple fields. Match Data Pro’s fuzzy matching algorithms allow you to configure field weights and algorithms per field type:
| Campo | Algoritmo | Peso |
|---|---|---|
| Surname | Jaro-Winkler | 0.30 |
| Given name | Jaro-Winkler + nickname table | 0.20 |
| Fecha de nacimiento | Coincidencia exacta | 0.25 |
| Código postal | Coincidencia exacta | 0.10 |
| Teléfono | Levenshtein (normalizado) | 0.10 |
| Dirección postal | Índice de clasificación de fichas | 0.05 |
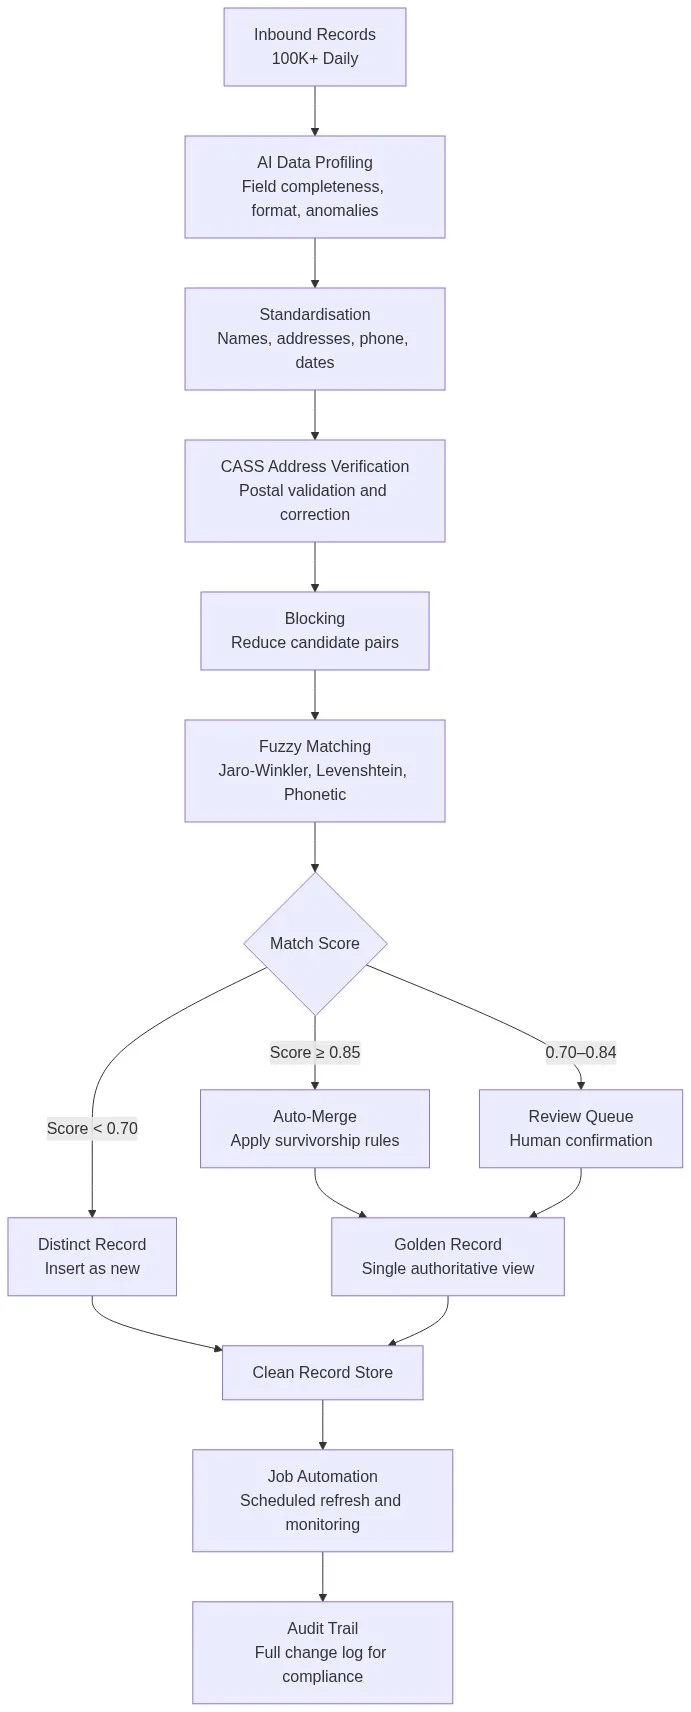
A composite score above 0.85 routes to auto-merge. Scores between 0.70 and 0.84 go to a review queue. Below 0.70, the record is treated as distinct.
Entity Resolution with Senzing
For complex identity scenarios — patients with multiple aliases, changed names, or records spanning decades — Match Data Pro integrates Senzing entity resolution. Senzing uses a pre-trained probabilistic graph model to link records across entity types without hand-crafted rules. It operates in real time, resolving a new record against the existing entity graph in under 100 milliseconds.
Etapa 5: Normas de supervivencia y creación del «Golden Record»
When two or more records merge, survivorship rules determine which field values carry forward to the golden record. Common rules for healthcare data:
- Most recent value: Use the address last updated by the patient’s primary care provider
- Most complete value: Prefer the record with a populated middle name or ZIP+4
- Source priority: Trust EHR data over billing data for clinical fields; reverse for financial fields
- Majority vote: If three sources agree on a phone number and one disagrees, use the majority value
Survivorship rules in Match Data Pro are configured per field and per source, and can be updated without restarting the pipeline. Each merge event writes a full record to the audit trail — showing the source records, the scoring rationale, and the surviving values.
Stage 6: Job Automation and Continuous Monitoring
A one-time cleanse does not solve a 100K-records-per-day problem. Ongoing quality requires scheduled automation. Match Data Pro’s job automation engine lets you:
- Schedule full or incremental matching runs (hourly, nightly, or event-triggered)
- Set quality threshold alerts — trigger a review workflow if duplicate rate exceeds 3% in any batch
- Run automated re-profiling after each batch to track metric trends over time
- Connect to upstream sources via import/export connectors for EHR, billing, and lab systems
Monitoring dashboards surface the key metrics operations teams need: records processed, duplicate rate per batch, address correction rate, auto-merge vs. review queue splits, and golden record coverage.
Healthcare Records Data Quality Pipeline
The diagram below shows the end-to-end flow from inbound records to a clean golden record store with full audit trail:
Operational Benchmarks to Aim For
At 100K+ records per day, well-configured pipelines typically achieve:
| Métrico | Target | What Drives It |
|---|---|---|
| Address correction rate | 8–12% on initial run | CASS verification engine |
| Duplicate detection rate | 90–96% precision | Blocking + multi-algorithm scoring |
| Auto-merge rate | 70–80% of matched pairs | Threshold calibration |
| Review queue size | Under 5% of total volume | Score band tuning |
| Processing latency | Under 4 hours per 100K batch | Parallel blocking passes |
These benchmarks require tuning. The first run establishes a baseline. Match score distributions, false positive rates, and address correction volumes all feed back into threshold and weight adjustments over the first 30–60 days.
Ready to automate your healthcare record operations? Start a free trial of Match Data Pro — no contract, no setup fees, full pipeline access from day one.
Preguntas frecuentes
How do you handle duplicate patient records when names differ significantly?
Fuzzy matching algorithms like Jaro-Winkler and phonetic encoding (Soundex, Double Metaphone) catch near-matches even when names differ by several characters. Nickname expansion tables handle cases like “Bob” versus “Robert”. A composite score across name, date of birth, and address typically achieves 90–96% precision on healthcare records with significant name variation.
What is the difference between deduplication and entity resolution in healthcare?
Deduplication removes exact or near-exact copies within a single dataset. Entity resolution links records across multiple systems — EHR, billing, lab, pharmacy — that refer to the same patient without sharing a common ID. Healthcare operations typically need both: deduplication within each source, then entity resolution to build a cross-system golden record.
How long does it take to process 100,000 records through a full quality pipeline?
With blocking enabled, a well-configured pipeline processes 100,000 records through profiling, standardisation, CASS verification, and fuzzy matching in under four hours. Incremental runs (new records only) often complete in under 30 minutes. Real-time entity resolution via the Senzing integration handles individual records in under 100 milliseconds.
How do you keep the golden record current as patient data changes?
Scheduled incremental jobs re-process only new or modified records since the last run. When a source system updates a patient’s address or phone, the survivorship rules re-evaluate the golden record for that entity and update affected fields. A full re-profile runs nightly to catch format drift and new anomalies across the entire dataset.
Is CASS address verification required for all healthcare records?
CASS verification is not legally mandated, but it is operationally essential for organisations that mail patient communications, file claims, or coordinate care across geographic regions. Unverified addresses generate returned mail, delayed billing, and care coordination failures. CASS certification also qualifies mail for USPS automation discounts, which matters at 100K+ records per day.