
The six data quality issues that cause the most downstream damage are: duplicate records, missing values, format inconsistencies, inaccurate data, invalid addresses, and fragmented entity identity. Fix them in that order of business impact and you eliminate roughly 80% of the errors that corrupt analytics, break integrations, and inflate operational costs.
Most teams have a long list of data quality problems. Very few have a prioritised fix list. Without prioritisation, teams spend engineering cycles on cosmetic issues while high-impact problems continue to poison every downstream system. This guide ranks the issues that matter most and shows the fix for each one.
How to Rank Data Quality Issues by Business Impact
Not every data quality problem deserves equal attention. Before writing a single cleansing rule, run a data profiling pass. Profiling tells you three things: which issues exist, how frequently they appear, and which fields they affect. From that output, score each issue on two axes.
- Frequency: How many records are affected? A 0.1% null rate on a secondary field is a low priority. A 12% null rate on the primary customer identifier is critical.
- Downstream reach: Does this issue affect matching, reporting, compliance, or billing? Issues that touch multiple downstream systems move to the top of the list.
Multiply frequency by downstream reach score (1-5) to produce a priority number. Fix the highest numbers first. This is the same scoring logic that powers the AI data profiling engine inside Match Data Pro, which scans every field and surfaces a ranked issue report before cleansing begins.
The Six Data Quality Issues to Prioritise
1. Duplicate Records
Duplicate records are the highest-impact data quality problem in most enterprise datasets. The average CRM contains a 10-25% duplicate rate. Each duplicate inflates marketing spend, corrupts attribution models, and produces contradictory customer histories.
Consider this example. A sales team runs a campaign and sends 10,000 emails. If 2,500 of those contacts are duplicates, 25% of budget is wasted. Worse, the same contact may receive three separate outreach emails in a week, damaging brand credibility.
The fix requires more than a simple exact-match deduplication run. Real names like “Jon Smith” and “Jonathan Smith at IBM” and “J. Smith, IBM Corp” are the same person. Only fuzzy matching catches those variants. Match Data Pro applies configurable fuzzy algorithms across name, email, phone, and address fields simultaneously, with field-weighted composite scoring to rank match confidence before any merge occurs.
2. Missing Values in Key Fields
Missing values break matching and aggregation. A contact record missing an email address cannot be matched across the CRM and email platform. A product record missing a category code cannot be aggregated in the ERP.
The priority question is: which fields are required for your highest-value downstream process? Map your systems. Any field that feeds a join key, a reporting dimension, or a compliance check is critical. A null rate above 5% in those fields needs an immediate remediation plan.
Remediation options:
- Impute from related fields (derive a postal code from city and state).
- Enrich from a verified external source.
- Flag as incomplete and exclude from downstream processes until resolved.
Match Data Pro’s profiling engine flags every null and blank by field, with percentage and record-count breakdowns, so remediation can be scoped before any fix runs.
3. Format Inconsistencies
Format inconsistencies are the leading cause of false negatives in matching pipelines. The same phone number stored as “212-555-0147”, “2125550147”, and “+1 (212) 555-0147” will not match on an exact join. The same date stored as “11/09/2026”, “09-Nov-2026”, and “2026-11-09” will not sort or filter correctly.
Before any matching or analytics job runs, standardise. Apply format normalisation rules to dates, phone numbers, postal codes, company names, and categorical values. Data standardisation in Match Data Pro covers all common field types with configurable transformation rules, including custom REGEX-based normalisation for unusual formats.
4. Inaccurate and Stale Data
Data that was accurate at entry degrades over time. Research from Dun and Bradstreet indicates business contact data decays at roughly 30% per year. A customer list that was clean 18 months ago may now have 40-45% inaccurate records.
Stale data is harder to fix than format errors because there is no programmatic rule that detects inaccuracy. You need either an external reference dataset to validate against, or a monitored pipeline that alerts when field values stop changing for entities that should be updating. Data quality monitoring tracks freshness metrics across your datasets and raises alerts when drift thresholds are breached.
5. Invalid and Undeliverable Addresses
Address data degrades at approximately 10-15% per year as people move, buildings are renumbered, and postal codes change. Undeliverable addresses waste direct mail spend, break geographic segmentation, and cause compliance failures when physical records need to reach regulated individuals.
The only reliable fix is CASS-certified address verification. CASS (Coding Accuracy Support System) is the USPS standard for validating and correcting postal addresses. Address verification in Match Data Pro runs CASS certification on every record, appends ZIP+4 codes, and flags undeliverable, vacant, and non-existent addresses for removal before they reach a campaign or compliance report.
6. Fragmented Entity Identity
Fragmented entity identity means the same customer, vendor, or provider exists as separate records across multiple systems, with no linking identifier. This is distinct from duplicates within a single system. The same hospital group appears as “Metro Health Group” in the CRM, “Metro Health Grp Inc” in the ERP, and “Metropolitan Health Group LLC” in the billing system. All three refer to the same entity but share no common ID.
Standard deduplication cannot solve this. It requires entity resolution. Match Data Pro embeds Senzing, a graph-based entity resolution engine that probabilistically links records across systems using composite field scoring, without requiring a shared identifier. The result is a persistent entity ID that connects every system record for that entity into a single golden view.
Building a Fix Pipeline That Addresses All Six Issues
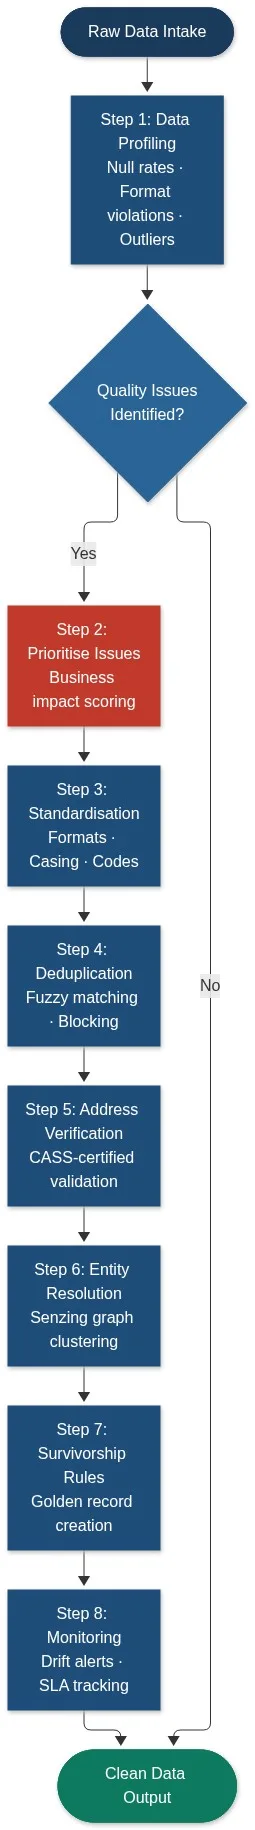
Fixing one issue in isolation creates a new problem. If you deduplicate before standardising formats, you will miss duplicates where the only difference is a format variant. If you verify addresses before resolving entities, you may verify the wrong address for a merged record. The fix order matters.
The correct sequence:
- Profile: Scan every field. Measure null rates, format violations, duplicate estimates, and outliers.
- Standardise: Normalise formats, casing, codes, and categorical values.
- Deduplicate: Run fuzzy matching with blocking and field-weighted scoring to collapse duplicates within each system.
- Verify addresses: Run CASS certification on all postal fields.
- Resolve entities: Link records across systems using graph-based entity resolution (Senzing).
- Apply survivorship rules: Build the golden record from the most reliable field values across all matched records.
- Monitor: Set drift alerts to catch new issues before they accumulate.
Match Data Pro executes this sequence as a single automated job. Import your data via native connectors for Salesforce, HubSpot, SQL databases, CSV, and Excel. Configure the pipeline once. Schedule it to run on a cadence your team defines. Job automation means the pipeline runs without manual intervention, with results exported to your target system automatically.
How to Measure Progress After Fixing Data Quality Issues
Every data quality fix needs a measurable outcome. Without metrics, you cannot demonstrate ROI or detect regression.
Track these metrics before and after each fix run:
- Duplicate rate: Number of duplicates as a percentage of total records. Target: under 2% for CRM data, under 1% for financial records.
- Field completeness: Percentage of records with values in all critical fields. Target: 98%+ for join keys and compliance fields.
- Format compliance rate: Percentage of records meeting standardisation rules. Target: 99%+.
- Address deliverability rate: Percentage of addresses passing CASS verification. Target: 95%+ for active customer datasets.
- Entity match rate: Percentage of cross-system records linked to a golden entity. Track this after entity resolution runs.
The data quality dashboard in Match Data Pro displays all five metrics in real time, with trend charts and threshold alerts so you see regression immediately.
Common Mistakes When Prioritising Data Quality Issues
Fixing symptoms instead of root causes
A high null rate on the email field is often a symptom of a broken data entry form, not a data quality problem. Fix the upstream form validation and the null rate drops automatically. Run root cause analysis on each issue before writing a remediation rule.
Running one-off cleansing instead of continuous pipelines
A one-off cleanse decays within weeks. Business contact data degrades at 30% per year. Without a scheduled data matching and merging pipeline, issues return faster than teams can manually address them.
Starting with the easiest issues, not the most impactful ones
Teams often fix format inconsistencies first because they are technically straightforward. But if the dataset has a 20% duplicate rate, fixing formats without deduplication just produces clean-looking duplicates. Use the business impact scoring framework above to sequence correctly.
Ready to identify and fix your highest-impact data quality issues? Start a free trial of Match Data Pro and run your first profiling and deduplication job in minutes, with no contract required.
Preguntas frecuentes
What are the most common data quality issues?
The most common data quality issues are duplicate records, missing values in key fields, format inconsistencies, stale or inaccurate data, undeliverable addresses, and fragmented entity identity across systems. Duplicate records typically have the highest business impact because they corrupt analytics, inflate costs, and break downstream system joins.
How do I prioritise data quality issues when there are too many to fix at once?
Score each issue on two dimensions: frequency (how many records are affected) and downstream reach (how many systems or processes does this issue corrupt). Multiply the two scores to produce a priority rank. Fix the highest-scoring issues first. Data profiling tools surface this ranking automatically before any cleansing runs.
How often should organisations run data quality checks?
High-volume transactional systems should run quality checks continuously or at minimum daily. CRM and marketing databases should be profiled and cleansed monthly. Static reference datasets such as product catalogues need a quarterly check. Set automated drift alerts so issues surface between scheduled runs.
Can fuzzy matching fix all duplicate record problems?
Fuzzy matching resolves most duplicate problems within a single system by catching name and format variants that exact matching misses. But duplicates that span multiple systems, where records share no common identifier, require entity resolution in addition to fuzzy matching. Use both for complete coverage.
¿Cuál es la diferencia entre la limpieza de datos y la gestión de la calidad de los datos?
Data cleansing is the act of correcting errors in a specific dataset, typically as a one-off or scheduled job. Data quality management is the ongoing programme of profiling, cleansing, monitoring, and governance that prevents issues from recurring. Cleansing is a tactical step inside a broader data quality management programme.