
CRM data hygiene is the ongoing practice of identifying, correcting, and preventing data quality problems inside your customer relationship management system. Poor CRM hygiene is not a cosmetic problem. Duplicate contacts, stale addresses, inconsistent name formats, and blank required fields corrupt every report, pipeline forecast, and segmentation query that touches those records. Fix the data at the source and your analytics, sales ops, and marketing all improve as a direct consequence.
If your dashboards are producing results your team no longer trusts, the most common root cause is the data feeding them. Start with a structured CRM data cleansing audit before optimising any downstream process.
Why CRM Data Degrades Over Time
CRM data has a natural decay rate. Industry benchmarks put it at 20 to 30 percent per year. Contacts change roles. Companies merge. Phone numbers rotate. When new records enter without validation, the decay compounds. A 50,000-contact CRM left untouched for two years can carry 10,000 or more invalid records by conservative estimates.
The main causes of CRM data decay are:
- Manual entry errors — typos in name, email, and phone fields introduced at point of entry
- Format inconsistency — “New York”, “NY”, “New York, NY”, and “new york” all stored in the same state field
- Duplicate creation — web forms, imports, and manual entry each create new records without checking for existing ones
- Stale address data — 11.8 percent of the US population moves each year; CRM addresses go invalid at a parallel rate
- Missing required fields — records imported with partial data that never get completed
Each of these problems is individually correctable. The challenge is that they usually arrive together, compounding each other. A duplicate record with an incorrect address and no job title is three problems, not one.
The Business Cost of Poor CRM Hygiene
Dirty CRM data produces tangible, measurable costs across every team that depends on it.
Sales Operations
Duplicate contacts inflate pipeline counts. A deal that appears three times in the forecast because the same account exists as “Acme Corp”, “Acme Corporation”, and “ACME Corp” throws off every capacity and revenue model. Sales reps spend an estimated 27 percent of their time on data-related tasks instead of selling, according to multiple CRM adoption surveys.
Marketing Segmentation and Campaign Spend
When the same contact receives three copies of the same email because they exist as three records, deliverability scores drop and unsubscribe rates climb. Address hygiene failures cost direct mail campaigns an average of $0.68 per piece returned as undeliverable. At scale, that is tens of thousands of dollars per campaign. The impact of poor marketing data quality on attribution models is equally damaging: duplicate contacts inflate click and open counts, making campaign ROI appear higher than it is.
Analytics and Reporting
Every BI dashboard built on a dirty CRM produces aggregations of dirty data. Churn rate calculations that count the same customer twice, win rate analyses that double-count closed deals, and geographic heat maps built on invalid addresses all lead to decisions based on fiction. Business intelligence initiatives fail without clean, connected data at the foundation.
The 7-Stage CRM Data Hygiene Pipeline
A structured pipeline treats CRM hygiene as an engineering problem, not a manual task. The diagram below shows each stage and how it feeds the next.
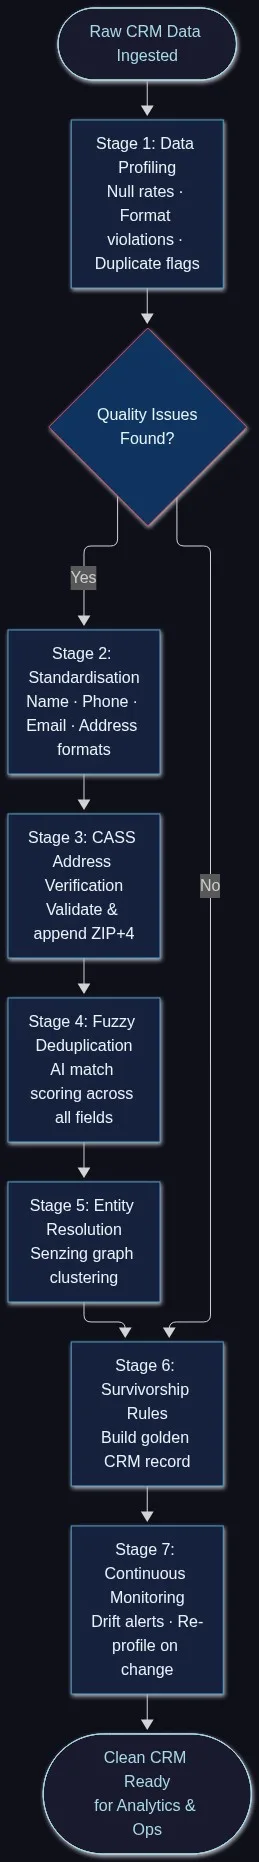
Fase 1: Perfilado de datos
AI-powered data profiling scans every field in your CRM dataset and produces a quality scorecard before any changes are made. The profiling run reports null rates per field, format violation counts, value distribution anomalies, and an initial duplicate flag estimate. For a 100,000-record CRM, a full profile typically completes in under ten minutes on the Match Data Pro platform.
A sample profiling output might look like this:
| Campo | Null Rate | Format Violations | Duplicate Flag Rate |
|---|---|---|---|
| correo electrónico | 12% | 3.2% | 8.4% |
| teléfono | 18% | 21.6% | 6.1% |
| nombre_de_la_empresa | 4% | 0.9% | 14.7% |
| address_line_1 | 22% | 9.3% | 11.2% |
| state | 9% | 16.4% | N / A |
These numbers immediately show where the highest-impact fixes are. In this example, phone format violations (21.6%) and company name duplicate flags (14.7%) are the first priorities.
Fase 2: Normalización
Data standardisation converts every field to a consistent format before matching begins. For a CRM this means:
- Name fields: title-case normalisation, prefix and suffix stripping (“Mr.”, “Jr.”), and nickname-to-canonical expansion (“Bob” to “Robert” for matching purposes)
- Phone fields: strip punctuation, normalise country code, enforce E.164 format (+12025551234)
- Email fields: lowercase, trim whitespace, validate syntax against RFC 5322
- Company names: expand abbreviations (“Corp” to “Corporation”), strip legal suffixes for matching, normalise punctuation
- State and country codes: map free-text values (“New York”, “new york”, “NY”) to a single canonical value
Standardisation before matching reduces false negatives — the missed matches — by 30 to 50 percent, because records that differ only in format now produce identical or near-identical strings for scoring.
Stage 3: CASS Address Verification
CASS-certified address verification validates every postal address against the USPS database, corrects street abbreviations and directionals, and appends the ZIP+4 code for precise delivery-point matching. Address cleansing at this stage catches a class of errors that standardisation alone cannot — wrong street numbers, non-existent suite codes, and cities placed in the wrong state.
A before/after example:
| Antes | After CASS Verification |
|---|---|
| 123 Main st, new york, NY 10001 | 123 Main St, New York, NY 10001-1234 |
| 456 oak ave ste 3b, chicago il | 456 Oak Ave Ste 3B, Chicago, IL 60601-5678 |
| 789 Elm Street, Los Angelos, CA 90210 | 789 Elm St, Los Angeles, CA 90210-4321 |
Stage 4: Fuzzy Deduplication
Once fields are standardised, AI-powered fuzzy matching compares records using weighted composite scores across name, email, phone, company, and address fields. Exact matching alone misses a significant proportion of real duplicates. Consider this pair:
| Campo | Registro A | Disco B | Puntuación |
|---|---|---|---|
| Nombre | Jonathan | Jon | 72 |
| Apellido | Williams | Williams | 100 |
| Correo electrónico | jwilliams@acme.com | j.williams@acme.com | 88 |
| Empresa | Acme Corporation | Acme Corp | 91 |
| Teléfono | +12125550192 | 212-555-0192 | 100 |
| Compuesto | 90 |
An exact join returns zero matches for this pair. A weighted fuzzy composite score of 90 out of 100 flags it correctly as a likely duplicate for review or automatic merge above a configured threshold.
Etapa 5: Resolución de entidades
When the same contact appears across multiple source systems — CRM, marketing automation, support desk, and ERP — entity resolution using Senzing’s graph-based clustering engine links all representations of the same individual or organisation into a single resolved entity. This is where multi-system data hygiene differs from single-system deduplication. Entity resolution handles transitive relationships: if Record A matches Record B, and Record B matches Record C, all three collapse into one entity even if A and C would not have matched directly.
Stage 6: Survivorship Rules
Merging duplicate records requires deciding which field value wins when two records conflict. Survivorship rules define this logic systematically. Common patterns:
- Most recent non-null — use the value from the record modified most recently, as long as it is not empty
- Source system priority — CRM values override import values; ERP addresses override CRM addresses for billing
- Longest populated — the most complete street address field wins over a truncated version
- CASS-verified wins — a verified address always overrides an unverified one regardless of recency
The output of this stage is a golden record — a single authoritative CRM contact with the best available value in every field, a full merge history, and an audit trail showing which source provided each field value.
Stage 7: Continuous Monitoring
A one-time cleanse decays at the same 20–30 percent annual rate as untouched data. Continuous monitoring sets thresholds on key quality metrics — null rate per field, duplicate arrival rate, format violation rate, address bounce rate — and alerts when any metric breaches its threshold. Automated data quality monitoring re-profiles datasets on ingestion and flags drift before it compounds. Match Data Pro’s job automation scheduler runs hygiene jobs on any cadence, from real-time API checks at point of entry to nightly batch runs across the full dataset.
CRM Hygiene for RevOps and Sales Teams
Revenue operations teams depend on CRM data for territory planning, quota setting, and pipeline forecasting. Dirty data breaks each of these. A territory assignment model built on 14,000 unique accounts that is actually 18,500 duplicated records across 14,000 genuine accounts will assign the wrong reps, the wrong quotas, and produce a forecast that is off by the width of that duplicate gap.
The step-by-step guide to deduplicating CRM data covers the specific blocking and scoring configurations that work best for sales records — where company name and phone number are typically higher-weight identifiers than email, because email addresses change with job moves while company name and direct line often persist.
Ready to see the state of your CRM data before committing to a full hygiene project? Start a free Match Data Pro trial and run a profiling job on a sample export from your CRM. The profiling report shows null rates, format violations, and estimated duplicate density within minutes.
Preventing Hygiene Problems at the Point of Entry
Fixing existing dirty data is necessary. Preventing new dirty data from entering is the other half of the problem. Three approaches work in combination:
Real-Time Fuzzy Search at Entry
When a sales rep creates a new contact, a live fuzzy search query checks the existing database for near-matches and surfaces them before the record is saved. If “Jon Williams at Acme Corp” already exists, the system flags it and prompts the rep to link to or update the existing record rather than creating a new one. Match Data Pro’s live fuzzy search API integrates into CRM entry forms and web-to-lead flows to block duplicates at source.
Import Validation Pipelines
Bulk data imports are the single largest source of CRM duplicate creation. A pre-import validation pipeline runs the incoming file through the same profiling, standardisation, and fuzzy matching pipeline before any records reach the CRM. Records that match existing contacts above a configurable threshold are flagged or blocked. Data deduplication in practice works best when applied both to existing records and to every net-new import.
Scheduled Hygiene Jobs
Even with real-time prevention in place, scheduled batch hygiene runs catch problems that slip through — duplicates created in edge cases, addresses that became invalid since the last check, and format violations introduced by third-party enrichment tools. Monthly full-dataset runs with weekly incremental checks on new and modified records is a reasonable cadence for most CRM environments. Match Data Pro’s job automation scheduler handles this without manual intervention.
Want to see how Match Data Pro handles CRM hygiene at scale? Book a live demo and we will walk through a live deduplication and monitoring run on a dataset similar to yours.
Preguntas frecuentes
What is CRM data hygiene?
CRM data hygiene is the ongoing process of profiling, standardising, deduplicating, and verifying customer records in a CRM system to keep them accurate, complete, and usable. It includes both one-time cleansing runs and continuous prevention measures at the point of data entry and import. Without it, CRM data degrades at 20 to 30 percent per year.
How often should I run a CRM data hygiene project?
At minimum, run a full hygiene audit quarterly and a targeted deduplication pass monthly. High-volume CRMs with active import pipelines benefit from weekly or even nightly batch jobs on new and modified records, plus real-time fuzzy matching at the point of entry. The goal is to keep the duplicate rate below 2 percent and the address invalid rate below 5 percent at all times.
What is the difference between data cleansing and data hygiene?
Data cleansing is a point-in-time operation that corrects errors in an existing dataset. Data hygiene is the broader ongoing program that includes cleansing plus prevention measures, monitoring, and governance policies. Cleansing fixes the past; hygiene prevents the future. A mature CRM data program runs both: an initial cleanse to establish a clean baseline, then continuous hygiene to maintain it.
How do I find duplicate records in a CRM without an exact ID match?
Use fuzzy matching across multiple fields with weighted composite scoring. Score name, email, phone, company, and address independently using algorithms suited to each field type (Jaro-Winkler for names, token-based matching for company names, E.164 normalisation before phone comparison). Combine scores into a weighted composite and flag pairs above a threshold (typically 80 to 90 out of 100) for review or automatic merge. Exact ID matching alone misses 15 to 25 percent of real duplicates in typical CRM datasets.
Can I run CRM data hygiene without disrupting live CRM data?
Yes. The standard approach is to export a snapshot, run the full hygiene pipeline on the copy, review the merge proposals and change log, and then apply only the approved changes back to the live system. Match Data Pro’s import and export connectors support this workflow with a full audit trail on every proposed change, so your CRM team can review the results before any record in production is touched.