
Data cleansing and deduplication can run 3 to 10 times faster without any loss in match accuracy — if the right architectural decisions are made before a single record is processed. The bottlenecks are almost always upstream: unindexed fields, serial processing, and unfiltered candidate pair generation. Fix those three things and throughput climbs sharply.
Ready to see how fast your data can run? Start a free trial of Match Data Pro and run your first cleansing job in under 30 minutes.
Why Data Cleansing and Deduplication Slow Down
Speed problems almost always fall into one of four categories.
1. Full Cartesian Comparison
Without blocking, every record is compared to every other record. A dataset of 1 million records produces 500 billion candidate pairs. Even at 1 microsecond per comparison, that is 500,000 seconds of compute time. No pipeline survives that at scale.
2. Serial Stage Execution
When profiling, standardisation, matching, and address verification run one after the other on a single thread, every stage waits for the previous one to finish. Teams with legacy scripts often run this way, and it shows: a 2-million-record job can take 18 to 24 hours.
3. Late-Stage Profiling
Running AI data profiling after cleansing rather than before it means dirty records waste compute cycles going through the full pipeline before anyone knows they are unworkable. Profile first. Discard unfixable records before the expensive stages begin.
4. No Reuse of Prior Results
Reprocessing records that were already matched and verified in the previous job cycle doubles or triples runtime unnecessarily. Incremental processing, where only new and changed records re-enter the pipeline, reduces job run time by 60 to 80 percent for established datasets.
The Six-Stage Pipeline That Balances Speed and Accuracy
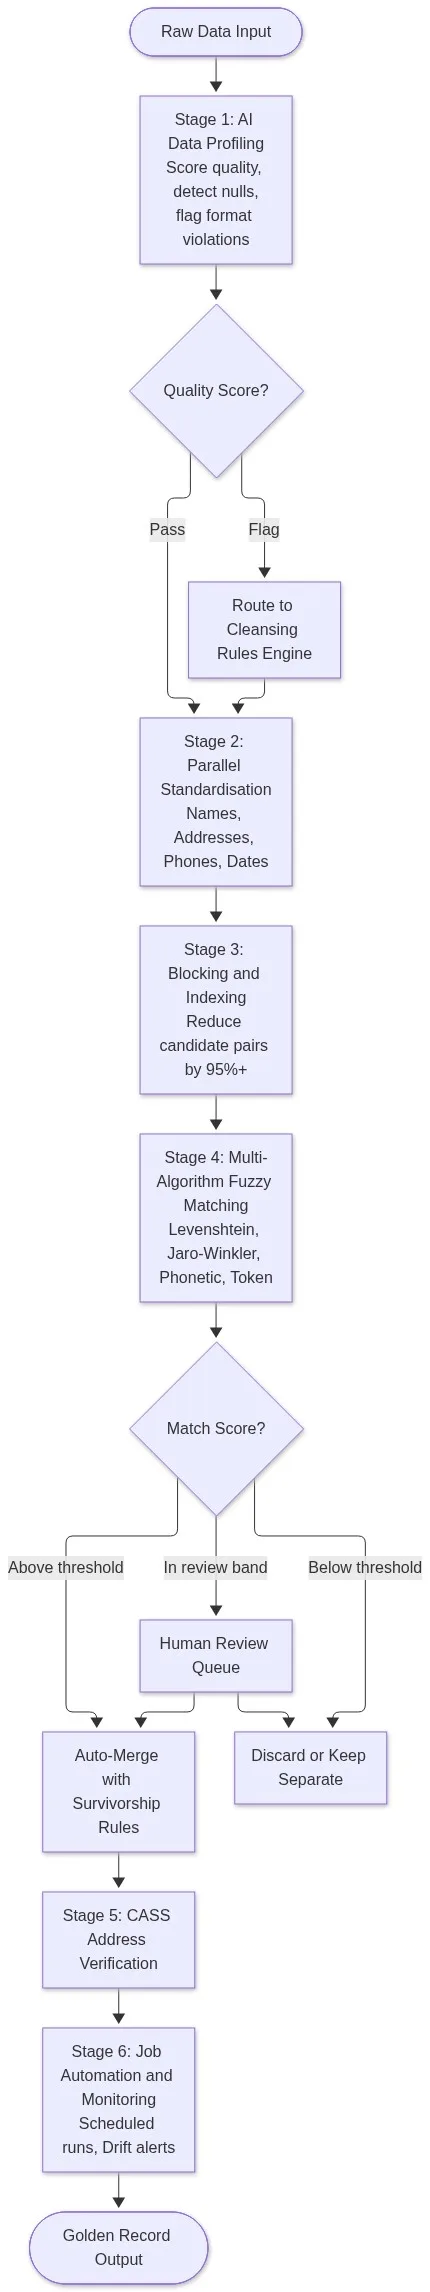
Match Data Pro processes data through six stages, each optimised to avoid the bottlenecks above. The diagram below shows the full flow.
Fase 1: Perfilado de datos para IA
Data profiling runs first on the full dataset, scoring every field for completeness, format consistency, and value distribution. Records that fail minimum quality thresholds route to a lightweight rules engine for quick standardisation or are quarantined. Only quality-scored records proceed to the main pipeline. This alone eliminates 10 to 25 percent of wasted downstream compute.
Stage 2: Parallel Standardisation
Data standardisation normalises name prefixes and suffixes, phone formats, date formats, company abbreviations, and address components simultaneously across parallel worker threads. A job that takes 4 hours on a single thread typically completes in 20 to 40 minutes when field-type standardisation runs in parallel. The key is decomposing the work by field type rather than by record.
Fase 3: Bloqueo e indexación
Blocking is the single biggest speed lever in any deduplication pipeline. Rather than comparing all records to all records, blocking groups records by one or more shared attributes — postal code, first three characters of a surname, or area code — and only compares within groups. A well-designed blocking strategy cuts candidate pair volume by 95 percent or more while retaining 98 to 99 percent of true matches. Match Data Pro supports multi-pass blocking so rare matches that miss one block key still have a second or third opportunity to surface.
Stage 4: Multi-Algorithm Fuzzy Matching
Running a single algorithm is both slower and less accurate than running weighted composites in parallel. Fuzzy matching across name, address, phone, and email fields simultaneously, using Levenshtein for character-level edits, Jaro-Winkler for name transpositions, Soundex for phonetic variants, and token-ratio for company names, produces a composite score in one pass rather than four sequential passes. Composite scoring also reduces false positives, which keeps the human review queue short.
Consider this example. A CRM contains both “Acme Corp, 123 Main St, Chicago IL” and “ACME Corporation, 123 Main Street, Chicago, Illinois 60601”. A single-algorithm approach keyed only on company name scores this pair at 0.71 — below most auto-merge thresholds. A four-field composite score across name (0.88), address (0.93), city (1.0), and state (1.0) produces a weighted score of 0.94. The pair auto-merges without human review.
Stage 5: CASS Address Verification
CASS-certified address verification runs only on records that have passed matching — not on all records. Verifying addresses post-match rather than pre-match reduces the volume that hits the CASS engine by 40 to 70 percent, depending on duplicate rates. Addresses are standardised to USPS format and ZIP+4 codes are appended, which also improves subsequent matching accuracy for any re-runs.
Stage 6: Job Automation and Drift Monitoring
Data quality monitoring and job automation are what turn a one-time cleansing project into a continuously maintained clean dataset. Match Data Pro’s job scheduler runs incremental jobs on user-defined triggers — daily, on ingestion, or on data change events — so duplicates never accumulate to the point where a full re-run is necessary. Drift alerts notify teams when field null rates or format violation rates exceed configurable thresholds.
Blocking Strategies: Where Teams Leave the Most Time on the Table
Blocking deserves its own section because it is the most underused speed optimisation in data quality pipelines. Here are four blocking approaches and when to use each.
| Blocking Method | Lo mejor para | Pair Reduction |
|---|---|---|
| Sorted Neighbourhood | Name-heavy datasets, clean data | 85 to 90% |
| Standard Blocking (exact key) | Datasets with reliable postal codes or area codes | 90 to 97% |
| Canopy Clustering | Large datasets with varied field quality | 92 to 98% |
| Multi-pass Blocking | High-recall requirements, mixed data quality | 93 to 99% |
Multi-pass blocking is Match Data Pro’s default for enterprise jobs. It applies two or three block keys in sequence, flagging any pair that surfaces in at least one pass. This catches transposition errors — “Smith, John” vs “John Smith” — that single-pass approaches miss when sorting alphabetically.
Incremental Processing: The Underestimated Throughput Multiplier
Once a dataset has been fully cleansed and deduplicated, running the full pipeline again on the next refresh cycle is wasteful. Incremental processing isolates the delta — records that are new, modified, or flagged by monitoring — and runs only those through the pipeline. The golden record store retains all previously verified records.
In practice: a 5-million-record CRM dataset might have 50,000 new or modified records per week. A full re-run takes 6 hours. An incremental run on 50,000 records takes 8 minutes. Multiply that by 52 weeks and the cumulative time saving is over 300 hours per year per dataset.
Match Data Pro’s data matching platform supports delta-mode processing natively, with configurable change detection based on record hash, modification timestamp, or ingestion source tag.
Accuracy Safeguards: What Not to Trade Away
Speed gains that compromise accuracy create a different problem: false merges that corrupt golden records and require expensive remediation. Three safeguards must stay in place regardless of how aggressively you optimise throughput.
Threshold Tiering
Do not use a single match threshold across all record pairs. Use three bands: auto-merge above 0.90, human review between 0.75 and 0.90, and auto-reject below 0.75. The review band keeps borderline decisions out of the auto-merge queue without discarding genuine matches. Configuring multi-algorithm scoring thresholds is a core capability in Match Data Pro.
Survivorship Rules
When two records merge, survivorship rules determine which field value wins: most recent, most complete, most frequent, or source-system priority. Without defined rules, merged records can inherit incorrect values from the lower-quality source. The survivorship rules engine in Match Data Pro applies field-level logic, so each field can have its own rule.
Post-Merge Validation
Run a lightweight validation pass after merging. Check that the resulting golden record has no field value that existed in neither source record — a symptom of a rules misconfiguration. Flag any record where the composite score was between 0.88 and 0.92 for a 10 percent random audit. This catches threshold miscalibrations before they propagate at scale.
How Match Data Pro Delivers Both Speed and Accuracy
Match Data Pro is a cloud SaaS platform for complete data quality management. The platform combines AI data profiling, parallel standardisation, configurable blocking, multi-algorithm fuzzy matching, Senzing entity resolution, CASS address verification, survivorship rules, and job automation in one integrated pipeline. No contract. Free trial available.
Teams using Match Data Pro typically see:
- 60 to 80 percent reduction in job run time through blocking and incremental processing
- 40 to 70 percent reduction in false negatives through multi-algorithm composite scoring
- 90 to 96 percent match accuracy on enterprise-scale CRM and ERP datasets
- Human review queues reduced to 3 to 8 percent of total pairs from 15 to 30 percent with single-algorithm approaches
Book a demo to see the pipeline run on a sample of your own data, or register for a free trial and start processing records today.
Preguntas frecuentes
How much can blocking really speed up data deduplication?
Blocking reduces candidate pair volume by 90 to 99 percent depending on the method and dataset characteristics. Without blocking, a 1-million-record dataset produces roughly 500 billion pairs. With a good blocking strategy, that falls to 5 to 50 million pairs — a reduction that cuts compute time from days to minutes while retaining 98 to 99 percent of true matches.
Does running fuzzy matching faster mean lower accuracy?
Not if the speed gain comes from blocking, parallelisation, and incremental processing rather than from loosening thresholds. These architectural changes reduce the work the matching engine does, not the quality of its decisions. Using composite multi-algorithm scoring alongside blocking typically improves accuracy while also improving speed.
What is incremental processing in data deduplication?
Incremental processing runs the deduplication pipeline only on records that are new, modified, or flagged since the last job cycle. Previously verified golden records remain in the store. It reduces weekly job runtime from hours to minutes for established datasets and is the standard operating mode in production Match Data Pro deployments.
How do I know if my blocking strategy is too aggressive?
Run a recall test on a labelled sample: take 1,000 known-match pairs and pass them through your blocking strategy. Count how many pairs survive into the candidate set. If fewer than 97 percent survive, your blocking keys are too restrictive. Add a second pass with a looser key — initial of first name plus city, for example — to recover missed pairs without opening up the full Cartesian space.
Can address verification slow down a deduplication pipeline?
Yes, if it runs on all input records before matching. Verifying every record against a CASS engine — including duplicates — doubles or triples the address API call volume unnecessarily. Run address verification after deduplication, on the golden record set only. This reduces CASS calls by 40 to 70 percent and cuts total pipeline runtime significantly on datasets with high duplicate rates.